The Future of Home Weather Stations: Smart Acoustic Sensors
Explore acoustic smart weather stations revolutionizing forecasting in remote areas. Learn about Aurora's TinyML-powered approach to classifying wind and rain intensity, and its potential global impact on agriculture and accessibility.
Create AI Images with Your Face Using Photomaker - Free and Easy Tutorial
Explore Photomaker to generate AI images featuring your face. Learn installation, Python libraries, and text-prompt techniques for creating personalized, stunning photos effortlessly.
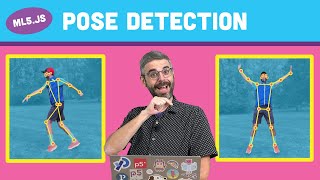
Pose Estimation with ml5.js - Body Tracking and Skeleton Visualization
Explore pose estimation using ml5.js, learning to track body keypoints and visualize skeleton connections with MoveNet and BlazePose models through hands-on coding examples and creative applications.
Gradients for Everyone: A Quick Guide to Autodiff in Julia
Explore automatic differentiation in Julia, comparing approaches with Python frameworks and learning to make code differentiable for various backends. Gain insights into forward and reverse modes, custom rules, and performance optimization.
Docs, CI Tests, Error Messages, and Interfaces in Julia's SciML - JuliaCon 2024
Explore SciML's infrastructure practices in Julia, covering documentation, testing, error handling, and benchmarking. Gain insights into scalable and reproducible numerical ecosystems for Julia developers.
Modern CI/CD Machine Learning Workflows Using Julia
Explore streamlined machine learning workflows in Julia, integrating package development principles and MLflow for robust, reproducible, and scalable model creation and management.
Robot Learning with Minimal Human Feedback
Explore innovative techniques for training robots with minimal human feedback, from single demonstrations to eye gaze, and learn about leveraging pretrained models for efficient robot learning.

Fine-Tuning BERT for Text Classification - Python Code Tutorial
Dive into fine-tuning BERT for text classification, focusing on phishing URL detection. Learn key concepts and implement Python code to enhance your natural language processing skills.
Roblox's Journey to Supporting Multimodality on vLLM - Ray Summit 2024
Explore Roblox's integration of multimodal language models into vLLM, uncovering technical challenges and insights for developers seeking to enhance their LLM deployments with advanced AI capabilities.
Achieving vLLM Platform Portability with Triton Autotuning - Ray Summit 2024
Discover IBM Research's innovative approach to vLLM platform portability using Triton autotuning, enhancing LLM serving with improved cross-platform performance and reduced dependencies.
Databricks' vLLM Optimization for Cost-Effective LLM Inference - Ray Summit 2024
Discover strategies for optimizing vLLM to enhance LLM inference performance, reduce GPU idle time, and accelerate quantization, leading to cost-effective large-scale language model deployment.
Optimizing vLLM for Intel CPUs and XPUs - Ray Summit 2024
Dive into Intel's optimization strategies for vLLM on CPUs and XPUs, exploring technical advancements, performance data, and collaborative efforts to enhance GenAI inference efficiency.
ByteDance's Platform for Reinforcement Learning from Human Feedback
Explore ByteDance's journey in building a video data processing pipeline using Ray's ecosystem for creating realistic video generation models from text instructions.
Uber's Journey in Building Multi-Modal Foundation Models
Dive into Uber's approach to developing in-house multi-modal foundation models, optimizing earner onboarding and screening processes globally using Ray for distributed training and deployment.
Klaviyo's Journey to Robust Model Serving with Ray Serve
Explore Klaviyo's journey in building DART, a model serving platform using Ray Serve. Gain insights into architecture, deployment strategies, and practical advice for implementing Ray Serve in your own projects.
Faster Model Serving with Ray and Anyscale - Ray Summit 2024
Explore Ray Serve's capabilities for distributed model serving and deployment, focusing on Anyscale's solutions for large-scale AI models and the challenges of building AI applications in the era of generative AI.
Fine-Tuning Large Language Models at Scale - Workday's Approach
Dive into Workday's innovative approach to fine-tuning LLMs securely in a multi-tenant environment, addressing GPU scarcity and data access controls using PEFT techniques and KubeRay's autoscaling capabilities.
Using Promptable Image Analysis for Clinical Diagnostics - Ray Summit 2024
Explore the integration of LLMs and Vision Transformers for enhanced clinical image analysis. Discover how Ray technologies enable real-time processing of multimodal data, revolutionizing diagnostic workflows in healthcare.
Scaling Inference Deployments with NVIDIA Triton Inference Server and Ray Serve
Explore the integration of Ray Serve and NVIDIA Triton Inference Server for enhanced ML model performance and scalability. Learn to optimize inference deployments using advanced tools and a new Python API.
Handshake's Approach to Content Tagging with vLLM and Anyscale
Explore Handshake's journey in implementing vLLM-based content tagging using Anyscale, enhancing job feed performance and addressing growing LLM requirements through innovative internal tools and methodologies.
The State of vLLM - Advancements in LLM Inference and Serving
Explore the latest advancements in vLLM, the open-source LLM inference engine. Gain insights into its growing adoption, new features, performance improvements, and future roadmap for efficient LLM deployment.