MLOps MLFlow: Trabajar con Spacy NLP y Entrenar Modelo NER
Aprende a entrenar un modelo NER personalizado utilizando Spacy y MLflow para optimizar el flujo de trabajo de procesamiento de lenguaje natural.
MLOps: Usando Librerías de Python en DotNet - Spacy, Numpy, Pandas
Aprende a integrar librerías Python como Spacy, NumPy y Pandas en aplicaciones .NET utilizando pythonnet, con ejemplos prácticos y código fuente disponible.
NLP Spacy: PII/GDPR Detection with Presidio - Part 2 Code and REST API
Desarrolla una aplicación para detectar información PII/GDPR utilizando Spacy, Presidio, FastAPI y Azure DevOps. Aprende a implementar pipelines de integración y despliegue.
NLP Spacy: PII/GDPR Detection with Presidio - Part 1 Architecture APP
Aprende a desarrollar una aplicación para detectar información regulada por PII y GDPR utilizando NLP Spacy y Presidio. Explora la arquitectura y tecnologías implementadas.
MLOps: Using Python Libraries in DotNet - Spacy, Numpy, Pandas
Integrate Python libraries like Spacy, NumPy, and Pandas into .NET applications using Pythonnet for enhanced machine learning and data science capabilities.
MLOps with MLFlow: Working with Spacy NLP and Training NER Models
Explore Spacy NLP models in MLflow and learn to train a custom NER component using your own data for advanced natural language processing tasks.
Topic Modeling Workshop for Beginners in Python
Learn topic modeling in Python using Gensim, spaCy, and NLTK. Covers data preparation, exploratory analysis, tokenization, LDA modeling, and evaluation techniques for beginners.
Custom NER with spaCy v3 Tutorial - Named Entity Recognition Tutorial
Learn to build custom Named Entity Recognition models using spaCy v3, including data annotation with free tools and training techniques for improved NLP applications.
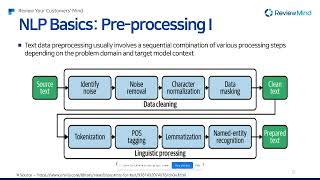
Introduction to NLP and Topic Modeling
Explore NLP basics, advanced techniques like word vectors, and topic modeling. Learn pre-processing, tools, and methodologies to start NLP modeling and understand topic analysis.
NLP Spacy: PII/GDPR Detection with Presidio - Part 2 - Code and REST API
Develop a PII/GDPR detector using Microsoft Presidio and Spacy, implementing a REST API with FastAPI and CI/CD pipelines with Azure DevOps and Docker Compose.
PII/GDPR Detection with Presidio and Spacy - Part 1: Architecture and Design
Explore PII/GDPR detection using Microsoft Presidio and Spacy, focusing on architecture and design for effective data protection implementation.
Building New NLP Solutions with spaCy and Prodigy
Discover strategies to maximize success in NLP projects using spaCy and Prodigy. Learn iterative approaches, avoid common pitfalls, and explore effective workflows for building innovative language processing solutions.
Introduction to Sentiment Analysis with SpaCy
Learn to extract opinions from text using spaCy, covering sentiment analysis basics, topic extraction, and rating consolidation. Includes practical examples in German with English translations.
15 Things You Should Know About Spacy
Discover 15 key insights about spaCy, an open-source NLP library for Python. Learn its strengths, limitations, and practical applications for processing and understanding large text corpora.
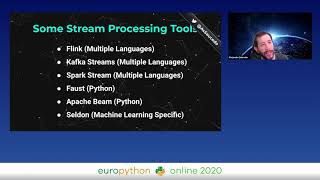
Real Time Stream Processing for Machine Learning at Massive Scale
Practical insights on building scalable data streaming ML pipelines for real-time processing using Python, Kafka, SpaCy, and Seldon. Covers key concepts and best practices through a Reddit comment moderation case study.
Private Data Anonymization with Python - Fundamentals
Explore techniques for anonymizing legal documents using Python, including entity recognition, masking, and pseudoanonymization. Learn to apply AI models and text mining for improved data privacy compliance.
Identify Stocks on Reddit with SpaCy - NER in Python
Learn to extract stock mentions from Reddit using SpaCy's Named Entity Recognition, enabling automated classification and analysis of unstructured text data for financial insights.
Serializing spaCy Doc Containers with DocBin and Pickle
Learn how to efficiently save and serialize spaCy Doc containers using DocBin and Pickle methods for optimized data storage and retrieval in Python.
Coreference Resolution with spaCy and spaCy-Experimental
Master coreference resolution in Python using spaCy-Experimental - implement advanced natural language processing techniques to track and link entity mentions across text.
Named Entity Recognition Tools in spaCy - A Comparison Guide
Master the differences between spaCy's entity recognition tools and learn when to effectively implement NER, EntityRuler, SpanCat, and SpanRuler for optimal text processing results.
SpanCat with spaCy on Real Data - Cultivating Data for Annotation - Part 1
Learn how to implement SpanCat in spaCy for real-world data annotation, focusing on project setup and effective data cultivation techniques for natural language processing.