Learn Your Codebase: Fine-tuning CodeLlama with Flyte to Learn Flyte
Discover how to fine-tune LLMs on specific codebases using Flyte, an open-source orchestration platform. Explore multi-node, multi-gpu distributed training for efficient model adaptation with limited resources.
Inside TensorFlow
Deep dive into TensorFlow's internal workings, covering advanced topics like parameter servers, quantization, debugging, and optimization, presented by the framework's developers.
Amazon SageMaker Technical Deep Dive Series
Comprehensive deep dive into Amazon SageMaker, covering notebook instances, algorithms, custom models, training, deployment, tuning, and advanced features for efficient machine learning workflows.

Deep Learning for Fundamental Sciences Using High-Performance Computing
Exploring deep learning applications in fundamental sciences using high-performance computing to uncover universe secrets and improve discovery sensitivity.
Distributed TensorFlow Training - Google I/O 2018
Learn to scale TensorFlow training across multiple GPUs and machines efficiently. Explore distribution strategies, performance optimization techniques, and practical implementation using Google Cloud.

Scaling Ray Train to 10,000 Kubernetes Nodes on GKE
Discover how to scale distributed machine learning workloads across 10,000 Kubernetes nodes using Ray Train and GKE, featuring architectural insights and practical solutions for massive AI model training.
VeScale - A PyTorch Native LLM Training Framework for Automatic Parallelism
探索PyTorch原生框架veScale,实现大规模语言模型的自动并行训练。结合易用性和性能,助力开发者高效扩展LLM训练,无需复杂并行编程。
Boosting LLM Development and Training Efficiency: Automated Parallelization with MindSpore
Explore automated parallelization for efficient LLM development and training using MindSpore. Learn to optimize distributed training on large-scale clusters without intrusive model modifications, accelerating AI research and implementation.
Efficient Data Parallel Distributed Training with Flyte, Spark and Horovod
Learn to optimize distributed training using Flyte, Spark, and Horovod for efficient data parallelism in machine learning workflows.
Build NLP Model with Azure ML AutoML NLP Capability
Learn to build NLP models using Azure ML AutoML for tasks like classification and named entity recognition. Explore multilingual support, data labeling, and distributed training for efficient model development.
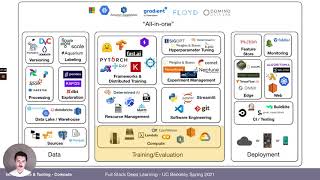
Infrastructure & Tooling - Full Stack Deep Learning - Spring 2021
Comprehensive overview of ML infrastructure and tools, covering software engineering, computing, resource management, frameworks, experiment management, and hyperparameter optimization for practitioners.
Data Science at Uber - Full Stack Deep Learning - August 2018
Explore Uber's data science approach with Jai Ranganathan, covering model lifecycle, customer-centric problem-solving, and practical challenges in AI implementation at scale.
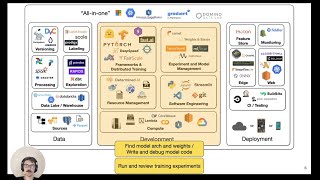
Development Infrastructure & Tooling - FSDL
Comprehensive overview of deep learning development infrastructure, covering software engineering, frameworks, distributed training, GPUs, resource management, and experiment tracking.
PyTorch NLP Model Training and Fine-Tuning on Colab TPU Multi-GPU with Accelerate
Learn to train and fine-tune PyTorch NLP models on Colab TPU using Hugging Face's Accelerate library for efficient multi-GPU/TPU implementation with minimal code changes.
Object Detection with Transformers - From Training to Deployment
Explore cutting-edge object detection using transformers, from fundamental concepts to advanced techniques. Learn scalable training with Determined AI and deployment using MLflow.
Scaling Up AI Research to Production with PyTorch and MLFlow
Explore PyTorch's latest advancements in AI research and production, including distributed training, model optimization, and deployment using MLFlow, with insights on scaling and efficiency.
Generalized Pipeline Parallelism for DNN Training - PipeDream System Overview
Efficient multi-accelerator parallelization for DNN training using PipeDream, combining intra-batch parallelism with inter-batch pipelining to improve throughput and overcome challenges in bi-directional training.
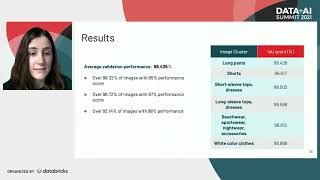
Automated Background Removal Using PyTorch - Wehkamp's Image Processing Pipeline
Discover an automated pipeline for efficient background removal in product images using PyTorch and machine learning, enhancing visual experiences for e-commerce customers.
Machine Learning with Kubernetes
Explore MLOps with Kubernetes: Learn to build scalable ML pipelines using Kubeflow, optimize cluster design, and leverage Istio for enhanced observability and security in production environments.
Accelerating Neural Recommendation Training with Embedding Scheduling
Optimizing deep learning recommendation models through embedding scheduling, reducing communication overhead and improving training performance without compromising accuracy.
Training and Optimisation of Large Transformer Models - An ATLAS and CERN Use Case
Explore CERN's implementation of transformer models for Jet Flavour Tagging, utilizing Kubeflow for machine learning and Katib for hyperparameter optimization in large-scale particle physics data analysis.