A Transformer-Based Framework for Multivariate Time Series Representation Learning
Explore a Transformer-based framework for multivariate time series analysis, covering challenges, model architecture, pre-training, fine-tuning, and applications in classification and forecasting.
Coding RLHF on LLama 2 with LoRA, 4-bit Quantization, TRL and DPO
Master advanced LLM fine-tuning techniques using RLHF, implementing DPO and PPO methods on Llama models with 4-bit quantization and LoRA for optimized performance and human feedback integration.
ORPO: A New Preference-Aligned Training Method for Large Language Models
Explore a groundbreaking reference model-free optimization algorithm for LLM training, comparing ORPO's performance with Llama 2 and Mistral 7B through theoretical physics perspectives.
FASTER Code for Supervised Fine-Tuning and DPO Training with UNSLOTH
Explore practical implementation of UNSLOTH for accelerated Supervised Fine-Tuning and DPO-Alignment of LLMs using Jupyter notebooks with HuggingFace compatibility.
Fine-tuning LLama 2 with PEFT, LoRA, 4-bit Quantization, TRL and SFT
Master advanced LLama2 fine-tuning techniques using PEFT, LoRA, and 4-bit quantization while creating synthetic datasets with GPT-4 for customized model training.
Inside ChatGPT- Unveiling the Training Process of OpenAI's Language Model
Explore the training process behind ChatGPT, including generative pretraining, supervised fine-tuning, and reinforcement learning through human feedback. Gain insights into AI language model development.
Yi 34B: The Rise of Powerful Mid-Sized Models - Base, 200k, and Chat
Explore Yi 34B, a powerful mid-sized AI model. Learn about its performance, versions, and potential applications. Discover insights from AI expert Kai-Fu Lee and see practical demonstrations.
LLaMA 2 and Meta AI Projects - Interview with Thomas Scialom
Insightful discussion with LLaMA 2 lead Thomas Scialom, covering his journey, Meta projects, and the future of AI. Explores key concepts like supervised fine-tuning and human preference in language models.
Fine Tune GPT-3.5 Turbo
Comprehensive guide to customizing GPT-3.5 Turbo for specific use cases, enhancing performance, steerability, and output consistency through fine-tuning techniques.

ORPO: Monolithic Preference Optimization without Reference Model
Innovative approach to language model preference alignment without separate fine-tuning, achieving state-of-the-art performance using odds ratio optimization across various model sizes.
Building the Fine-Tuning Pipeline for Alignment of LLMs
Explore key aspects of aligning LLMs and set up infrastructure for a versatile alignment pipeline. Learn data collection, prompt tuning, and workflow management techniques.
Fine-tuning LLMs with Hugging Face SFT and QLoRA - LLMOps Techniques
Explore advanced LLM fine-tuning techniques, from specialized tuning to instruction enhancement. Learn dataset preparation, model optimization, and leverage powerful libraries for efficient fine-tuning and deployment.
Big Self-Supervised Models Are Strong Semi-Supervised Learners
Explore SimCLRv2, a powerful semi-supervised learning approach combining self-supervised pre-training, fine-tuning, and distillation to achieve state-of-the-art results with minimal labeled data.
Understanding How Llama 3.1 Works - A Technical Deep Dive
Dive into Meta's groundbreaking Llama 3 architecture, exploring pre-training techniques, model capabilities, synthetic data quality, and implementation strategies for advanced AI development.
Customizing Generative AI Models with Vertex AI
Explore Vertex AI's capabilities for customizing foundation models, including supervised fine-tuning and distillation techniques, to enhance performance and create unique AI offerings.
From Research to Production: Fine-Tuning and Aligning LLMs
Learn essential steps for transitioning LLMs to production, focusing on fine-tuning and alignment strategies. Explore Supervised Fine-Tuning, RLHF, and DPO for effective LLM alignment with production goals.
Creating Your Own LLM Tuning Platform with Open Source Technologies
Explore open-source LLM tuning techniques using FMS HF Tuning. Learn architectural integration, various tuning methods, and deployment on Open Data Hub for enhanced AI solutions.
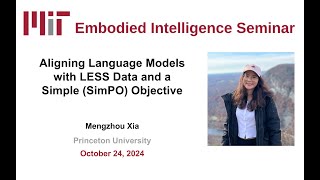
Aligning Language Models with LESS Data and Simple Preference Optimization (SimPO)
Discover innovative approaches to language model alignment through LESS data selection and SimPO optimization, achieving superior performance with reduced computational resources and simplified objectives.
Self-Play Fine-Tuning Converts Weak Language Models to Strong Language Models
Explore a novel fine-tuning method for Large Language Models that improves performance without additional human-annotated data, using self-play mechanisms and theoretical guarantees.
Q-Learning and Hindsight Regeneration for Interactive AI Agents
Explore groundbreaking Q-Learning techniques for AI agents, featuring Hindsight Regeneration and Q-SFT approaches that enhance conversational AI capabilities through advanced reinforcement learning methods.