Aligning Open Language Models - Stanford CS25 Lecture
Explore the evolution of open language models, covering key techniques, datasets, and models like Alpaca and QLoRA. Gain insights into the future of aligning these models for easier use.
Llama2 7B QLora Fine Tuning for Chain-of-Thought in Spanish
Aprende a personalizar el modelo Llama2 7B utilizando QLora para tareas de razonamiento en cadena (CoT) en español. Explora técnicas avanzadas de aprendizaje automático y ciencia de datos.
Llama3 8B QLora Fine Tuning for Chain-of-Thought in Spanish
Aprende a personalizar el modelo Llama3 8B con QLora para tareas de razonamiento en cadena (CoT) en español. Domina técnicas avanzadas de ajuste fino en aprendizaje automático.
MLOps MLflow: Fine-Tuning Mistral 7B con PEFT y QLora - Español
Aprende a ajustar Mistral 7B utilizando técnicas avanzadas como PEFT y QLora, integrando MLflow para un seguimiento eficiente del proceso de fine-tuning.
LLM Quantization Tutorial: QLoRA, GPTQ, and LLama.cpp Implementation for LLama 2
Master LLM quantization techniques and implement efficient model compression using QLoRA, GPTQ, and Llamacpp, with practical guidance for running optimized LLMs locally across different platforms.
Understanding 4-bit Quantization and QLoRA - Memory Efficient Fine-tuning of LLMs
Dive into memory-efficient fine-tuning of large language models through 4-bit quantization and QLoRA, combining theoretical foundations with practical implementation in Colab.

QLoRA: Efficient Training of Large Language Models Using Quantization and Low-Rank Adaptation
Discover how QLoRA enables efficient training of large language models on a single GPU through innovative techniques like NormalFloat, Double Quantization, and Paged Optimizers.
LoftQ: Understanding LoRA-Fine-Tuning-aware Quantization for LLMs
Dive into LoftQ, a groundbreaking LLM quantization method that combines with LoRA to achieve superior performance and efficiency in large language models.
Generative AI and LLM Technologies - A Comprehensive Tutorial
Explore essential concepts and technologies behind generative AI systems, from pre-training and fine-tuning to prompt engineering and advanced data structures for LLMs.
Fine-Tuning LLM with QLoRA on Single GPU - Training Falcon-7b on ChatBot Support FAQ Dataset
Learn to fine-tune Falcon-7b LLM on a custom dataset using QLoRA. Covers model loading, LoRA adapter implementation, fine-tuning, progress monitoring, and performance evaluation on chatbot support FAQs.
Deploy LLM to Production on Single GPU - REST API for Falcon 7B with QLoRA on Inference Endpoints
Learn to deploy a fine-tuned Falcon 7B model with QLoRA to production using HuggingFace Inference Endpoints, creating a REST API for efficient and scalable inference on a single GPU.

Building an LLM Fine-Tuning Dataset - From Reddit Comments to QLoRA Training
Learn to build a QLoRA fine-tuning dataset for language models using Reddit data. Covers data acquisition, processing, structuring, and training sample creation, culminating in QLoRA training and results analysis.

Generative AI: Fine-Tuning LLM Models Crash Course
Comprehensive guide to fine-tuning LLMs using advanced techniques like QLORA and quantization, covering theoretical concepts and practical implementations with popular models like LLama2 and Google Gemma.
Fine-tuning LLMs with Hugging Face SFT and QLoRA - LLMOps Techniques
Explore advanced LLM fine-tuning techniques, from specialized tuning to instruction enhancement. Learn dataset preparation, model optimization, and leverage powerful libraries for efficient fine-tuning and deployment.
Llama2 7B QLora Fine Tuning with Chain-of-Thought Dataset
Fine-tune Llama2 7B model using QLora with chain-of-thought dataset. Learn step-by-step process, access provided notebooks, and explore CodeLlama implementation for enhanced machine learning capabilities.
Llama3 8B QLora Fine-Tuning with Chain-of-Thought Dataset
Fine-tune Llama3 8B model using QLora with chain-of-thought dataset. Learn step-by-step process and access provided notebooks for Llama3, Llama2, and Mistral models.
Local LLM Fine-tuning on Mac (M1 16GB) Using QLoRA and MLX
Fine-tune a local LLM on M1 Mac using MLX and QLoRA. Adapt Mistral 7b to respond like you to YouTube comments, with step-by-step guidance and code examples.
MLOps: Fine-tuning Mistral 7B with PEFT, QLora, and MLFlow
Fine-tune Mistral 7B using PEFT, QLora, and MLFlow techniques. Master advanced LLM optimization for improved performance and efficiency.
Top Ten Tips for Fine-tuning Large Language Models
Discover ten essential tips for effective fine-tuning of language models, from starting small to advanced techniques like LoRA and preference tuning. Gain practical insights for optimal results.
Unlocking Local LLMs with Quantization
Discover how quantization optimizes LLMs for local deployment, from pre-training techniques to fine-tuning methods and inference optimization using cutting-edge approaches and community tools.
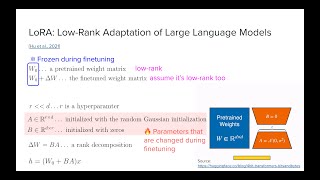
Parameter-Efficient Finetuning - QLoRA and LoRA Methods
Explore parameter-efficient fine-tuning techniques with LoRA and QLoRA, learning how to optimize large language models while maintaining performance and reducing computational costs.