
Federated Hyperparameter Tuning - Challenges, Baselines, and Connections
Explores challenges and solutions for hyperparameter tuning in federated learning, introducing FedEx method to accelerate the process. Connects to weight-sharing in neural architecture search and demonstrates improved accuracy on benchmarks.
Embodiment Without Situatedness - An Embodied Perspective on Neural Architecture Search
Explore embodied perspectives on neural architecture search with Nick Cheney, examining the intersection of neurorobotics and complex systems in AI development and intelligence research.
MCUNet and TinyML - Lecture 10
Explore MCUNet and TinyML for efficient machine learning on microcontrollers. Learn optimization techniques and real-world applications in resource-constrained environments.
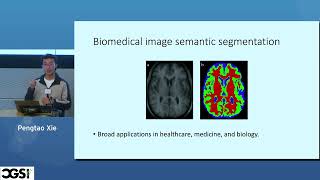
Training Highly Generalizable Biomedical Image Segmentation Models with Very Few Annotations
Learn highly generalizable biomedical image segmentation techniques using minimal annotations, focusing on efficient model training and performance optimization for medical imaging tasks.
Synthetic Petri Dish - A Novel Surrogate Model for Rapid Architecture Search
Explore a novel approach to Neural Architecture Search using a Synthetic Petri Dish model, which evaluates architectural motifs in small networks with synthetic data to accelerate performance prediction and optimization.
Using AI to Design Energy-Efficient AI Accelerators for the Edge
Explore AI-driven co-design of neural networks and hardware accelerators for edge devices, optimizing accuracy and efficiency through simultaneous architecture and hardware space exploration.
EfficientNetV2 - Smaller Models and Faster Training - Paper Explained
Explore EfficientNetV2's improved image classification performance, including progressive training, Fused-MBConv layer, and novel reward function for Neural Architecture Search.
Parameter Prediction for Unseen Deep Architectures - With First Author Boris Knyazev
Explore parameter prediction for neural networks using graph hypernetworks. Learn about DeepNets-1M dataset, training techniques, and experimental results for efficient network training paradigms.
Neural Architecture Search Without Training - Paper Explained
Explores a novel approach to Neural Architecture Search using statistics of the Jacobian around data points, enabling rapid architecture evaluation without training and significantly accelerating the search process.
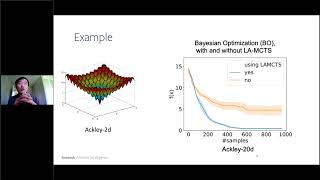
Learning to Optimize High Dimensional Optimization Problems
Explore deep neural networks and reinforcement learning for solving high-dimensional optimization problems, improving performance in job scheduling, neural architecture search, and black-box optimization.
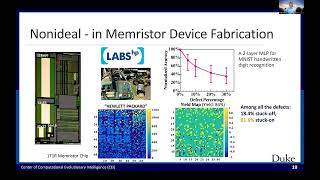
TinyML Talks - Software-Hardware Co-design for Tiny AI Systems
Explore efficient AI models, hardware-friendly compression, and topology-aware design for resource-constrained systems. Learn cross-optimization techniques and distributed learning for scalable AI solutions.
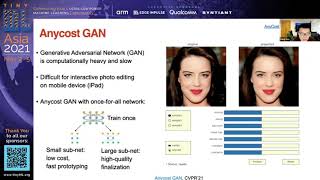
Putting AI on a Diet: TinyML and Efficient Deep Learning
Efficient deep learning techniques for deploying AI on resource-constrained devices, including model compression, neural architecture search, and new design primitives for various applications.
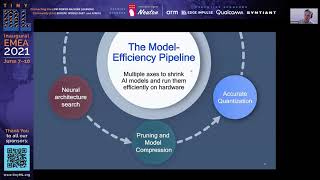
The Model Efficiency Pipeline: Enabling Deep Learning Inference at the Edge
Explore optimizing deep learning for edge devices through model efficiency techniques, including neural architecture search, pruning, quantization, and conditional processing.
Hyperparameter Tuning Using Kubeflow
Explore automated machine learning with Katib, a Kubernetes-native platform for hyperparameter tuning and neural architecture search, enhancing model performance efficiently.
A Bregman Learning Framework for Sparse Neural Networks
Explore a novel Bregman learning framework for training sparse neural networks, featuring LinBreg, momentum-accelerated, and AdaBreg algorithms, with applications in Neural Architecture Search.

AutoML and Training Working Group Updates - Kubeflow Developments
Explore AutoML and Training Working Group updates for Kubeflow, including Katib's V1 API graduation, advanced parameter distribution, and LLM tuning, plus Training Operator's roadmap for enhanced ML framework support.
Neural Architecture Search: Coming of Age
Explore Neural Architecture Search advancements, including benchmarks, speedup techniques, AutoML integration, and neural ensemble search. Gain insights from a leading expert in automated machine learning.
Deep Learning for Mobile Devices
Strategies for implementing efficient convolutional neural networks on mobile devices, covering model optimization, hardware considerations, and on-device training techniques.
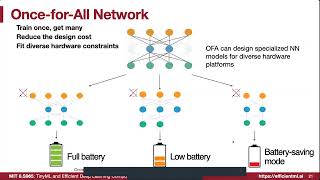
TinyML and Efficient Deep Learning Computing - Course Summary
Explore efficient machine learning techniques for deploying neural networks on resource-constrained devices, covering model compression, pruning, quantization, and more.
TinyML and Efficient Deep Learning Computing - Lecture 24: Course Summary
Explore efficient machine learning techniques for deploying neural networks on resource-constrained devices. Gain hands-on experience with mobile AI and quantum machine learning.
SpineNet - Learning Scale-Permuted Backbone for Recognition and Localization
Explores SpineNet, a novel CNN architecture using scale-permuted features and cross-scale connections, outperforming traditional models in object detection and classification tasks.