Understanding Deep Learning Requires Rethinking Generalization
Explore deep learning generalization, examining regularization techniques, randomization tests, and neural network expressivity to challenge conventional understanding and improve model performance.
Beyond Lazy Training for Over-parameterized Tensor Decomposition
Explore over-parameterization in tensor decomposition, comparing lazy training and gradient descent approaches. Discover how gradient descent can leverage low-rank data structure beyond lazy training regimes.
Training More Effective Learned Optimizers, and Using Them to Train Themselves - Paper Explained
Explores a novel approach to machine learning optimization using neural networks, discussing its architecture, training process, and potential to revolutionize model training through self-improvement and generalization.
Generalization in Deep Learning Through the Lens of Implicit Rank Minimization
Explores implicit regularization in deep learning through matrix and tensor factorizations, revealing tendencies towards low ranks. Discusses implications for generalization and potential improvements in neural network design.
Benign Overfitting - Peter Bartlett, UC Berkeley
Explore benign overfitting in machine learning, focusing on linear regression, deep networks, and statistical implications. Gain insights into effective rank, regularization, and future research directions.
Big Data Is Low Rank - Madeleine Udell, Cornell University
Explore big data's low-rank structure, generalized low-rank models, and their applications in machine learning. Learn about dimensionality reduction, autoML, and latent variable models for efficient data analysis.
Implicit Regularization I
Explore implicit regularization in deep learning, covering boosting, complexity control, optimization landscapes, and stochastic gradient descent for effective model training.
Implicit and Explicit Regularization in Deep Neural Networks
Explores implicit and explicit regularization in deep neural networks, connecting learning algorithms to H-infinity control and explaining convergence behavior in over-parametrized models, offering insights into generalization abilities.
Implicit Regularization II
Explore implicit regularization in deep learning, focusing on advanced concepts and their impact on model performance and generalization.
Implicit Regularization for General Norms and Errors - Lorenzo Rosasco, MIT
Explores implicit regularization in optimization methods, focusing on stability in estimation processes for non-Euclidean norms and non-quadratic errors, with emphasis on accelerated techniques.
Random Initialization and Implicit Regularization in Nonconvex Statistical Estimation - Lecture 2
Explore nonconvex optimization in statistical estimation, focusing on gradient descent's convergence to optimal solutions without explicit regularization or careful initialization.
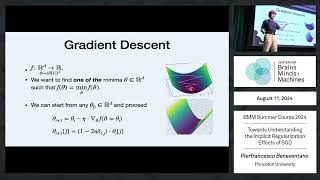
Towards Understanding the Implicit Regularization Effect of SGD
Explore the implicit regularization effect of Stochastic Gradient Descent, uncovering its impact on optimization and generalization in machine learning models.