GUITAR: Gradient Pruning toward Fast Neural Ranking - Efficiency for Search
Explore gradient pruning techniques for optimizing neural ranking models, enhancing search efficiency and performance.
Leaner, Greener and Faster PyTorch Inference with Quantization
Explore PyTorch quantization techniques to optimize neural networks, reducing size and improving speed without sacrificing accuracy. Learn implementation strategies and real-world applications.
A Gentle Introduction to Sparsity with a Concrete Example
Explore sparsification techniques for ML models, including popular methods and a concrete example to understand their benefits.
MCUNet and TinyML - Lecture 10
Explore MCUNet and TinyML for efficient machine learning on microcontrollers, covering design principles and real-world applications in resource-constrained environments.
MCUNet and TinyML - Lecture 10
Explore MCUNet and TinyML for efficient machine learning on microcontrollers. Learn optimization techniques and real-world applications in resource-constrained environments.
Self-Improving Teacher Cultivates Better Student: Distillation Calibration for Multimodal Large Language Models - Lecture 3.3
Explore innovative distillation calibration techniques for multimodal large language models, focusing on self-improving teacher methods to enhance student model performance.
Optimizing vLLM Performance Through Quantization - Model Compression Techniques
Discover practical techniques for model quantization in vLLM deployments, exploring FP8, INT8, and INT4 methods to enhance performance and reduce memory usage while maintaining efficiency.
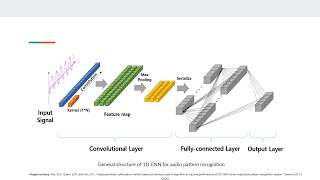
Leveraging Pruning and Quantization for Efficient Real-Time Audio Applications
Explore pruning and quantization techniques to enhance efficiency of complex audio models for real-time processing in resource-constrained environments. Gain insights into model compression for audio applications.
LLMOps: Quantization Models and Inference with ONNX Generative Runtime
Explore ONNX runtime GPU support for inference with generative models, including Phi3-mini quantization and conversion techniques.
Lightweight Deep Learning on Edge Devices - Energy Efficient Approaches
Discover efficient deep learning techniques for edge devices, focusing on energy-saving approximation methods that maintain accuracy while improving performance on smartphones and IoT devices.

LLM Deployment Techniques - Lecture 13
Dive into advanced LLM deployment strategies, covering optimization techniques, infrastructure scaling, and practical implementation methods for efficient large language model deployment.

EfficientML.AI - Introduction to Efficient Machine Learning
Master efficient machine learning techniques and optimization strategies for deploying ML models in resource-constrained environments, focusing on practical implementation methods.
LLM Deployment Techniques - Lecture 13
Dive into advanced LLM deployment strategies, covering optimization techniques, infrastructure scaling, and practical implementation methods for efficient large language model deployment in production environments.
LLM Quantization Tutorial: QLoRA, GPTQ, and LLama.cpp Implementation for LLama 2
Master LLM quantization techniques and implement efficient model compression using QLoRA, GPTQ, and Llamacpp, with practical guidance for running optimized LLMs locally across different platforms.
GGUF Quantization of Large Language Models Using LLAMA.cpp
Master GGUF quantization techniques to run large language models efficiently on personal devices using LLAMA.cpp, enabling GPU-free inference and deployment on laptops, phones, and watches.
In-SRAM Computing for Generative AI and Large Language Models
Explore innovative In-SRAM computing architecture and its role in reducing power consumption for large language models and generative AI in datacenter environments.

Quantization in Deep Learning: Types, Algorithms, and Implementation
Explore quantization techniques in deep learning, from uniform to non-uniform approaches, and learn practical implementation strategies for optimizing large-scale neural networks.
Simple Quantization of LLMs - A Hands-on Guide to Absolute Max and Zero Point Methods
Master practical LLM quantization techniques through hands-on implementation of Absolute Max and Zero Point methods, building foundational skills for advanced approaches like GPTQ and AWQ.
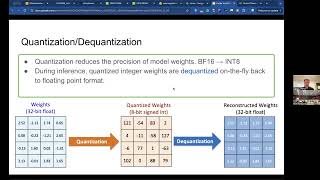
Faster and Cheaper LLMs with Weight and Key-value Cache Quantization
Explore advanced techniques for optimizing Large Language Models through weight and key-value cache quantization methods to improve speed and reduce computational costs.
On-Device Training Under 256KB Memory
Discover cutting-edge techniques for on-device machine learning training with minimal memory requirements, presented by MIT's Song Han in this technical seminar on resource-efficient AI deployment.
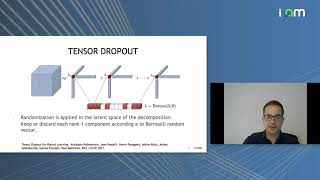
Efficient Tensor Representation for Deep Learning with TensorLy and PyTorch
Explore tensor methods for deep learning, improving performance, speed, and robustness. Learn practical implementation using TensorLy-Torch for video and image classification tasks.