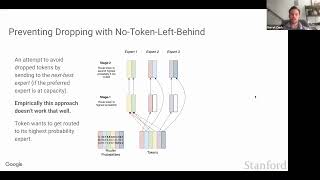
Stanford Seminar - Mixture of Experts Paradigm and the Switch Transformer
Explore the Mixture of Experts paradigm and Switch Transformer, revolutionizing deep learning with sparsely-activated models for improved efficiency and performance in language processing tasks.
Unsupervised Cross-Domain Image Retrieval with Semantic-Attended Mixture-of-Experts
Explore unsupervised cross-domain image retrieval using semantic-attended mixture-of-experts, enhancing retrieval accuracy across diverse visual domains.
When MOE Meets LLMs: Parameter Efficient Fine-tuning for Multi-task Medical Applications - Lecture 1
Explore parameter-efficient fine-tuning techniques for multi-task medical applications using Mixture of Experts and Large Language Models.
Understanding Snowflake Arctic 480B - A Mixture of Experts LLM Architecture
Dive into the architecture and performance analysis of Snowflake's Arctic 480B LLM, exploring how its 128x4B MoE design compares to traditional transformers for enterprise-level AI tasks.
LLM Prompt Formatting: Optimizing Performance for Language Models and RAG Systems
Master the critical impact of prompt formatting on LLM and RAG system performance, exploring optimization techniques and understanding how different formats influence AI model responses.
Supercharging Multi-LLM Intelligence with CALM - Composition to Augment Language Models
Discover how CALM (Composition to Augment Language Models) revolutionizes multi-LLM integration through advanced projection layers and cross-attention mechanisms for enhanced AI capabilities.
Mixture of Experts (MoE) in Large Language Models - A Simple Guide
Delve into the architecture and functionality of Mixture of Experts (MoE) systems in language models through clear examples and technical insights about token routing, gating networks, and computational efficiency.
Modules and Architectures
Explore non-linear functions, cost functions, and advanced architectures like multiplicative interaction and mixture of experts in deep learning, with insights from expert Yann LeCun.
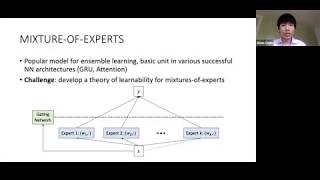
Learning Mixtures of Linear Regressions in Subexponential Time via Fourier Moments
Explore efficient algorithms for learning mixtures of linear regressions using Fourier moments, overcoming previous barriers and achieving subexponential time complexity.
Developing and Serving RAG-Based LLM Applications in Production
Learn to develop, evaluate, and scale RAG-based LLM applications for production, including advanced topics like hybrid routing to bridge the gap between open-source and closed LLMs.
Microsoft's Phi 3.5 - Latest Small Language Models Overview
Explore Microsoft's latest Phi 3.5 models, including Mini, MoE, and Vision variants. Learn about their capabilities, performance, and practical applications through demonstrations and code examples.
AutoMoE - Neural Architecture Search for Efficient Sparsely Activated Transformers
Discover how Neural Architecture Search optimizes Transformer models through sparse activation, achieving 4x FLOP reduction while maintaining performance in machine translation tasks.
Mixture-of-Supernets - Improving Weight-Sharing Supernet Training with Architecture-Routed MoE
Explore cutting-edge research on Mixture-of-Supernets architecture that enhances neural architecture search efficiency and improves BERT and MT model performance through innovative weight-sharing techniques.
Building Intelligent Systems with MoE, Multimodality, and Crowd of Agents
Explore advanced AI systems using MoE, multimodality, and agent crowds. Learn techniques for building composite intelligent systems beyond single algorithms or models.
Unlocking Mixture of Experts - From One Know-it-all to a Group of Jedi Masters
Explore Mixture of Experts technique to enhance predictive powers. Dive into principles, challenges, and applications. Learn when to use MoE, discuss business metrics, and access resources for implementation.
GenAI in Production - Challenges and Trends - Lecture 224
Explore challenges and trends in Generative AI production, including model size, context windows, multimodality, and regulation. Gain insights from Gemini 1.0 vs 1.5 comparisons and industry expert Verena Weber's experiences.

LLaMA 3 Deep Dive - Synthetic Data, Privacy, and Model Architecture
Explore LLaMA 3's innovations with Meta's Thomas Scialom, covering synthetic data, privacy concerns, scaling techniques, and architectural choices in this in-depth discussion on advanced language models.
Pioneering a Hybrid SSM Transformer Architecture - Jamba Foundation Model
Explore AI21 Labs' Jamba: a groundbreaking hybrid Transformer-Mamba MoE model with unparalleled throughput and a 256K context window, revolutionizing large language model development.

GShard- Scaling Giant Models with Conditional Computation and Automatic Sharding
Detailed explanation of Google's 600 billion parameter transformer for multilingual translation, focusing on scaling techniques, mixture-of-experts, and automatic sharding implementation on TPUs.
Pre-training Mixtral MoE Model with SageMaker HyperPod - Fine-Tuning and Continued Pre-Training
Master advanced techniques for pre-training and fine-tuning Mixtral MoE models using AWS SageMaker HyperPod and SLURM, covering implementation strategies and continued pre-training approaches.
OpenMoE: An Early Effort on Open Mixture-of-Experts Language Models
Explore OpenMoE, an open-source Mixture-of-Experts language model series. Discover its cost-effectiveness, routing mechanisms, and key insights in comparison to dense LLMs.