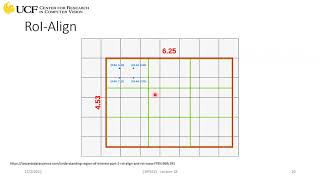
Instance Segmentation - Lecture 26
Explore instance segmentation in computer vision, covering Mask R-CNN, ROI pooling, and alignment techniques for precise object detection and pixel-level classification.
Leaner, Greener and Faster PyTorch Inference with Quantization
Explore PyTorch quantization techniques to optimize neural networks, reducing size and improving speed without sacrificing accuracy. Learn implementation strategies and real-world applications.
Quantized Optimal Transport Reward-based Reinforcement Learning Approach to Detoxify Query Auto-Completion - Lecture 1
Explore a novel reinforcement learning approach for detoxifying query auto-completion using quantized optimal transport rewards.
MCUNet and TinyML - Lecture 10
Explore MCUNet and TinyML for efficient machine learning on microcontrollers. Learn optimization techniques and real-world applications in resource-constrained environments.
Databricks' vLLM Optimization for Cost-Effective LLM Inference - Ray Summit 2024
Discover strategies for optimizing vLLM to enhance LLM inference performance, reduce GPU idle time, and accelerate quantization, leading to cost-effective large-scale language model deployment.
Real-Time Digital Signal Processing Laboratory Course
Comprehensive video series on real-time digital signal processing, covering DSP architecture, filters, modulation techniques, and communication systems. Includes lectures and homework discussions for hands-on learning.
Gauge Theory and the Analytic Approach to Geometric Langlands - Edward Witten
Explore gauge theory's role in geometric Langlands correspondence, comparing categorical and analytic approaches through quantum states, operators, and gauge theory interpretations.
Optimizing vLLM Performance Through Quantization - Model Compression Techniques
Discover practical techniques for model quantization in vLLM deployments, exploring FP8, INT8, and INT4 methods to enhance performance and reduce memory usage while maintaining efficiency.
The Completion of the Space of Lagrangian Submanifolds for the Spectral Metric
Explore the spectral metric on Lagrangian spaces, its completion, and connections to symplectic topology and sheaf theory through quantization.
MLOPS LLMs: Converting Microsoft Phi3 to GGUF Format with LLaMA.cpp
Aprende a cuantizar el modelo Microsoft Phi3 a formatos bf16, fp16 o q8_0 utilizando LLaMA.cpp para optimizar el rendimiento de LLMs.
MLOPS LLMs - Converting Microsoft Phi3 to GGUF Format with LLaMA.cpp
Aprende a cuantizar el modelo Phi3 mini a diferentes tipos de datos utilizando LLama.cpp para optimizar el rendimiento y la eficiencia.
MLOps with MLFlow: Comparing Microsoft Phi3 Mini 128k in GGUF, MLFlow, and ONNX Formats
Explora el modelo Phi3 Mini 128k en formatos MLFlow, GGUF y ONNX. Compara rendimiento y precisión en diferentes configuraciones. Aprende a implementar y optimizar modelos de lenguaje para diversas plataformas.
AirLLM: Inferencia de LLM de 70 Billones de Parámetros en GPU de 4GB - Español
Aprende a realizar inferencia con un LLM de 70 billones de parámetros en una GPU doméstica de 4GB usando AirLLM. Explora técnicas avanzadas de machine learning y optimización de recursos.
Visual Studio Code AI Toolkit Introduction - Data Science and Machine Learning
Explora el Visual Studio Code AI Toolkit con ejemplos prácticos en Python y C# para inferencia en CPU usando el modelo Phi 3 4K Instruct cuantizado.
LLMOps: Como usar Nvidia TensorRT SDK para Inferencia en GPU
Optimiza la inferencia en GPU con Nvidia TensorRT SDK, convirtiendo modelos y comparando tiempos de ejecución en diferentes precisiones de datos.
LLMOps: Comparación de Openvino, ONNX, TensorRT y Pytorch para Inferencia
Compara el rendimiento de inferencia de modelos convertidos a ONNX, OpenVino y TensorRT frente a PyTorch nativo en GPU y CPU.
MLOPS: Object Detection con Faster RCNN en C# Formato ONNX en CPU
Desarrolla una aplicación de detección de objetos en C# utilizando Fast RCNN, ONNX y CPU para inferencia eficiente.
LLMOPs: Inferencia en CPU con Phi3 Vision 128k Instruct - ONNX 4bits en C#
Aprende a realizar inferencia en CPU con Phi 3 Vision 128K Instruct, utilizando modelos ONNX de 4 bits y C# para prompts multimodales eficientes.
LLMOPs - Inferencia en CPU con Phi3 4k Instruct ONNX 4bits en C#
Aprende a realizar inferencia en CPU con Phi 3 4K Instruct cuantizado a 4 bits en ONNX usando C#, optimizando el rendimiento de modelos de lenguaje.

The Unreasonable Effectiveness of JPEG: A Signal Processing Approach
Explore the mathematical foundations and signal processing insights behind JPEG compression, including color spaces, discrete cosine transform, and quantization techniques for efficient image encoding.
Models on the Move: Towards Feasible Embedded AI for Intrusion Detection on Vehicular CAN Bus
Innovative AI model for efficient intrusion detection on vehicular CAN bus, enhancing automotive cybersecurity with high accuracy and low latency using FPGA hardware acceleration.