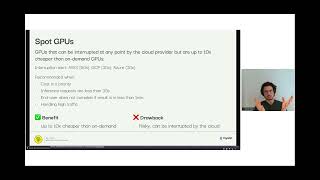
Running Multiple Models on the Same GPU on Spot Instances
Optimize ML inference costs through GPU fractionalization and Spot instances. Increase GenAI application throughput while reducing expenses.
Scaling LLM Inference - AWS Inferentia Meets Ray Serve on EKS
Discover how to build scalable, cost-effective LLM inference infrastructure using Ray Serve and AWS Inferentia on Amazon EKS, optimizing deployment of models like Llama2 and Mistral-7B.
Deep Learning Neural Network Acceleration at the Edge
Explore neural network acceleration for edge computing, covering frameworks, formats, and hardware solutions. Learn about efforts to consolidate technologies and enable innovation in intelligent devices.
Inference on KubeEdge
Explore KubeEdge for efficient edge computing inference with Adrian Gonzalez-Martin from Seldon. Learn about deploying and managing machine learning models at the network edge.
The Hitchhiker's Guide to Kubernetes Platforms - Building AI Development Platforms
Explore building a robust AI platform on Kubernetes, featuring modular APIs for efficient management and deployment. Learn from Bloomberg's implementation using open-source projects as guides.
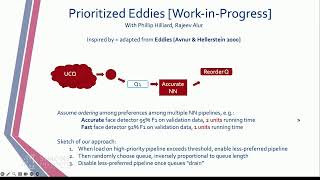
Deep Learning and the Relational Algebra
Exploring the integration of machine learning inference in query processing, including tensor operations and autograd in relational algebra, with insights from early research experiences.
Serverless for ML Inference on Kubernetes - Panacea or Folly
Explore serverless ML inference on Kubernetes: performance, costs, and architecture. Gain insights from benchmarking experiments to optimize your ML inference system.
Using Python to Power Serverless Applications
Explore best practices for building serverless solutions with Python, focusing on API calls, streaming data, and ML inference. Learn techniques for production-grade systems with observability.
TensorFlow Lite - Solution for Running ML On-Device
Explore TensorFlow Lite for efficient on-device ML inference, featuring low latency, high performance, and small binary size. Learn about mobile BERT, support libraries, and microcontroller applications.
Faster Inference Using Output Predictions with OpenAI and vLLM
Master advanced inference techniques for faster AI model outputs using OpenAI predictions and vLLM speculative decoding, with practical demonstrations and cost optimization strategies.