
Building a Music Recommendation Engine
Learn to build a music recommendation engine using AudioSet dataset, embedding generation, and ANNOY algorithm. Hands-on coding and practical implementation for personalized music suggestions.
Neural Search Improvements with Apache Solr 9.1 - Approximate Nearest Neighbor and Pre-Filtering
Explore neural search in Apache Solr 9.1, including HNSW graph improvements, pre-filtering capabilities, and Deep Learning integrations for enhanced search relevance and efficiency.
Milvus - Accelerating Approximate Nearest Neighbor Search for Large Scale Datasets
Explore techniques to accelerate Approximate Nearest Neighbor Search for large datasets using Milvus. Learn about unstructured data services, vector databases, and real-world AI applications.
The Rise of Vector Databases - Lessons from the Milvus Community
Explore vector databases, their rise in managing unstructured data, and insights from Milvus. Learn about embeddings, production use cases, challenges, and future developments in this emerging field.
Locality Sensitive Hashing for Search with Shingling + MinHashing - Python
Learn efficient similarity search using Locality Sensitive Hashing (LSH) with shingling and MinHashing techniques in Python. Explore implementation steps, from data preprocessing to LSH tuning, for approximate nearest neighbor search.
Private Nearest Neighbor Search with Sublinear Communication and Malicious Security
Explore secure and efficient private nearest neighbor search techniques, focusing on sublinear communication and protection against malicious adversaries in two-party computation scenarios.
ElasticON Public Sector - The Search for Relevance with Vector Search
Explore vector search in public sector applications, enabling semantic queries with text, images, and audio. Learn about intelligent discovery and NLP integration in Elastic's search solutions.
Vector Search in Elasticsearch 8
Explore vector search in Elasticsearch 8, covering basics, indexing, efficient search algorithms, and machine learning model integration for advanced similarity-based applications.
ElasticON EMEA - The Search for Relevance with Vector Search
Explore vector search in Elastic, enabling semantic queries for text, images, and audio. Learn about new intelligent discovery methods and combining vector with traditional search techniques.
CXL-ANNS - Software-Hardware Collaborative Memory Disaggregation and Computation for Billion-Scale Approximate Nearest Neighbor Search
Innovative approach for scalable approximate nearest neighbor search using CXL memory disaggregation, caching, and parallel processing to significantly improve performance and efficiency.
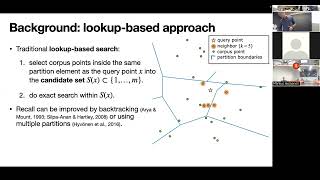
Multilabel Classification Framework for Approximate Nearest Neighbor Search
Explore multilabel classification for approximate nearest neighbor search, enhancing space partitioning trees and enabling supervised classifiers as index structures for ANN search.

Building Deep Retrieval Models in Practical Applications
Explore deep retrieval models for efficient web-scale data search, balancing accuracy and computational cost. Learn techniques for training robust models with limited labeled data.
pgvector - Stylish Hierarchical Navigable Small World Indexes
Explore efficient vector similarity search using pgvector's Hierarchical Navigable Small World indexes for PostgreSQL databases.