Extending PyTorch for Custom Compiler Targets - Accelerator Hardware Integration
Discover how to annotate PyTorch code with custom metadata for optimizing model inference on specialized hardware accelerators, focusing on LPU deployment and performance enhancement.
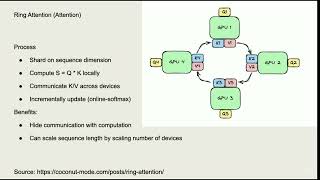
Unraveling Long Context: Existing Methods, Challenges, and Future Directions
Explore the complexities of scaling transformer models for longer context, examining current methodologies, implementation hurdles, and emerging solutions in AI development.
Helping the PyTorch Community Improve the Security Posture of this Popular AI Framework
Discover how to enhance PyTorch's security through OpenSSF Best Practices, dependency management, and proactive measures for safer AI framework implementation and neural network development.
Exploring Distributed Caching for Faster GPU Training with NVMe, GDS, and RDMA
Discover how to optimize GPU training performance through distributed caching techniques, leveraging NVMe storage, GDS, and RDMA networks for enhanced data access and reduced GPU wait times.
Democratizing Diffusion Models with Diffusers
Discover how to create and edit photo-realistic images using Diffusers, an open-source Python library that makes advanced image generation accessible through diffusion models.
Unlocking Local LLMs with Quantization
Discover how quantization optimizes LLMs for local deployment, from pre-training techniques to fine-tuning methods and inference optimization using cutting-edge approaches and community tools.
Machine Learning Integration with Knowledge Systems
Explore the intersection of symbolic methods and deep learning, focusing on integrating machine learning with knowledge-based approaches for advancing artificial intelligence.
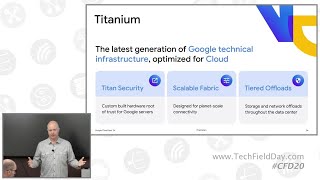
Running Enterprise Workloads in Google Cloud - Optimizing Infrastructure and Performance
Discover how Google Cloud optimizes enterprise infrastructure through Titanium technology, offering enhanced performance, reliability, and cost efficiency for VMware, SAP, and Microsoft workloads.
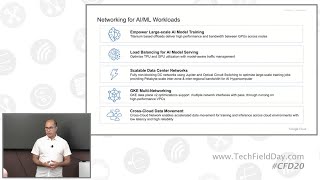
Google Cloud Network Infrastructure for AI and Machine Learning
Discover how Google Cloud's advanced network infrastructure enables efficient AI/ML workloads through dual-network architecture, hardware acceleration, and intelligent load balancing for optimal performance and scalability.
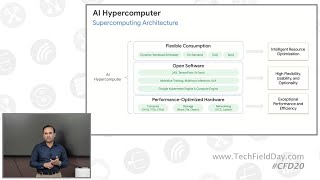
AI Workloads and Hardware Accelerators - Introducing the Google Cloud AI Hypercomputer
Discover how Google Cloud's AI Hypercomputer revolutionizes AI workload management with advanced GPUs, TPUs, and dynamic scheduling, enabling efficient, scalable, and sustainable enterprise AI solutions.
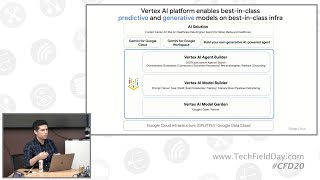
Introduction to Google Cloud Vertex AI Platform - Enterprise AI Development and Deployment
Discover how Vertex AI leverages TPUs and transformer architecture to enable multimodal AI processing across text, images, audio, and video, with enterprise-ready features for secure, customizable AI implementation.
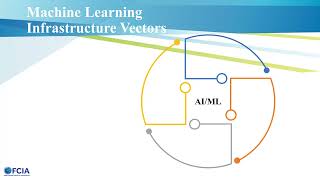
Benefits of FC-NVMe for Containerized Machine Learning Models
Discover how FC-NVMe optimizes containerized machine learning models, exploring Docker fundamentals, ML storage requirements, and performance benefits for efficient model training and deployment.
Training Vision Transformers for Real-Time Image Classification
Master Vision Transformer implementation for real-time emotion classification in video, including hands-on training techniques and comparison with CLIP for zero-shot classification tasks.
How to Fine-Tune Mamba for Question Answering
Dive into practical Mamba language model fine-tuning for question-answering tasks, from basic prompt engineering to complete model training implementation.
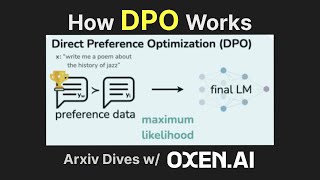
Direct Preference Optimization (DPO) vs RLHF - Understanding Language Model Training
Delve into Direct Preference Optimization (DPO) and discover how it eliminates the need for separate reward models in language model training, offering a more efficient alternative to RLHF.
Understanding Diffusion Transformers and the Technology Behind Sora
Dive into the technical foundations behind OpenAI's Sora, exploring diffusion transformers, U-Nets, and latent diffusion models that power this groundbreaking video generation technology.
Fine-Tuning Self-Rewarding Language Models with Mistral 7B
Dive into implementing Meta's Self-Rewarding Language Model with Mistral 7B, covering fine-tuning techniques, data preparation, prompt generation, and practical demonstrations.
Understanding I-JEPA: A Non-Generative Approach to Self-Supervised Learning from Images
Dive into Meta AI's I-JEPA framework for self-supervised image learning, exploring its architecture, methodology, and advantages over traditional approaches in computer vision and neural networks.
Training LLMs with Diffusion Techniques - From Theory to Implementation
Dive into implementing text generation using discrete diffusion modeling, covering implementation details from basic concepts to training scripts for creating GPT-2 competitive models.
Efficient Text-to-Image Generation with PixART-α DiT Fine-Tuning
Dive into efficient text-to-image generation using PixART-α, exploring fine-tuning techniques, design principles, and practical implementation steps for diffusion transformers.
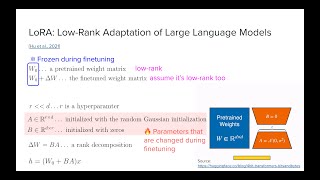
Parameter-Efficient Finetuning - QLoRA and LoRA Methods
Explore parameter-efficient fine-tuning techniques with LoRA and QLoRA, learning how to optimize large language models while maintaining performance and reducing computational costs.