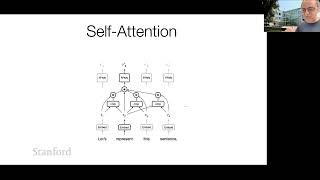
How I Learned to Stop Worrying and Love the Transformer - Stanford CS25 Lecture
Explore the Transformer's evolution and future directions with Ashish Vaswani, co-author of "Attention is All You Need". Gain insights into motivations, developments, and promising research areas in AI and NLP.
Overview of Transformers - Stanford CS25: Lecture 1
Comprehensive introduction to NLP, Transformers, and AI agents, covering history, functionality, recent breakthroughs, applications, and challenges in the field of artificial intelligence.
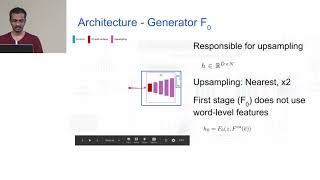
AttnGAN: Fine-Grained Text to Image Generation with Attentional Generative Adversarial Networks
Explore fine-grained text-to-image generation using attentional GANs, covering architecture, experiments, and novel scenarios in this technical deep dive.
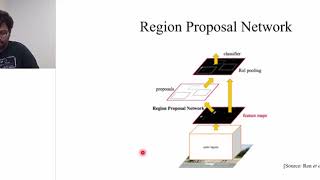
Video Action Transformer Network: Implementation and Experiments
Learn about Video Action Transformer Networks, exploring their architecture, implementation, and experimental results for advanced video understanding and action recognition.
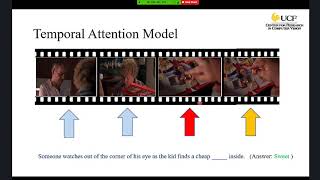
Video Content Understanding Using Text
Explore video content understanding using text, covering challenges, algorithms, and techniques for video representation, scoring, optimization, and inaccuracy detection.
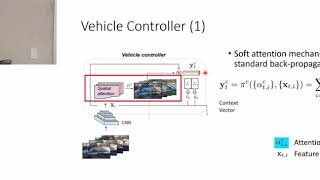
Textual Explanation for Self-Driving Vehicles
Explore self-driving vehicle technology through an explainable driving model, focusing on network architecture, preprocessing, and evaluation of vehicle control and explanation generation.
Demystifying LLMs and Their Security Implications - A Business-Friendly Overview
Explore GenAI and LLMs, understanding their operations, security implications, and deployment scenarios. Learn to manage risks, prevent data leakage, and implement practical strategies for safe AI integration.
Exact Solutions to the Geometric Dynamics of Signal Propagation Through Transformers
Explore exact solutions to geometric dynamics of signal propagation in transformers, predicting their behavior as computational models.
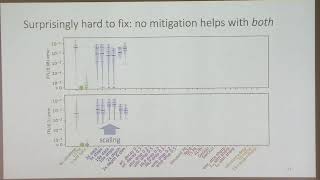
Limitations of Attention Mechanism in Transformers - Implications for Generalization and Optimization
Explore Transformer's reasoning capabilities and limitations in sequential tasks, examining optimization challenges and out-of-distribution generalization issues compared to RNNs.
Transformers as a Computational Model
Explore Transformers as a computational model with Misha Belkin, delving into their architecture, capabilities, and implications for AI research and applications.
Introduction to Transformers
Dive into the fundamentals of Transformers, exploring their architecture and applications in large language models with expert insights from Columbia University.

MIT 6.S191 - Recurrent Neural Networks
Explore recurrent neural networks, LSTMs, and attention mechanisms for sequence modeling. Learn backpropagation through time, gradient issues, and practical applications in deep learning.

MIT: Recurrent Neural Networks
Explore deep sequence modeling with recurrent neural networks, including LSTMs and attention mechanisms. Learn to tackle challenges like vanishing gradients and long-term dependencies in sequence tasks.
Modularity, Attention and Credit Assignment Computations - Anirudh Goyal
Explore modularity, attention, and credit assignment in computational models, focusing on complex generalization, independent mechanisms, and selective activation for improved learning and problem-solving.
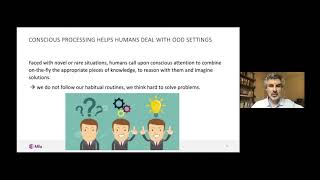
Priors for Semantic Variables - Yoshua Bengio
Explore semantic variables, learning theory, and cognitive processes with Yoshua Bengio. Delve into attention mechanisms, causality, and modular recurrent networks for advanced machine learning insights.
How Do Transformers Work? - A Deep Dive into Neural Network Architecture
Dive into the fundamental mechanics and architecture of transformer models, exploring their key components and operational principles through expert insights from MIT's research.
Transformers in Time Series: A Survey
Explore the application of Transformer models in time series analysis, covering recent advancements and potential future directions in this rapidly evolving field.

The Math Behind Attention Mechanisms
Demystify attention mechanisms in Transformer models through visuals, examples, and mathematical explanations, focusing on embeddings, similarity, and key-query-value matrices.
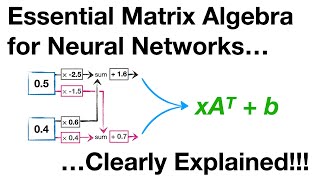
Essential Matrix Algebra for Neural Networks
Learn essential matrix algebra for neural networks, covering linear transformations, matrix operations, and their application in PyTorch and Attention mechanisms.
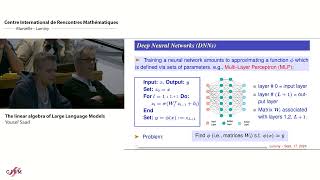
The Linear Algebra of Large Language Models
Explorez les fondements mathématiques des modèles de langage à grande échelle et leur lien avec l'algèbre linéaire avancée.

HOT: Higher-Order Dynamic Graph Representation Learning with Efficient Transformers
Explore higher-order dynamic graph representation learning with efficient Transformers for improved link prediction in rapidly changing graphs. Learn about HOT model's architecture and performance.