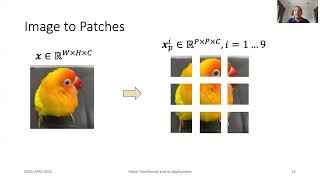
Vision Transformer and Its Applications
Explore vision transformers' architecture, self-attention in computer vision, and applications in recognition, segmentation, and multi-modal learning. Discover their potential for general-purpose model architectures.
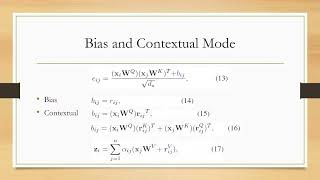
Rethinking and Improving Relative Position Encoding for Vision Transformer - Lecture 23
Explore vision transformer improvements through relative position encoding, examining bias modes, piecewise indexing, and 2D calculations for enhanced performance in image processing tasks.
The Emergence of Clusters in Self-Attention Dynamics
Explore the formation of clusters in self-attention dynamics, examining their impact on transformer models and computational processes.
Transformers, Parallel Computation, and Logarithmic Depth
Explore the computational power of transformers, their connection to parallel processing, and efficiency in solving complex tasks with logarithmic depth.
Introduction to Transformers
Dive into the fundamentals of Transformers, exploring their architecture and applications in large language models with expert insights from Columbia University.
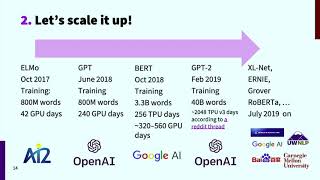
Emergent Linguistic Structure in Deep Contextual Neural Word Representations - Chris Manning
Explore emergent linguistic structures in deep neural word representations with Stanford's Chris Manning, examining language models, attention mechanisms, and vector space analysis.
How Do Transformers Work? - A Deep Dive into Neural Network Architecture
Dive into the fundamental mechanics and architecture of transformer models, exploring their key components and operational principles through expert insights from MIT's research.
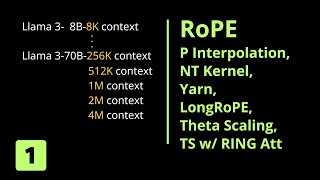
RoPE: Rotary Position Embedding for Extended Context Lengths in Transformers
Dive into Rotary Position Embedding (RoPE) and learn how this innovative technique enhances transformer models by enabling extended context lengths up to 100K tokens.
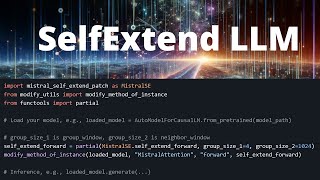
Self-Extending LLM Context Windows Using Grouped Self-Attention
Discover how to extend LLM context windows through grouped self-attention, enabling longer text processing without model retraining. Learn implementation techniques and practical applications.
Seeing Through the Lens of Transformers - A New Era in Computer Vision
Explore the revolutionary impact of transformer architecture in computer vision, from its origins in language processing to groundbreaking applications in visual tasks and self-attention mechanisms.
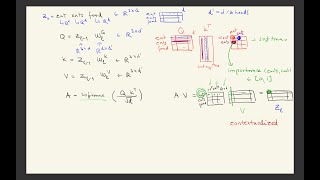
Pairwise Feature Importance and Effective Attention in Self-Attention Networks
Dive into advanced concepts of attention mechanisms, exploring effective attention computation, norm-based analysis, and practical applications in neural networks.
Attention Mechanism and Self-Attention in Deep Learning - Lecture 9
Dive into attention mechanisms and self-attention concepts in deep learning, exploring their revolutionary impact on NLP and discovering practical applications in sequence models.
Transformers Explained - Part 1: Generative Music AI
Comprehensive exploration of transformer architectures in AI, covering intuition, theory, and mathematical formalization, with focus on their application in music and audio processing.
Discovering Black-Box Optimizers via Evolutionary Meta-Learning
Delve into evolutionary meta-learning techniques for discovering black-box optimizers, exploring advanced concepts in evolution strategies and genetic algorithms through self-attention architectures.
Recreate Google Translate - Model Training
Explore model training and testing for Neural Machine Translation, recreating Google Translate using mT5 and Hugging Face. Practical implementation and demo of multilingual translations.
Let's Build GPT - From Scratch, in Code, Spelled Out
Comprehensive tutorial on building a GPT model from scratch, covering key concepts like self-attention, multi-headed attention, and transformer architecture. Includes practical coding examples and insights into modern language models.
TransGAN - Two Transformers Can Make One Strong GAN - Machine Learning Research Paper Explained
Explore TransGAN, a novel approach using transformers for image generation. Learn about its architecture, key techniques, and competitive performance in various datasets.
Nyströmformer- A Nyström-Based Algorithm for Approximating Self-Attention
Explore Nyströmformer, a novel algorithm for approximating self-attention in Transformers with linear complexity, enabling processing of longer sequences and improving scalability in natural language tasks.
Prompt Engineering - Understanding Large Language Models with ChatGPT
Explore large language models and ChatGPT through prompt engineering. Learn about transformer architecture, text embedding, self-attention, and key deep learning methods with practical Python examples.

Neural Nets for NLP 2017 - Attention
Comprehensive exploration of attention mechanisms in neural networks for NLP, covering various types, improvements, and applications, with a focus on the Transformer model.
CMU Multilingual NLP - Machine Translation-Sequence-to-Sequence Models
Explore conditional language modeling, sequence-to-sequence models, generation methods, attention mechanisms, and transformers in multilingual natural language processing.