
NeRFs- Neural Radiance Fields - Paper Explained
Explore neural radiance fields for 3D scene representation and view synthesis, covering network architecture, key concepts, learning process, and advanced techniques.
Self-Extending LLM Context Windows Using Grouped Self-Attention
Discover how to extend LLM context windows through grouped self-attention, enabling longer text processing without model retraining. Learn implementation techniques and practical applications.
How to Code Long-Context LLMs - LongLoRA Implementation with Llama 2 100K
Dive into fine-tuning techniques for extending LLM context lengths using LongLoRA, featuring practical implementation on Llama 2 and Flash Attention 2 optimization for handling extensive sequences.
Deep Learning: Transformers and Encoder-Decoder Architecture - Lecture 10
Dive into transformer architectures, exploring encoder-decoder mechanisms and positional embeddings for advanced deep learning applications.
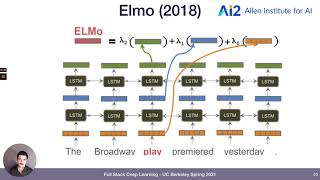
Transfer Learning and Transformers - Full Stack Deep Learning - Spring 2021
Explore transfer learning's evolution from computer vision to NLP, diving into embeddings, language models, and the revolutionary Transformer architecture. Gain insights into various models and their applications.
Transformers Explained - Part 1: Generative Music AI
Comprehensive exploration of transformer architectures in AI, covering intuition, theory, and mathematical formalization, with focus on their application in music and audio processing.
Attention Is All You Need - Transformer Paper Explained
Detailed walkthrough of the original transformer architecture, covering tokenization, embeddings, attention mechanisms, and decoding, with a focus on machine translation applications.
LambdaNetworks- Modeling Long-Range Interactions Without Attention
Explore LambdaNetworks, a novel approach to modeling long-range interactions in AI without traditional attention mechanisms, offering improved efficiency and performance in computer vision tasks.

NeRF - Representing Scenes as Neural Radiance Fields for View Synthesis
Explore NeRF, a neural network-based approach for 3D scene representation and novel view synthesis, achieving photorealistic results from sparse input images through volumetric rendering.
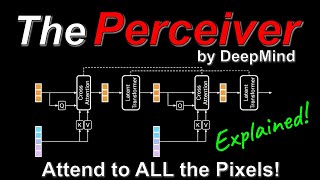
Perceiver - General Perception with Iterative Attention
Explore DeepMind's Perceiver model, a versatile architecture that processes diverse input modalities using iterative attention, solving the quadratic bottleneck problem in Transformers.
LLM Foundations - LLM Bootcamp
Explore foundational concepts of large language models, including machine learning basics, Transformer architecture, and notable LLMs. Gain insights into pretraining datasets and instruction tuning.

Transformer Neural Networks, ChatGPT's Foundation, Clearly Explained
Clear explanation of Transformer Neural Networks, the foundation of ChatGPT and modern AI. Covers key concepts like word embedding, self-attention, and encoder-decoder architecture.
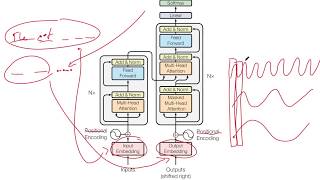
Attention Is All You Need
Explore the groundbreaking Transformer architecture, revolutionizing sequence transduction with attention mechanisms. Learn its superior performance in machine translation and generalization to other NLP tasks.
Deep Dive into the Transformer Encoder Architecture
Detailed exploration of transformer encoder architecture, covering embeddings, positional encodings, self-attention mechanisms, and key components for effective natural language processing.
The Complete Guide to Transformer Neural Networks
Comprehensive exploration of Transformer neural networks for language translation, covering architecture, key components, and practical implementation insights.
Transformers: Introduction and Fundamentals - Day 1
Explore the fundamentals of Transformers, a powerful deep learning architecture revolutionizing natural language processing and beyond.

Transformer Models: Understanding Their Architecture and Functionality - Part 3
Demystifying Transformer models with visuals and examples, covering key concepts like attention mechanism, tokenization, embeddings, and fine-tuning for various NLP tasks.
Transformers Meet Directed Graphs - Exploring Direction-Aware Positional Encodings
Explore direction-aware positional encodings for transformers on directed graphs, enhancing performance in code understanding and sorting network correctness testing.
Cost-Efficient Large Language Model Serving for Multi-turn Conversations with CachedAttention
Innovative attention mechanism for efficient LLM serving in multi-turn conversations, reducing computation costs and improving performance through hierarchical KV caching and optimized cache management.
Attention with Linear Biases Explained
Explore attention mechanisms with linear biases in transformer models, enabling efficient extrapolation to longer sequences without explicit positional embeddings.
Transformers from Scratch - Part 2: Building and Training a Weather Prediction Model
Dive deep into advanced transformer concepts, exploring encoder-decoder architectures, GPT-4o, and positional embeddings. Apply knowledge to weather prediction and analyze model performance.