
Stanford Seminar - Decision Transformer: Reinforcement Learning via Sequence Modeling
Innovative approach to reinforcement learning using sequence modeling and Transformer architecture, offering simplicity and scalability while matching or exceeding state-of-the-art performance in various tasks.
Shaping the Future of AI from the History of Transformer Architectures - Stanford CS25
Explore the evolution of Transformer architectures and AI development with OpenAI researcher Hyung Won Chung, focusing on historical motivations and future projections in the field.
Intuitions on Language Models and Shaping AI's Future - Stanford CS25 Lecture
Explore intuitions on language models and the evolution of Transformer architectures with OpenAI researchers. Gain insights into next-word prediction, scaling laws, and the future of AI development.
LLMOPS: Training a Small LLM (GPT-2) - Machine Learning and Data Science
Explore training a small LLM (GPT2) locally, understanding challenges and limitations of LLM development for individuals and small teams.
How Datadog is Transforming Time Series Forecasting with Toto
Discover how Toto, a Time Series-Optimized Transformer, revolutionizes forecasting through advanced architecture and trillion-point training data, enabling precise zero-shot predictions for observability metrics.

Autoregressive Long-Context Music Generation with Perceiver AR
Explore autoregressive long-context music generation using Perceiver AR, presented by DeepMind's Cătălina Cangea. Gain insights into cutting-edge AI techniques for creating music.
Supercharging Multi-LLM Intelligence with CALM - Composition to Augment Language Models
Discover how CALM (Composition to Augment Language Models) revolutionizes multi-LLM integration through advanced projection layers and cross-attention mechanisms for enhanced AI capabilities.
StreamingLLM: Enabling Infinite Sequence Length in Large Language Models
Dive into StreamingLLM's framework for extending LLM attention windows to handle infinite sequences, featuring practical implementation insights and code analysis.
Mamba AI: Understanding Selective State Space Models as Transformer Alternatives
Explore the groundbreaking MAMBA architecture and its potential to revolutionize AI through selective state space models, offering a compelling alternative to traditional transformers.
Reversible Transformer - GPU Memory Optimization Using ReFORMER and Reversible Residual Layers
Delve into GPU memory optimization techniques for transformers, exploring reversible residual layers and locality-sensitive hashing to enhance deep neural network efficiency and performance.
Deep Learning: RLHF, ChatGPT, and Alignment in LLMs - Lecture 14
Dive into advanced concepts of RLHF, ChatGPT training, and LLM alignment, exploring efficient transformers and the technical foundations behind modern language models.
Transfer Learning and Transformer Models
Explore natural language processing's evolution, focusing on Transformer architecture, language modeling, and BERT's impact on transfer learning in this comprehensive tech talk.
Let's Build GPT - From Scratch, in Code, Spelled Out
Comprehensive tutorial on building a GPT model from scratch, covering key concepts like self-attention, multi-headed attention, and transformer architecture. Includes practical coding examples and insights into modern language models.
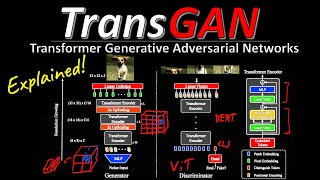
TransGAN - Two Transformers Can Make One Strong GAN - Machine Learning Research Paper Explained
Explore TransGAN, a novel approach using transformers for image generation. Learn about its architecture, key techniques, and competitive performance in various datasets.
Perceiver - General Perception with Iterative Attention
Explore DeepMind's Perceiver model, a versatile architecture that processes diverse input modalities using iterative attention, solving the quadratic bottleneck problem in Transformers.

Complete Natural Language Processing Tutorial in Python
Comprehensive Python tutorial covering NLP fundamentals, techniques, and state-of-the-art models. Includes practical examples using popular libraries and hands-on implementation of advanced concepts.
Prompt Engineering - Understanding Large Language Models with ChatGPT
Explore large language models and ChatGPT through prompt engineering. Learn about transformer architecture, text embedding, self-attention, and key deep learning methods with practical Python examples.
Neural Nets for NLP 2021 - Attention
Explore attention mechanisms in neural networks for NLP, covering key concepts, improvements, and specialized varieties with practical examples and applications.
Text to Image Generation Using ruDALL-E Open Source Model
Explore ruDALL-E, an open-source text-to-image model based on DALL-E. Learn about its architecture, models, and try it out in Google Colab for generating images from text descriptions.
LLM Foundations - LLM Bootcamp
Explore foundational concepts of large language models, including machine learning basics, Transformer architecture, and notable LLMs. Gain insights into pretraining datasets and instruction tuning.
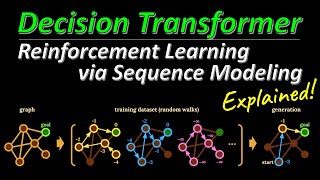
Decision Transformer - Reinforcement Learning via Sequence Modeling
Explore how Decision Transformer reframes offline reinforcement learning as sequence modeling, leveraging Transformer architecture to generate optimal actions based on desired returns, past states, and actions.