Learning the Structure of EHR with Graph Convolutional Transformer - Edward Choi
Explore graph convolutional transformers for learning EHR structure, combining graph convolution and self-attention for supervised prediction tasks in healthcare analytics and representation learning.

Stanford Seminar 2022 - Self Attention and Non-Parametric Transformers
Explore self-attention and Non-Parametric Transformers with PhD students discussing Transformer origins, intuitions, and recent advancements in neural network architecture.
Models on the Move: Towards Feasible Embedded AI for Intrusion Detection on Vehicular CAN Bus
Innovative AI model for efficient intrusion detection on vehicular CAN bus, enhancing automotive cybersecurity with high accuracy and low latency using FPGA hardware acceleration.
The Inner Workings of Large Language Models - Visualizing Self-Attention Mechanisms
Dive into the mechanics of Large Language Models, exploring self-attention mechanisms, architectural designs, and performance optimization through clear visualizations and practical examples.
Synthesizer - Rethinking Self-Attention in Transformer Models
Explores alternative attention mechanisms in Transformer models, proposing the Synthesizer model that learns synthetic attention weights without token-token interactions, showing competitive performance across various NLP tasks.
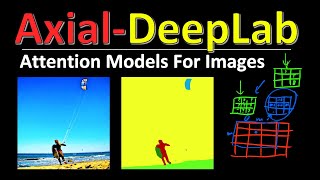
Axial-DeepLab - Stand-Alone Axial-Attention for Panoptic Segmentation
Explore a novel approach to image processing using axial-attention, combining positional embeddings and factorized self-attention to achieve state-of-the-art results in image segmentation tasks.
Self - Cross, Hard - Soft Attention and the Transformer
Explore attention mechanisms and Transformer architecture, covering self/cross and hard/soft attention, key-value stores, and practical implementation in PyTorch for advanced deep learning applications.
Knowledge Is Embedded in Language Neural Networks but Can They Reason?
Explore language models' reasoning capabilities, from n-grams to transformers, and discuss future research directions in neural state machines for improved natural language understanding.
Collective Intelligence for Deep Learning - A Survey of Recent Developments
Survey of recent developments in collective intelligence for deep learning, exploring self-organization, emergent behavior, and cellular systems to address robustness and adaptability issues in neural networks.
Transformers: Introduction and Fundamentals - Day 1
Explore the fundamentals of Transformers, a powerful deep learning architecture revolutionizing natural language processing and beyond.
Linformer - Self-Attention with Linear Complexity
Detailed explanation of the Linformer model, which reduces self-attention complexity in transformers from O(n²) to O(n), improving efficiency while maintaining performance in NLP tasks.

The Narrated Transformer Language Model
Visual introduction to the Transformer architecture, explaining its components and applications in AI/ML. Accessible to various experience levels, covering tokenization, embedding, and output projection.