Milvus: A Purpose-Built Vector Data Management System
Explore Milvus, a purpose-built vector data management system, and its applications in efficient similarity search and AI-powered data analysis.
pgvector - Stylish Hierarchical Navigable Small World Indexes
Explore efficient vector similarity search using pgvector's Hierarchical Navigable Small World indexes for PostgreSQL databases.
Chroma Vector Database: Retrieval for LLMs
Explore Chroma Vector Database's role in enhancing LLM retrieval capabilities with insights from industry experts Hammad Bashir and Liquan Pei.

Realtime Data Streaming - End-to-End Data Engineering Project
Build a real-time data streaming pipeline using Apache Airflow, Kafka, Spark, and Cassandra. Learn end-to-end data engineering, from ingestion to processing and storage, all containerized with Docker.
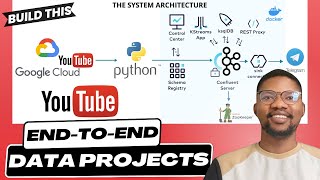
Google Cloud Real-Time Streaming - End-to-End Data Engineering Project
Build an end-to-end data engineering pipeline for real-time YouTube Analytics, using Python, Google Cloud, Docker, and Kafka. Learn to fetch, process, and stream data, with instant Telegram notifications.
Football Data Analytics: Azure End-to-End Data Engineering Project
Extract, clean, and analyze football data using Apache Airflow, Azure services, and Tableau. Build a comprehensive data pipeline from Wikipedia to interactive visualizations.
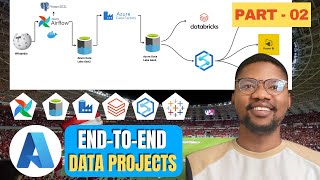
Football Data Analytics: Azure End-to-End Data Engineering Project - Part 2
Extract, store, and analyze football data using Azure services and Apache Airflow. Develop end-to-end data engineering skills through hands-on implementation of a real-world project.
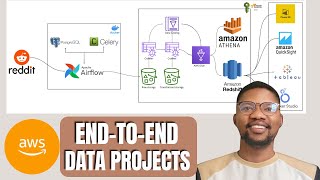
Reddit Data Pipeline Engineering with AWS - End-to-End Data Engineering
Build a comprehensive Reddit data pipeline using AWS services, integrating Airflow, S3, Glue, Athena, and Redshift for efficient ETL processes and analytics.
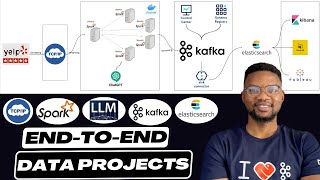
Realtime Socket Streaming with Apache Spark - End-to-End Data Engineering Project
Build a real-time data streaming pipeline using TCP/IP Socket, Apache Spark, OpenAI LLM, Kafka, and Elasticsearch. Process 7 million records for sentiment analysis and efficient data indexing.
Apache Airflow with Spark for Data Engineers - Full Course
Build end-to-end data engineering projects using Apache Airflow, Docker, Spark, and multiple programming languages. Learn to create and submit jobs to Spark clusters for processing and view real-time results.
Realtime Change Data Capture Streaming - End-to-End Data Engineering Project
Implement real-time Change Data Capture streaming using Docker, Postgres, Debezium, Kafka, Apache Spark, and Slack. Create an efficient data pipeline for responsive data engineering projects.
Building Robust Data Pipelines for Modern Data Engineering - End-to-End Project
Develop robust data pipelines using Apache Spark, Azure Databricks, and DBT. Master end-to-end data engineering with Azure, covering ingestion, integration, and transformation in a modern data architecture.
Realtime Streaming with Data Lakehouse - End-to-End Data Engineering Project
Design, implement, and maintain secure, scalable lakehouse architectures using Apache Spark, Kafka, Flink, Delta Lake, AWS, and open-source tools. Unlock data's potential through advanced analytics and machine learning.
Realtime Algorithmic Trading with Apache Flink - End-to-End Data Engineering Project
Develop an end-to-end algorithmic trading system using Apache Flink, Kafka, and Python. Learn real-time data processing, custom algorithms, and financial market insights.
Fraud Detection Use Case with Red Hat OpenShift Data Science
Explore hands-on fraud detection techniques using a practical GitHub repository, guided by experienced software engineers.
Debezium - Building Streaming Data Pipelines with Change Data Capture
Explore Debezium's features for building streaming data pipelines using popular databases as sources, with a focus on Apache Kafka integration and alternative data sinks.
Migrate Your Kafka Cluster with Minimal Downtime
Learn strategies and tools for migrating Kafka clusters with minimal downtime. Explore MirrorMaker, Confluent Replicator, and Cluster Linking. Gain insights on planning, execution, and overcoming challenges in Kafka migration.
Kafka, Flink, and Beyond: Current Developments and Future Innovations in Data Streaming - 2023
Explore recent advancements, upcoming improvements, and innovative applications in Kafka and Flink data streaming. Gain insights from industry leaders on tiered storage, queues, use cases, and two-phase commit protocol.
Unpacking Three Types of Feature Stores - MLOps Podcast
Explore feature stores, vector stores, and embeddings in ML and LLMs. Learn about personalization in prompts, MLOps challenges, and innovations from Featureform's CEO Simba Khadder.
Conjuring Data with APIs - PowerShell Techniques
Harness the power of APIs to conjure and manipulate data using PowerShell, enhancing your scripting capabilities and automation workflows.
Predicting Healthcare Insurance Costs with Python - Real-World Data Science Problem Solving
Predict healthcare insurance costs using Python and machine learning. Clean data, visualize with pandas, and apply scikit-learn for linear regression in this hands-on tutorial with real-world data analysis.