Introducing UACCE Bus in DPDK - Unified Accelerator Framework Integration
Discover how UACCE bus enables seamless integration of accelerator devices in DPDK, exploring Shared Virtual Addressing implementation and its potential to enhance application performance.
Coupling Eventdev Usage with Traffic Metering and Policing for QoS
Discover how to integrate hardware RX scheduling with metering and policing modules using DPDK's eventdev framework for efficient packet processing and QoS implementation.
Lessons Learnt from Reusing QDMA NIC to Base Band PMD
Discover key insights and practical lessons from converting AMD Xilinx FPGA NIC PMD to BBDEV PMD, exploring technical challenges and implementation strategies for efficient hardware adaptation.
Extending For_each_lcore for Hardware Topology LCORE - Achieving Higher Performance
Discover how to optimize processor performance through topology-aware LCORE listing, focusing on pkt-distributor, event-dev and pipeline libraries for enhanced payload processing.
API for Cache Stashing Hints in DPDK Applications
Explore the development of cache stashing APIs in DPDK, focusing on how TPH capabilities can provide developers with fine-grained control over CPU cache utilization and memory management.
Revolutionizing Big Data Analytics with NeuroBlade's SQL Processing Unit (SPU)
Discover how NeuroBlade's SQL Processing Unit revolutionizes data analytics by accelerating SQL queries up to 30x faster, offering cost-effective solutions for enterprise-scale data processing and insights.
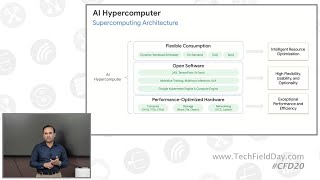
AI Workloads and Hardware Accelerators - Introducing the Google Cloud AI Hypercomputer
Discover how Google Cloud's AI Hypercomputer revolutionizes AI workload management with advanced GPUs, TPUs, and dynamic scheduling, enabling efficient, scalable, and sustainable enterprise AI solutions.
Getting Started with VMware Private AI Foundation with NVIDIA
Discover how to efficiently deploy AI infrastructure using VMware's Private AI Foundation and NVIDIA, focusing on GPU selection, virtualization, and automated deployment for enterprise AI success.
NVMe Computational Storage - From Addressing Ransomware to Improving Bandwidth
Discover how NVMe Computational Storage tackles ransomware detection and optimizes bandwidth usage through real-world applications from IBM and Solidigm experts in cloud, enterprise, and IoT environments.
Understanding Medusa: A Framework for LLM Inference Acceleration with Multiple Decoding Heads
Dive into the mechanics of Medusa, a framework that accelerates LLM inference through parallel token prediction and tree-based attention, enhancing AI model performance and efficiency.
Introduction to Compute Express Link (CXL) 3.0 - Features and Fabric Management
Discover the latest advancements in CXL 3.0 technology, including enhanced fabric capabilities, improved memory sharing, and next-generation datacenter architecture for high-performance computing workloads.
Universal Chiplet Interconnect Express - Building an Open Ecosystem of Chiplets
Discover how UCIe technology enables mixing chiplet components from multiple vendors for customized System-on-Chip construction, addressing growing compute demands across various sectors.
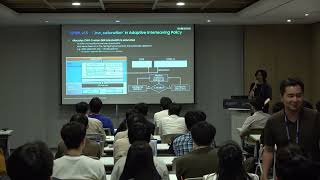
Effective Data Tiering and Memory Allocation Techniques in Heterogeneous Memory System
Discover advanced techniques for optimizing data tiering and memory allocation in heterogeneous systems, focusing on efficient resource management and performance enhancement.
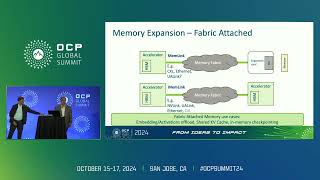
Memory Expansion Requirements for AI Systems in Hyperscale Data Centers
Explore evolving memory architecture requirements for AI systems in hyperscale data centers, focusing on GPU acceleration and infrastructure optimization for next-generation applications.
Accelerator Clusters: The New Supercomputer
Discover how accelerator clusters are revolutionizing supercomputing through NVIDIA's innovative approach to high-performance computing architecture and interconnect technologies.
Understanding How Microarchitecture Impacts Microservices
Discover how microarchitecture design choices affect microservices performance, scalability, and efficiency in modern distributed systems through practical insights and architectural analysis.
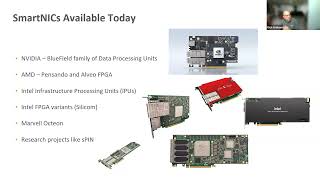
Leveraging SmartNICs for HPC and Data Center Applications - Part 1
Discover how SmartNICs revolutionize high-performance computing and data center operations, exploring key implementation strategies and performance optimization techniques for modern infrastructure.
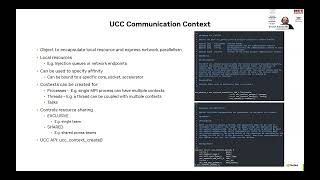
Unified Collective Communication - A Library for CPU, GPU, and DPU Integration
Explore the innovative Unified Collective Communication library that seamlessly integrates CPU, GPU, and DPU communication, enhancing performance across diverse computing architectures.
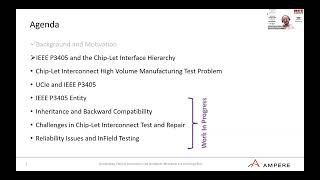
Chip-let Interconnect Test and Repair
Explore advanced techniques for testing and repairing chip-let interconnects, focusing on practical solutions and emerging methodologies in semiconductor manufacturing.
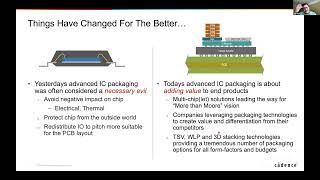
The Challenges of Scaling Beyond Moore's Law - From Monolithic Dies to 3D Heterogeneous Integration
Explore the shift beyond Moore's Law into 3D heterogeneous integration, examining technical challenges, economic factors, and emerging solutions in semiconductor design and packaging.
3D IC Test Strategy and DFT Methodologies for Advanced Packaging Technologies
Explore comprehensive testing strategies for 3D integrated circuits, covering DFT methodologies, BSDL implementation, and IJTAG integration for advanced semiconductor packaging technologies.