Low-Code Machine Learning on Databricks with AutoML
Discover how to build, train, and deploy ML models using Databricks AutoML and low-code tools, empowering users of all expertise levels to create predictive analytics solutions.
Kolmogorov Complexity for DNA Sequences Analysis in Python
Learn to analyze DNA sequence complexity using Kolmogorov Complexity and Python. Covers theoretical background, Lempel-Ziv algorithm, and practical implementation with code walkthrough and visualization.
Analysis Services - What Is the Difference Between Tabular and Multidimensional Models
Explore the differences between Tabular and Multidimensional models in Microsoft Analysis Services, their use cases, and how to choose the right model for your data analysis needs.
Jupyter Notebooks - An Introduction
Learn to create interactive documents combining code, visualizations, and text using Jupyter Notebooks. Explore features, languages, and applications across various industries.
Dimensional Modeling
Learn key concepts and practices of Dimensional Modeling using the Kimball Method. Explore star schemas, snowflake schemas, surrogate keys, and slowly changing dimensions for effective data warehouse design.
Joining Multiple Heatmaps - ComplexHeatMap Tutorial
Learn to combine multiple heatmaps in R using ComplexHeatmap. Master horizontal and vertical merging, customization, and annotations for effective data visualization in bioinformatics.

Clustering and Markers Identification for ScRNA-Seq - Seurat Package Tutorial
Learn to analyze single-cell RNA-seq data using Seurat package, covering data import, QC, normalization, clustering, and marker identification. Gain insights into cell interactions and create visualizations.
Applied Data Science for Predictive Time Series Analytics - Nesime Tatbul
Explore predictive time series analytics, focusing on anomaly detection and explanation techniques, with insights on evaluation tools and real-world applications in cloud observability.
Learning Transferable Human Behavior Representations From Sensor Data - Flora Salim
Explore techniques for learning transferable human behavior representations from sensor data, including challenges, preprocessing, and applications in various domains.
The Big Promise of Big Data Analytics - ACM WomENcourage 2020
Explore intelligent data tools bridging users and data. Learn about natural language queries, clarifications, and recommendations for effective data exploration and analysis.
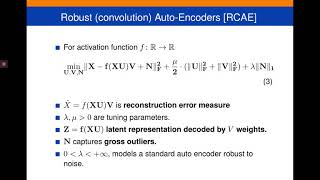
KDD 2020: Robust Deep Learning Methods for Anomaly Detection
Explore robust deep learning techniques for anomaly detection, focusing on auto-encoders and their applications in video surveillance and image analysis.
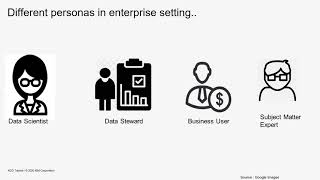
Overview and Importance of Data Quality
Explore data quality's crucial role in machine learning, covering challenges, metrics, cleaning techniques, and strategies for handling imbalanced datasets in enterprise settings.
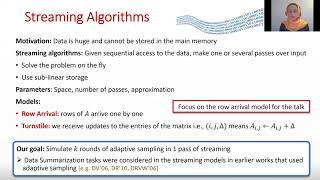
Non-Adaptive Adaptive Sampling on Turnstile Streams
Explore non-adaptive adaptive sampling techniques for turnstile streams, covering data summarization, streaming algorithms, and applications in subset selection, subspace approximation, and volume maximization.

Sketching Big Data
Explore big data sketching techniques with Harvard's Jelani Nelson, covering approximate counting, frequent items, and graph streaming in this insightful lecture.
Robust List Decoding of Spherical Gaussians
Explore robust list decoding of spherical Gaussians, covering algorithms, error identification, and computational challenges in high-dimensional statistics.
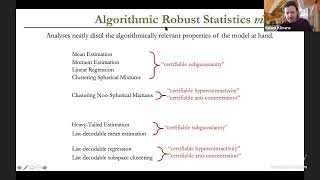
Recent Progress in Algorithmic Robust Statistics via the Sum-of-Squares Method
Explore recent advancements in algorithmic robust statistics using the Sum-of-Squares method, focusing on learning and testing in high-dimensional spaces.

Excel 2021 for Mac Beginner Tutorial
Comprehensive guide for Mac users to master Excel 2021, covering interface navigation, data manipulation, formulas, functions, and advanced features like Pivot Tables and Macros.
Koalas - Scaling Pandas API on Apache Spark
Learn to scale pandas operations to big data using Koalas, an open-source project implementing the pandas API on Apache Spark. Transition seamlessly from single-machine to distributed environments for large-scale data science.

Bringing Satellite and Drone Imagery into Data Science Workflows
Explore satellite and drone imagery analysis in data science workflows using RasterFrames, a Spark SQL extension with Python API for processing spatial image data and integrating with ML frameworks.
Geospatial Data Analysis in Apache Spark - Challenges and Solutions
Explore geospatial data challenges in Apache Spark, comparing libraries, and learning best practices for data ingestion, storage, and retrieval using spatial indexing techniques.
Generative Hyperloop Design - Managing Massively Scaled Simulations for Demand Modeling
Explore large-scale simulation framework for Hyperloop design, utilizing cloud computing, data pipelines, and machine learning to address key technical and business questions for safe and efficient mass transportation.