Excel Training - Complete Course
Comprehensive Excel training covering worksheets, formatting, functions, charts, and case studies. Develop essential skills for data management and analysis through hands-on practice and real-world applications.
Encoding Multi-Layered Vega-Lite COVID-19 Geodata Visualizations with MLflow
Learn to create and manage multi-layered Vega-Lite visualizations for COVID-19 geodata using MLflow, enhancing data communication and lifecycle management for powerful insights.
Learn to Use Databricks for Data Science
Discover how Databricks simplifies data science with a unified platform for analytics workloads, from data preparation to predictive analytics, enhancing collaboration and productivity at scale.
Getting Started with Databricks SQL Analytics
Explore Databricks SQL Analytics: set up SQL endpoints, query workspaces, create dashboards, and connect BI tools. Learn how this tool enhances the Lakehouse architecture for SQL-savvy data analysts.
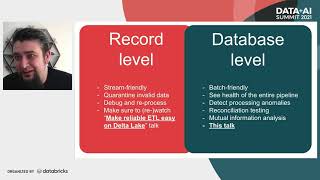
Data Quality Tools Comparison for Continuous Data Imports
Comparison of open-source data quality tools for continuous imports, covering maturity, documentation, extensibility, and features like data profiling and anomaly detection.
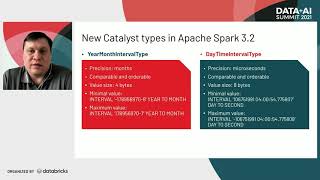
Comprehensive View on Intervals in Apache Spark 3.2
Explore Apache Spark 3.2's interval enhancements, including ANSI SQL conformance, new interval types, and improved APIs. Learn to construct, use, and manage intervals effectively in Spark SQL and PySpark.
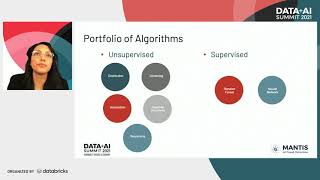
Wizard Driven AI Anomaly Detection with Databricks in Azure
Explore wizard-driven AI anomaly detection for fraud prevention using Databricks. Learn unsupervised and supervised methods, aggregation frameworks, and human-in-the-loop feedback to improve models over time.
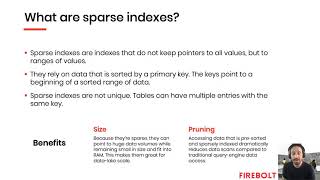
Low-Latency & High-Concurrency Analytics Over Data Lakes
Explore advanced techniques for achieving low-latency, high-concurrency analytics on large-scale data lakes. Learn about optimized storage, indexing, and practical approaches to handle massive data volumes efficiently.
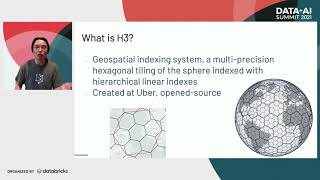
Large Scale Geospatial Indexing and Analysis on Apache Spark
Explore large-scale geospatial indexing and analysis using Apache Spark, covering challenges, frameworks, data structures, and practical applications in cloud-first architecture with Databricks.
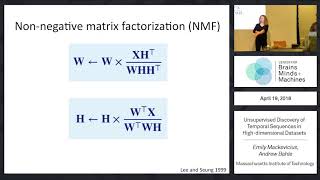
Unsupervised Discovery of Temporal Sequences in High-Dimensional Datasets
Explore unsupervised discovery of temporal sequences in high-dimensional datasets using seqNMF, a tool extending convolutional NMF. Learn to extract and validate neural sequences from large-scale recordings.
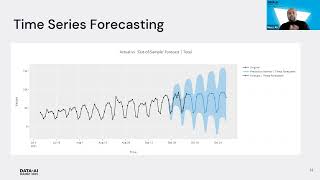
Time Series Forecasting with PyCaret
Explore automated time series forecasting with PyCaret's low-code module. Learn setup, EDA, training, and forecasting techniques to streamline your predictive modeling workflow.
NBA Analytics - Evolution and Impact in Professional Sports
Explore the evolution of sports analytics in the NBA, its impact on teams, and how data drives competitive advantage in professional basketball.
Master Databricks and Apache Spark - SparkR Usage - Lesson 35
Explore SparkR for integrating R with Databricks and Apache Spark, covering architecture, APIs, libraries, and practical examples of data manipulation and analysis.
Using SQL Views in Databricks and Apache Spark - Lesson 12
Learn to create and utilize SQL views in Databricks for efficient data analysis and pipeline reuse. Explore common table expressions, aggregations, and case statements for advanced querying techniques.
Using the Data Science Process - Lesson 5
Explore the data science process from project inception to completion, covering key steps for successful implementation in Databricks and Apache Spark projects.
Create a Spark Cluster - Master Databricks and Apache Spark Step by Step - Lesson 4
Learn to create and use Apache Spark clusters, understand their differences from Databricks, and explore data querying with Zeppelin notebooks in this step-by-step guide.
Databricks Workspace Tour and Notebook Demo - Lesson 3
Comprehensive tour of Databricks Workspace, demonstrating tools and features with focus on the proprietary notebook IDE. Provides foundation for advanced Databricks and Apache Spark usage.
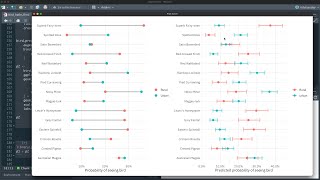
Fit and Predict With Logistic Regression for Bird Bath Observations in Australia
Learn to model bird bath observations in Australia using tidymodels, combining model specifications with feature engineering recipes for effective fitting and prediction.

Predict Housing Prices in Austin TX with Tidymodels and XGBoost
Explore feature engineering for boosted tree models using Austin housing data. Learn to incorporate text information as indicator variables and tune models for accurate price predictions.
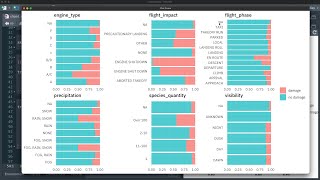
Class Imbalance and Classification Metrics With Aircraft Wildlife Strikes
Explore how handling class imbalance affects classification metrics using aircraft wildlife strike data, with focus on sensitivity and specificity in predictive modeling.
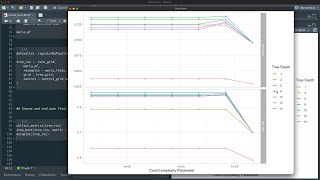
Partial Dependence Plots for Mario Kart World Records
Explore decision tree modeling and partial dependence profiles for Mario Kart world records using tidymodels and DALEX, with a focus on predicting shortcut usage.