Inside Multimodal Models - Understanding Technology and Applications
Dive into the mechanics and applications of multimodal AI models, exploring key technologies like CLIP, DALL-E, and GPT-4 through practical demonstrations and real-world use cases.
Extracting Structured Data from Images with OCR and LLM
Discover how to combine OCR technology with Large Language Models to efficiently extract and structure data from images, featuring practical demonstrations using Tesseract.js and OpenAI integration.
Building Local LLMs for OCR, Object Detection and Image Parsing Using Mono-InternVL
Master local implementation of Mono-InternVL for advanced computer vision tasks including OCR, object detection, and image parsing using Python, achieving high-precision results.
Building a Visual Inspection System for Defect Detection with Python
Learn to create a Python-based visual inspection system that automatically detects and identifies surface defects using AI and computer vision techniques.
Leveraging Pre-trained Vision Foundation Models for Geophysical Data Processing and Interpretation
Discover how to adapt computer vision foundation models for geoscience applications, focusing on efficient processing and interpretation of geophysical data like seismic and lunar imagery.
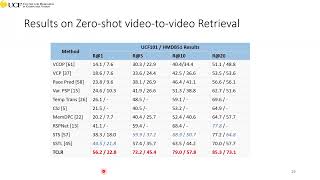
Towards Label Efficiency and Privacy Preservation in Video Understanding
Explore advanced techniques for efficient video analysis while maintaining data privacy, focusing on label-efficient learning methods and privacy-preserving frameworks for video understanding.
Object and Bounding Box Detection with Vision Models Using Florence 2
Master object detection and bounding box techniques using Florence 2 vision models, from basic architecture to custom dataset annotation and fine-tuning with LoRA adapters for optimal performance.

From CroCo to MASt3R - A Paradigm Change in 3D Computer Vision
Explore groundbreaking advancements in 3D vision through CroCo, DUSt3R, and MASt3R frameworks, revolutionizing multi-view stereo reconstruction and geometric deep learning for enhanced robotic navigation and cultural preservation.
YOLO - From Zero to Creating Applications and Fine-tuning - Tutorial 11
Aprende a implementar YOLO 11 desde cero, desarrollando aplicaciones prácticas y realizando ajustes de fine-tuning para optimizar el rendimiento de detección de objetos.

Creating Multiple Consistent Characters with OmniGen in ComfyUI
Master OmniGen's streamlined workflow in ComfyUI to generate multiple consistent characters in a single scene, complete with detailed clothing and seamless integration.
Splitting the Difference on Adversarial Training - A Method for Robust Neural Networks
Discover a novel approach to adversarial training that enhances neural network robustness while maintaining optimal accuracy by splitting data classes into clean and adversarial categories.

Microsoft OmniParser - AI Screen Reading and UI Interaction
Discover how OmniParser enables AI agents to interpret and interact with user interfaces through advanced screen reading and LLM integration capabilities.
The Unfinished Epic of Discrete Tomography
Delve into the mathematical foundations of discrete tomography through an engaging exploration of its ongoing challenges and theoretical developments in modern computational geometry.
Generative AI for Multimodal Biomedicine
Explore groundbreaking developments in multimodal biomedicine AI, including GigaPath, OCTCube, and BiomedParse foundation models, and their potential impact on advancing medical applications through multi-agent frameworks.
Diffusion Models - Lecture 18
Dive into the fundamentals of diffusion models with MIT Prof. Song Han, exploring their architecture, principles, and applications in machine learning and AI generation.
Diffusion Models - Lecture 18
Dive into the fundamentals of diffusion models, exploring their architecture, principles, and applications in machine learning through expert guidance from MIT's Professor Song Han.
Abstraction and Evolution with Large Language Models
Explore how large language models enhance genetic programming through concept-guided evolution, with applications in symbolic regression and image classification demonstrated through practical examples.
Introduction to Game Shaders and GLSL Programming - Lecture 18
Dive into shader programming fundamentals, from basic GLSL concepts to advanced effects like green screening and spotlights, with hands-on demonstrations using ShaderToy and SFML implementation.
Object Detection with Python - A Beginner's Guide to Computer Vision
Learn to build an AI-powered object detection system using Python, OpenCV, and YOLO, covering essential tools, dataset preparation, and model training techniques.
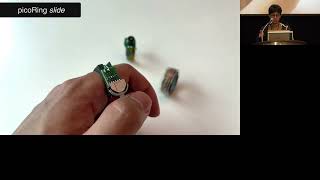
PicoRing - Battery-Free Rings for Subtle Thumb to Index Input
Discover groundbreaking battery-free ring technology that enables subtle finger-based input interactions, revolutionizing wearable device interfaces and human-computer interaction methods.
Deploying Generative AI Applications - Building Code Assistants, Image Search, and Robotics Solutions
Discover practical implementations of LLMs through hands-on demonstrations of image search applications, coding assistance tools, and vision-language action models for robotics integration.