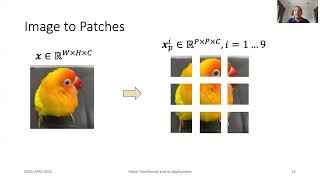
Vision Transformer and Its Applications
Explore vision transformers' architecture, self-attention in computer vision, and applications in recognition, segmentation, and multi-modal learning. Discover their potential for general-purpose model architectures.
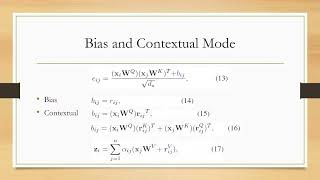
Rethinking and Improving Relative Position Encoding for Vision Transformer - Lecture 23
Explore vision transformer improvements through relative position encoding, examining bias modes, piecewise indexing, and 2D calculations for enhanced performance in image processing tasks.
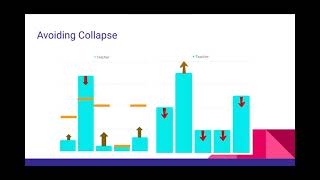
Emerging Properties in Self-Supervised Vision Transformers - Lecture 25
Explore emerging properties in self-supervised vision transformers, covering related topics, model overview, and implementation details for advanced computer vision applications.
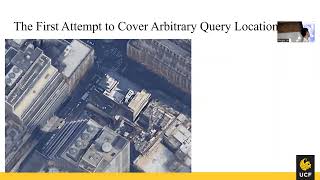
Geo-localization Framework for Real-world Scenarios - Defense Presentation
Explore advanced geo-localization techniques using vision transformers and novel loss functions for improved accuracy in real-world scenarios, with a focus on bridging domain gaps.
Automatic Image Captioning with Vision Transformer and GPT-2
Learn how to generate descriptive captions for images using Python and PyTorch in this 16-minute tutorial. Explore the process of automatic image captioning with the pre-trained 'nlpconnect/vit-gpt2-image-captioning' model from Hugging Face. Set up the V…

Building Generalist Robotics Policies from Scratch
Build a Generalist Robotics Policy from scratch, reimplementing the "Octo" model step-by-step. Learn to create, train, and evaluate large models for robotics using interaction data and transformer architecture.
Using Promptable Image Analysis for Clinical Diagnostics - Ray Summit 2024
Explore the integration of LLMs and Vision Transformers for enhanced clinical image analysis. Discover how Ray technologies enable real-time processing of multimodal data, revolutionizing diagnostic workflows in healthcare.
LLMOps: Personalizar ViT Classifier con tu Propia Data y Docker Inference
Personaliza un Vision Transformer con tu dataset, crea un docker y un punto de inferencia con FastAPI para clasificación de imágenes.
MLOPS: Inferencia de Modelo VIT ONNX en Azure ML Managed Endpoint - Español
Aprende a realizar inferencia en Azure Kubernetes Services utilizando un modelo Vision Transformer convertido a ONNX con Azure Machine Learning Studio y Python SDK v2.
LLMOps: Inferencia de Clasificador ViT Fine-Tuned en CPU con C#
Aprende a realizar inferencia en C# con un Vision Transformer personalizado en formato ONNX utilizando CPU para clasificación de imágenes.
LLMOps: Converting Fine-Tuned ViT Classifier to ONNX for CPU Inference
Convierte un Vision Transformer personalizado a ONNX y realiza inferencia en CPU, optimizando el rendimiento del modelo de clasificación de imágenes.
Fine-Tuning ViT Classifier for Retinal Image Detection - Part 2 (Español)
Personaliza un Vision Transformer para clasificar imágenes de retina, detectando ojos enfermos usando el dataset EyeQ. Aprende a ajustar modelos pre-entrenados para tareas específicas.
Fine-Tuning ViT Classifier for Retina Images and Converting to ONNX Format - Part 3
Personaliza un Vision Transformer con tu dataset de imágenes de retina y conviértelo a formato ONNX para optimizar el rendimiento y la portabilidad.
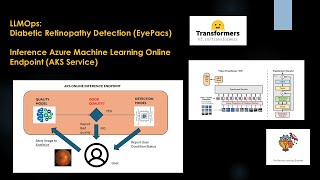
Fine-Tuning ViT Classifier for Retinal Images with AKS Inference - Part 4 (Español)
Personaliza un Vision Transformer con tu dataset de imágenes de retina y crea un punto de inferencia administrado en Azure Machine Learning Studio (AKS).
Python Classes for AI Model Subclassing and Fine-tuning
Master Python classes and their application in AI development, focusing on LLM fine-tuning and Vision transformer implementation with KERAS3 functionality.
Deep Learning Techniques for Monocular Depth Estimation
Dive into advanced monocular depth estimation techniques, from transfer learning to Vision Transformers and Meta AI's DINOv2 model, exploring cutting-edge solutions in computer vision.
AI Domain Generalization: ICRM and ContextVisionTransformers in Medical and Emergency Response
Explore advanced domain generalization in AI through MIT's ICRM methodology and ContextViT, focusing on medical imaging and emergency response applications across diverse real-world scenarios.
Seeing Through the Lens of Transformers - A New Era in Computer Vision
Explore the revolutionary impact of transformer architecture in computer vision, from its origins in language processing to groundbreaking applications in visual tasks and self-attention mechanisms.

DINOv2: Data Pipeline, Model Training and Results - Meta AI's Visual Feature Learning System
Delve into Meta AI's DINOv2 architecture, exploring its data pipeline, training methodology, and innovative features for robust visual processing without supervision in just 12 minutes.
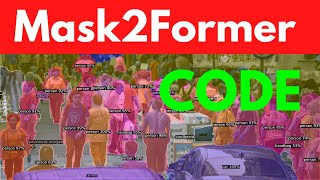
Code Panoptic Image Segmentation with Vision Transformer and Mask2Former - A PyTorch Tutorial
Dive into advanced image segmentation using Mask2Former architecture, exploring masked attention and universal segmentation techniques for enhanced computer vision applications.
Learning Vision Transformer (ViT) Technology: Research Methods and Resources - 2023
Discover effective strategies for learning and implementing Vision Transformer technology through top academic resources, code repositories, and research platforms like HuggingFace and Papers with Code.