How to Use OCR: Getting Started with Optical Character Recognition
Explore OCR models, benchmark performance, and follow a step-by-step guide to implement Optical Character Recognition in your projects.
Automate Data Extraction from ID Documents with Azure Form Recognizer - AI Show Episode 26
Learn to automate data extraction from ID documents using Azure Form Recognizer, exploring prebuilt models, REST APIs, SDKs, and AI Builder for efficient key-value pair extraction from passports and driver's licenses.
Analyzing Unstructured Documents with Azure Form Recognizer - Episode 52
Explore Azure Form Recognizer's latest updates for analyzing unstructured documents, including capabilities, pricing, and a live demo. Learn how this tool can streamline document processing and data extraction tasks.
Build Mobile OCR Scanner App with Flutter
Learn to build an OCR scanner app for Android and iOS using Flutter and Google ML Vision, converting images to text with machine learning techniques.
Improving Invoice Management for SAP S/4HANA Cloud with AI
Centralize and automate invoice processing with SAP Central Invoice Management, leveraging AI for document extraction, cost assignment, and tax code automation in multi-backend environments.
Computer Vision: OCR Tesseract for Different File Formats and Types - Data Science and Machine Learning
Aprende a extraer texto de diversos formatos de archivos utilizando OCR Tesseract para visión por computadora en ciencia de datos y aprendizaje automático.
Computer Vision: OCR Tesseract vs PaddleOCR - Español
Explora OCR: compara Tesseract y PaddleOCR, analiza alternativas en la nube y locales para el reconocimiento óptico de caracteres en visión por computadora.
Computer Vision: OCR Tesseract in C# - Español
Aprende a implementar OCR con Tesseract en C# para reconocimiento de texto en imágenes. Explora esta poderosa herramienta de visión por computadora.
Takeaways from the SCALE 2024 Workshop on Video-based Event Retrieval
Explore multilingual event-centric video retrieval techniques, focusing on non-professional content. Learn about dataset creation, modality-specific improvements, and key findings in text extraction and fusion.
Python Tutorial to Build Image-to-Text App Using EasyOCR and Streamlit
Build an image-to-text web app using EasyOCR and Streamlit. Extract text from images with Python in this hands-on data science project. Learn web app development and optical character recognition.
Extract Drug Labels Using Deep Learning with PaddleOCR and Python
Learn to extract prescription medication labels using PaddleOCR and Python. Gain hands-on experience in optical character recognition, from installation to visualization, with potential applications in accessibility.
GPT-4 Low Latency Screen-to-Voice Tutorial with OCR
Explore low-latency screen-to-voice technology with impressive OCR capabilities, enabling real-time question answering and problem explanation from screen content.
Computer Vision: OCR Tesseract in C# - Data Science and Machine Learning
Implement OCR using Tesseract library in C# for extracting text from images, enhancing your computer vision skills.
Entering the Fourth Dimension of OCR with Tesseract
Explore Tesseract OCR's capabilities, accuracy, and integration with Java projects. Learn how to process scanned text and assess its performance using real-world examples.
OCR - Information Through Images
Explore image processing and OCR techniques to extract valuable information from visual data, unlocking potential applications across various fields and industries.
Computer Vision: OCR Tesseract for Different Formats and File Types
Extract text from various image and document formats using OCR Tesseract. Learn practical techniques for optical character recognition in data science and machine learning applications.
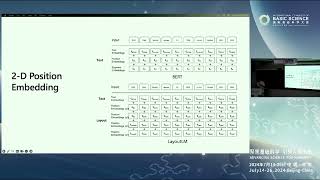
LayoutLM - Pre-training of Text and Layout for Document Image Understanding
Explore LayoutLM, a novel pre-training model integrating text and layout for enhanced document image understanding and information extraction from scanned documents.
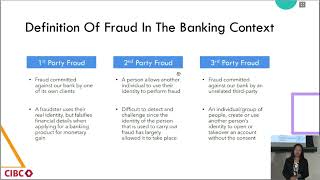
Revolutionizing Fraud Prevention - Harnessing AI and ML to Safeguard Banking from Fraud
Discover how AI and machine learning technologies transform banking fraud prevention, from rule-based systems to advanced self-learning models, OCR validation, and innovative NLP solutions for enhanced security.
Computer Vision: OCR Comparison - Tesseract vs PaddleOCR
Explore OCR techniques using Tesseract and alternatives, comparing offline solutions for computer vision and text recognition in data science and machine learning.
Extracting Structured Data from Images with OCR and LLM
Discover how to combine OCR technology with Large Language Models to efficiently extract and structure data from images, featuring practical demonstrations using Tesseract.js and OpenAI integration.

Building Your Own Private OCR System with LlamaOCR
Discover how to build a private OCR system using LlamaOCR to convert images and scanned documents into structured Markdown, with practical demonstrations in JavaScript and Python through Colab.