Improving Natural Language Understanding Through Adversarial Testing
Explore adversarial testing in natural language understanding to challenge and improve AI systems. Learn to identify weaknesses and develop robust models for real-world applications.
Automatic Image Captioning with Vision Transformer and GPT-2
Learn how to generate descriptive captions for images using Python and PyTorch in this 16-minute tutorial. Explore the process of automatic image captioning with the pre-trained 'nlpconnect/vit-gpt2-image-captioning' model from Hugging Face. Set up the V…
Machine Learning & Deep Learning Projects
Hands-on projects in machine learning and deep learning, covering chatbots, sentiment analysis, image captioning, speech recognition, customer segmentation, and facial expression detection.
Tensor2Tensor - TensorFlow at O’Reilly AI Conference, San Francisco '18
Explore state-of-the-art deep learning models and datasets with Tensor2Tensor, accelerating ML applications like translation, parsing, and image captioning.
Computer Vision Meets Social Networks
Explore the intersection of computer vision and social networks, covering low-light enhancement, pose estimation, video attractiveness, classification, captioning, and natural language localization.
Large Language Models for Real-World Applications
Explore real-world applications of large language models in this visual overview, covering image captioning, question answering, text generation, and more. Learn about NLP technologies and their potential in various business domains.
BLIP-2: Connecting Vision-Language Models with Q-Former for Image Chat
Explore BLIP-2's innovative approach to combining vision and language models through Q-Former, enabling advanced image-based conversations and multimodal AI interactions.
New Advances in Artificial Intelligence and Machine Learning - Lecture 3
Explore cutting-edge AI and ML advancements, including generative models, reinforcement learning, and computer vision. Gain insights into the capabilities and applications of modern machine learning technologies.

Machine Learning - What Is Easy, Medium, and Hard?
Explore the landscape of machine learning through case studies, examining easy, medium, and hard challenges while considering future possibilities and potential pitfalls.
Image Captioning Python App with ViT and GPT2 Using Hugging Face Models - Applied Deep Learning
Learn to create an image captioning app using ViT and GPT2 models from Hugging Face. Build a Gradio interface and deploy it on the Model Hub for easy access and sharing.
The Future of Crime Detection and Prevention
Expert panel explores AI's role in predicting and preventing crime, discussing technological advancements, ethical concerns, and the future of law enforcement and security.
Fine-tuning PaliGemma for Custom Object Detection
Step-by-step guide to fine-tune PaliGemma for custom object detection, covering setup, dataset preparation, training, evaluation, and deployment. Includes practical tips and important considerations.
Image Annotation with LLaVA and Ollama
Learn to annotate images using LLava 1.6 and Ollama. Explore file handling, image loading, API integration, and data management in this practical tutorial on building an image captioning application.
Florence-2: The Best Small Vision Language Model - Capabilities and Demo
Explore Florence-2, a powerful new Vision Language Model capable of detailed image captioning, visual grounding, and open vocabulary detection, with demonstrations and practical usage examples.
Narrated Reality
Explore neural networks for creative language applications, from expressive image captioning to AI-generated screenplays, with insights on new interfaces and forms for written expression.
Deep Learning and NLP with Spark
Explore deep learning and NLP using Spark, focusing on LSTM neural networks for complex language tasks. Includes real-time visualizations and Spark Notebook demonstrations.
에이닷의 이미지 이해와 생성 기술 발전 - AI 이미지 대화와 모션 프로필 서비스
Discover how A.dot evolved to understand and generate images, featuring insights into AI image dialogue systems and motion profile services using advanced Vision AI technology and LLM integration.
Creating Image Captioning Models: Overview and Components
Learn to build deep learning image captioning models, exploring encoder-decoder architecture, training techniques, and evaluation methods for accurate visual descriptions.
VirTex- Learning Visual Representations from Textual Annotations
Explore VirTex, a novel approach to visual representation learning using high-quality image captions, outperforming traditional methods with fewer images for various computer vision tasks.
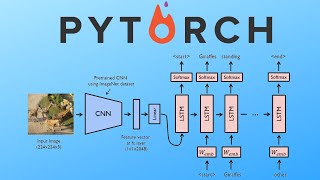
Pytorch Image Captioning Tutorial
Learn to build an image captioning system from scratch using PyTorch, covering CNN and RNN implementation, training setup, and evaluation on the Flickr8k dataset.
Unlocking New Video and Image Use Cases with Imagen on Vertex AI
Explore AI-powered image and video analysis for enhanced accessibility, training, recommendations, and search using Vertex AI's generative features.