EfficientML.ai: Quantization Part II - Lecture 6
Explore advanced quantization techniques for efficient machine learning, covering post-training and quantization-aware training methods to optimize model performance.
Quantum Algorithms and Parallel Architectures - New Results and Summary
Explore new findings in quantum algorithms and parallel architectures, comparing methods and machine learning parameters for advanced computational approaches.
Speech and Language Processing: Where Have We Been and Where Are We Going - 2003
Explore the past, present, and future of speech and language processing with insights on technological trends, data mining, and shifting priorities in the field.
Amazon Redshift Internals - Lecture 24
Explore Amazon Redshift's architecture, design principles, and performance optimizations with insights from a guest lecturer and former CMU PhD graduate.
Vectorized Query Execution Using SIMD - Lecture 6
Explore vectorized query execution using SIMD in advanced database systems, focusing on performance optimization techniques and modern hardware utilization.
UEFI and the Task of the Translator: Cross-Architecture UEFI Quines for Exploit Development
Explore UEFI exploit development using cross-architecture UEFI quines as a framework, enhancing your understanding of low-level system vulnerabilities.
Research Ops - Challenges and Practical Solutions for Distributed Scientific Computing
Explore challenges and practical solutions for distributed scientific computing in research operations, focusing on advanced cyberinfrastructure.
Exascale Computing: From Shared Memory to GPU Architecture
Explore exascale computing, HPC architectures, and GPU programming with Dr. Meifeng Lin from Brookhaven National Laboratory.
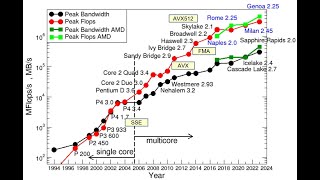
A Review of Processor Advances Over the Past Thirty Years - An Outsider's Perspective
Explore 30 years of processor advancements, focusing on x86 chips in HPC systems. Analyze core properties, memory hierarchy, and compare with Apple Silicon architecture.
What Do You Mean by Cache Friendly - Optimizing Data Structures for CPU Performance
Explore cache-friendly data structures and algorithms in C++. Learn techniques to analyze and improve cache efficiency, optimizing performance through memory layout and access patterns.
C++ Function Multiversioning in Windows - Load-time Implementation Selection - Lecture
Explore C++ function multiversioning for Windows, optimizing performance across diverse machines without runtime overhead. Learn implementation details, compiler-OS integration, and real-world applications.
GPU Accelerated Computing and Optimizations on Cross-Vendor Graphics Cards with Vulkan and Kompute
Explore GPU acceleration and optimizations for cross-vendor graphics cards using Vulkan & Kompute. Learn to implement GPU-accelerated machine learning algorithms and leverage hardware capabilities for performance improvements.
Follow the Data: Memory-Centric Designs for Modern Datacenters
Explore data-driven approaches for memory architecture in exascale supercomputing and cloud memory disaggregation. Gain insights into system-level memory problems and their solutions.
A Chiplet-Based Generative Inference Architecture with Block Floating Point Datatypes
Explore a chiplet-based architecture for generative inference, featuring block floating point datatypes and optimizations for large language models in AI accelerated computing.
C++11 to C++23 in the C++ Memory Model - Lecture
Explore C++ memory model evolution from C++11 to C++23, covering threading, optimization, and best practices for robust, thread-safe code development.
Zero Knowledge Proofs and ZK Programming in Blockchain Application Development
Explore zero knowledge proofs and implement a zkRollup system in Circom. Learn SNARK technology, Circom programming, and integrate with Hyperledger Besu or Fabric for blockchain applications.
Probabilistic Circuits
Explore probabilistic circuits with Antonio Vergari, covering foundational concepts and advanced applications in AI and machine learning.

EfficientML.AI Lecture - Machine Learning Efficiency and Optimization
Master efficient machine learning techniques and optimization strategies for deploying ML models in resource-constrained environments, focusing on practical implementation methods.

EfficientML.AI - Introduction to Efficient Machine Learning
Master efficient machine learning techniques and optimization strategies for deploying ML models in resource-constrained environments, focusing on practical implementation methods and performance enhancement.
Building Scalable and Effective Data Pipelines with Argo for Large-Scale Metadata Processing
Discover how to build high-performance data pipelines using Argo's parallelization techniques, achieving massive scale with 450% faster processing times and efficient metadata ingestion for large-scale data operations.
Optimizing LLM Efficiency One Trace at a Time on Kubernetes
Discover how to optimize LLM deployments on Kubernetes using OpenTelemetry's profiling features to identify resource bottlenecks, improve performance, and reduce operational costs through efficient monitoring.