Emission and Emissive Materials - Ray Tracing Series
Explore emission and emissive materials in ray tracing, enhancing your ability to create realistic lighting effects and improve the visual quality of rendered scenes.
Less Talking, More Learning - Avoiding Coordination in Parallel Machine Learning Algorithms
Strategies for scaling machine learning on parallel platforms, focusing on coordination-free algorithms to maximize computation time and discussing challenges in performance analysis.
Concrete Applications of Submodular Theory in ML and NLP
Explore submodularity's applications in machine learning and NLP, including dynamic graphical models, clustering, summarization, and more. Learn how it enables efficient algorithms with quality guarantees.
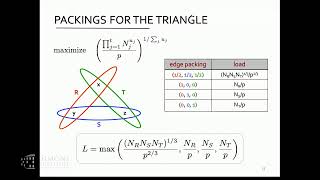
Massively Parallel Evaluation of Relational Queries I
Explore advanced techniques for parallel processing of relational database queries, focusing on fine-grained complexity and efficient evaluation strategies.
Overcoming GPU Shortages with Virtual Kubelets and Distributed Cloud
Explore innovative solutions to GPU shortages using virtual Kubelets and distributed cloud technology, with practical demonstrations and expert insights.
Running Distributed TensorFlow on DC/OS
Learn to run distributed TensorFlow on DC/OS, addressing challenges in large-scale machine learning. Explore framework design, live demo, and practical implementation for efficient model training on your infrastructure.
Energy Aware Scheduler (EAS) for big.LITTLE ARM SoCs - An Unbiased Analysis
Explore the Energy Aware Scheduler for big.LITTLE ARM SoCs, its essentials, alternatives, and vendor variations. Gain insights into its strengths and weaknesses for efficient heterogeneous computing.
Adapting Kubernetes for Machine Learning Workflows
Explore how Bloomberg adapted Kubernetes for machine learning, addressing multi-tenancy, data security, and hardware acceleration in their AI-driven financial services platform.
Distributed Deep Learning on Apache Mesos with GPUs and Gang Scheduling
Explore distributed deep learning on Apache Mesos, leveraging GPU clusters for efficient model training in self-driving cars, trip forecasting, and fraud detection at UBER.
Perspective in 3D - Vector Math and Ray Tracing for Financial Data Analysis
Explore vector math, ray tracing, and creative engineering as Perspective's expression language is repurposed for 3D graphics, blending financial analysis with game engine concepts.
Automatic Operator Generation for Open AI Frameworks - MindSpore and AKG
Explore AKG, an automatic AI/DL operator generation solution for MindSpore. Learn about its architecture, capabilities, and role in optimizing performance for various hardware platforms.
Co-Location of CPU and GPU Workloads for High Resource Efficiency in Kubernetes
Explore efficient co-location of CPU and GPU workloads in Kubernetes, including QoS class creation, cgroup management, gang scheduling, and utilization evaluation for improved resource efficiency.
Multi-Cloud Machine Learning Data and Workflow with Kubernetes
Explore building a multi-cloud ML platform using Kubernetes for autonomous vehicles, addressing data management, scheduling, and hardware support across diverse environments.
Fast and Accurate Deep Neural Networks Training
Exploring LARS and LAMB optimizers for scaling deep learning on supercomputers, enabling faster training and higher accuracy in AI applications across various industries.
Auto-scalable Microservices for Machine Learning - UnifyID Case Study
Scaling Machine Learning backend for 1M+ users: GPU-intensive computations, containerization on EC2, horizontal scaling, uniform API for ML microservices, and addressing production deployment challenges.
From Arm to Z - Building, Shipping, and Running a Multi-platform Docker Swarm
Learn to build, deploy, and run multi-architecture Docker services using manifest lists, emulation, and heterogeneous Swarms. Gain practical skills for creating cross-platform applications and managing diverse CPU architectures.
MegaScale - Scaling Large Language Model Training to More Than 10,000 GPUs
Innovative system for training large language models on 10,000+ GPUs, addressing efficiency and stability challenges through full-stack optimization and advanced diagnostic tools.

Fine-tuning LLMs 30x Faster - Unsloth AI's Approach
Discover techniques to accelerate LLM fine-tuning 30x with Daniel Han from Unsloth AI. Explore bug-hunting processes, optimization strategies, and insights into ML research reproducibility.

Optimizing a Ray Tracer by Building a Bounding Volume Hierarchy (BVH)
Optimize ray tracing performance by building a Bounding Volume Hierarchy (BVH). Learn techniques like GPU-friendly data structures, iterative traversal, and surface area heuristics to render complex scenes efficiently.
V-Express AI Talking Avatar Generator Tutorial - Cloud Installation and Usage Guide
Learn to use V-Express, an open-source tool for creating AI-powered talking avatars from static images. Covers installation and usage on various cloud platforms, including Massed Compute, RunPod, and Kaggle.

Fine-Tuning Llama 3 on a Custom Dataset for RAG Q&A - Training LLM on a Single GPU
Learn to fine-tune Llama 3 on custom datasets for improved LLM performance in specific tasks, using a single GPU. Covers dataset preparation, model setup, training, and evaluation.