High Performance Computing
Comprehensive exploration of advanced parallel computing techniques, covering MPI, OpenMP, GPU acceleration, and applications in scientific domains. Includes hands-on exercises for practical skill development.
Running ML Inference Services in Shared Hosting Environments
Optimize ML inference in shared hosting: Learn to boost latency, throughput, and resource utilization through queue management and OpenMP tuning.
Fortran with OpenMP
Learn parallel programming in Fortran using OpenMP. Master threads, clauses, work sharing, and optimization techniques for high-performance computing applications.
Shared Memory Parallelism in Julia with Multi-Threading - Parallel Depth-First Scheduling
Explore efficient shared memory parallelism in Julia using multi-threading, focusing on nested parallelism and the parallel depth-first scheduling approach for improved performance.
Exploit Parallelism for AI Workloads with WASM and OpenMP
Explore optimizing AI workloads using WebAssembly and OpenMP for multithreaded, shared memory, and vectorized operations, focusing on challenges and benefits in cloud computing environments.
OpenMP for Better High-Level Parallelism, Not Just for High Performance Computing
Explore OpenMP for efficient shared memory parallelism in C++, C, and FORTRAN. Learn its versatile applications beyond high-performance computing, from graphics to finance and data analysis.
Parallel Design Patterns and Stream Parallelism
Explore parallel design patterns and stream parallelism using GrPPI, an experimental library for expressing parallelism through patterns, with focus on composability and multiple back-end support.
A Discussion of Selected Vienna-Libraries for Computational Science
Explore Vienna-Libraries for computational science: ViennaCL, ViennaGrid, ViennaData, ViennaMath, and ViennaFEM. Learn how C++ can better meet scientific computing needs.
SpEQ: Translation of Sparse Codes Using Equivalences
Discover SpEQ, a strategy for detecting semantics in sparse codes and translating to high-performance libraries. Learn about its implementation, evaluation, and performance gains across various backends.
Exascale Computing: From Shared Memory to GPU Architecture
Explore exascale computing, HPC architectures, and GPU programming with Dr. Meifeng Lin from Brookhaven National Laboratory.
Facilitating Electronic Structure Computations on GPU-based Exascale Platforms
Explore GPU-based electronic structure computations for exascale platforms using PROGRESS and BML libraries. Learn implementation strategies, performance optimization, and scaling techniques.
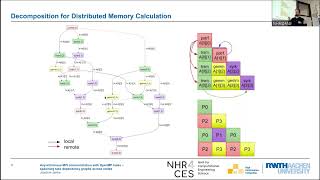
Asynchronous MPI Communication with OpenMP Tasks - Spawning Task Dependency Graphs Across Nodes
Explore asynchronous MPI communication with OpenMP tasks to improve parallel code scalability. Learn to integrate MPI detached communication for real asynchronous execution across processes.
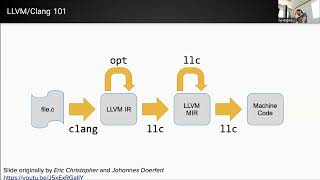
LLVM in HPC - Enabling Performance Portability, Interoperability, and Novel Features - Part 1
Explore LLVM's impact on HPC, covering portable CUDA, debugging at scale, GPU execution of legacy code, and ML in compilers. Learn about efforts to enhance performance, tooling, and development in HPC.
C++ Performance Portability - A Decade of Lessons Learned - Lecture
Explore a decade of C++ performance portability challenges and solutions, focusing on Kokkos ecosystem development for efficient cross-platform scientific computing.

Pathfinder to GPU Offload in WASM
Explore GPU offloading in WebAssembly for AI workloads, discussing integration challenges and potential solutions to enhance security and performance in cloud environments.