ML Training Acceleration with Heterogeneous Resources in ByteDance
探讨如何利用字节跳动的异构计算资源加速机器学习模型训练,包括GPU共享机制、NUMA亲和性资源分配和RDMA网络通信等技术。
Boost ML on Heterogeneous AI Accelerators with Ray on Kubernetes
探讨如何在Kubernetes上利用Ray和图编译器自动提升异构AI加速器的机器学习性能,无需修改用户代码,实现透明的后端加速。
Unlocking Heterogeneous AI Infrastructure K8s Cluster: Leveraging the Power of HAMi
Explore HAMi project for managing diverse AI devices in K8s clusters. Learn unified scheduling, GPU sharing, flexible policies, and real-world case studies to optimize heterogeneous AI infrastructure.
Security of Heterogeneous Systems
Explore microarchitectural attacks on heterogeneous systems, focusing on GPU vulnerabilities. Learn about covert channels, website fingerprinting, and defense strategies for integrated CPU-GPU architectures.
The OpenAMP Project: Standardizing Interactions in Heterogeneous Embedded Systems
Explore standardization of interactions in heterogeneous embedded systems, OpenAMP project history, working groups, and future developments for simplified software environments.
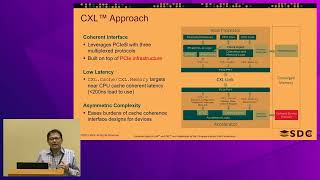
CXL Enabling an Interoperable Ecosystem for Heterogeneous Memory and Computing Solutions
Explore the CXL 3.0 specification's advanced features for heterogeneous computing, including enhanced memory sharing, coherency improvements, and expanded fabric capabilities for high-performance workloads.
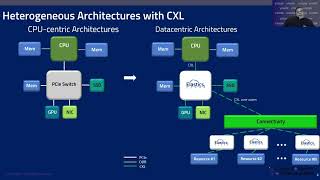
Server Fabrics and the Evolution to CXL 3.0 - Memory and Resource Management in Heterogeneous Computing
Explore the evolution of CXL technology and server fabrics, focusing on memory management, resource pooling, and system architecture improvements for enhanced computing performance.
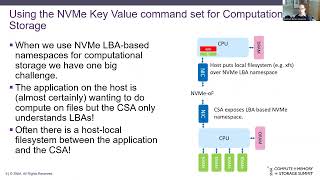
Big-Disk Computational Storage Array for High Performance Data Analytics
Explore high-performance computational storage solutions for data analytics, focusing on UCIe standards, chiplet interoperability, and power-efficient performance across cloud, edge, and client computing infrastructures.
SIGCOMM 2020 - Reducto - On-Camera Filtering for Resource-Efficient Real-Time Video Analytics
Explore real-time video analytics optimization with Reducto, a filtering technique for efficient on-camera processing. Learn about system design, performance results, and practical applications.
A Fast and Flexible CFD Solver with Heterogeneous Execution - JuliaCon 2024
Explore WaterLily.jl: a fast, flexible CFD solver for CPUs and GPUs. Learn about its meta-programming approach, performance, and potential for ML integration and differentiability.
Empower Heterogeneous Edge AI Acceleration with Kubernetes
Unified framework for empowering heterogeneous edge AI accelerators on Kubernetes, addressing challenges in detection, provisioning, and boosting ML frameworks for efficient edge computing.
TornadoVM: Heterogeneous Programming Framework for Java
Explore TornadoVM, a Java framework for heterogeneous computing on CPUs, GPUs, and FPGAs. Learn its API, compiler, and runtime system for optimized performance across diverse hardware.
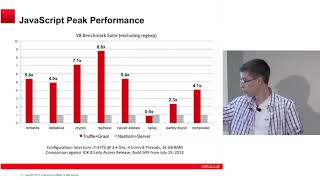
Graal and GPU Offload - Architecture and Implementation
Explore Graal architecture, GPU offloading, and HSAIL backend for Java performance optimization. Learn about Truffle, JavaScript peak performance, and special considerations for GPU compilation.
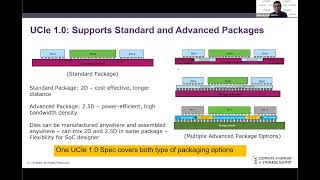
UCIe: An Open Standard for Package-Level Innovations in Computing Systems
Explore UCIe open standard for package-level innovations, covering key metrics, adoption criteria, and usage models for high-performance computing and heterogeneous processing integration.
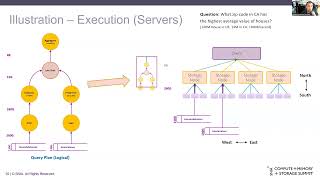
Decomposing Compute to Grow Computational Storage - Dynamic Query Partitioning in Storage Systems
Explore dynamic query partitioning in computational storage systems and learn how decomposable queries can optimize performance across storage device hierarchies for enhanced data processing capabilities.
Cross-Architecture Dynamic Migration Solution for Heterogeneous AI Acceleration Systems
Discover a unified solution for seamless application migration across diverse AI accelerators, enabling cross-architecture compilation and dynamic runtime adaptation without code modifications.
SoC Construction Using Universal Chiplet Interconnect Express (UCIe) - A Game Changer
Explore the Universal Chiplet Interconnect Express (UCIe) standard and its revolutionary impact on SoC construction, chiplet integration, and high-performance computing applications.
Heterogeneity-Aware Algorithms for Federated Learning and Distributed Optimization
Delve into advanced federated learning algorithms, focusing on heterogeneity challenges in distributed model training and innovative solutions for edge computing optimization.
How openEuler is Powering Tomorrow's AI and Smart Infrastructure
Explore openEuler's innovations in AI infrastructure and heterogeneous computing, including cloud-native solutions and openEuler NEXT, designed to optimize AI workflows and enhance user experience.
Docker Multi-arch: Extending to Windows, ARM, and IBM Platforms
Explore Docker's extension to Windows, ARM, and IBM platforms, covering multi-architecture images, heterogeneous swarms, and cross-platform deployment strategies.
Docker Containers for Machine Learning on Specialized AI Hardware
Explore Docker's role in scaling machine learning across heterogeneous systems with multiple processors, including GPUs and AI accelerators. Learn about container benefits and future trends in multi-processor ML workloads.