Implementing Understandable World Class Hash Tables in C++ - CppCon 2022
Explore world-class hash table implementation in C++, focusing on Robin Hood hashing, parallel computation, and SIMD operations. Learn to optimize performance while maintaining code clarity and understandability.
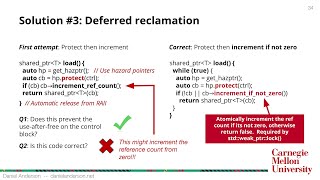
Lock-free Atomic Shared Pointers Without a Split Reference Count - Implementation Strategies
Explore lock-free atomic shared pointers implementation without split reference count. Learn an elegant solution using hazard pointers for improved performance in concurrent C++ programming.
Unlocking Modern CPU Power - Next-Gen C++ Optimization Techniques
Explore cutting-edge C++ optimization techniques for modern CPUs, covering architecture changes, benchmarking challenges, and practical strategies to enhance code performance on latest processors.
ASTRA-sim and Chakra - Co-design Exploration for Distributed Machine Learning Platforms
Explore co-design methodologies for distributed ML platforms using ASTRA-sim and Chakra frameworks, focusing on system optimization and performance analysis.
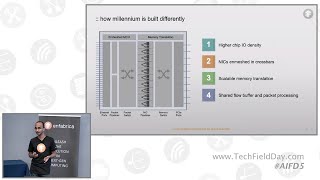
Solving I/O Scaling Challenges in Accelerated Compute with Networking Silicon
Discover how Enfabrica's Accelerated Compute Fabric revolutionizes I/O scaling in compute clusters through innovative networking silicon integration, optimizing data movement and enhancing GPU communication efficiency.
Powering Llama 3 - A Peek into Meta's Massive Infrastructure for Generative AI
Dive into Meta's advanced infrastructure powering Llama 3, exploring the technological backbone and innovative systems behind their next-generation generative AI development.
Tensor Query Processing - Accelerating Database Analytics with AI Hardware
Discover how Microsoft's framework compiles SQL to tensor abstractions, enabling efficient database analytics on GPUs and exploring the fusion of SQL with machine learning capabilities.
Принципи роботи HPC на прикладі комп'ютерного кластеру
Дізнайтеся про принципи роботи високопродуктивних обчислень (HPC) на реальному прикладі комп'ютерного кластера, його архітектуру та практичне застосування.
Foundation of GPU Programming
Explore GPU architecture, performance sources, and programming models. Gain insights into SIMD processing, DRAM parallelism, and software/memory hierarchies for confident GPU utilization.
Compile-Time Sparse Matrices - Optimizing Memory and Performance
Explore compile-time sparse matrices for efficient memory use and performance in C++ linear algebra. Learn to incorporate sparseness information, reduce storage, and optimize operations automatically.
Ascent: In Situ Visualization and Analysis for HPC Simulations - Tutorial 2024
Learn to use Ascent, an open-source in situ visualization and analysis tool for HPC simulations. Explore its capabilities for multi-physics applications on many-core architectures.
Small but Mighty: Subset Selection and Knowledge Distillation
Explore cost-efficient AI training methods, focusing on subset selection and knowledge distillation techniques to address challenges in large language model development.
Distributed Training for Efficient Machine Learning - Part I - Lecture 17
Explore distributed training techniques for machine learning, focusing on data and model parallelism strategies to enhance efficiency and scalability.
Distributed Training - Part I - Lecture 17
Explore distributed training techniques for efficient machine learning, covering key concepts and strategies for scaling ML models across multiple devices.
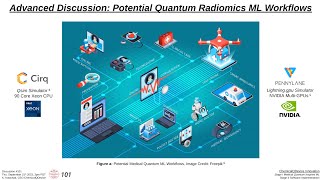
Advanced Discussion: Potential Quantum Radiomics ML Workflows
Explore quantum machine learning workflows for medical imaging, focusing on efficient state vector circuits, pure state representations, and exact expectation values. Discover recent advancements in large-scale quantum simulations.
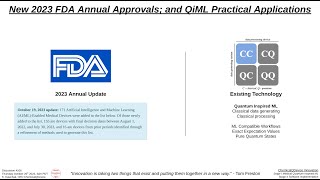
New 2023 FDA Annual Approvals and QiML Practical Applications
Explore FDA's 2023 AI/ML medical device approvals and quantum-inspired machine learning applications in healthcare, focusing on practical R&D potential for medical submissions.
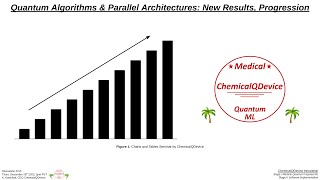
Quantum Algorithms and Parallel Architectures - New Results and Summary
Explore new findings in quantum algorithms and parallel architectures, comparing methods and machine learning parameters for advanced computational approaches.
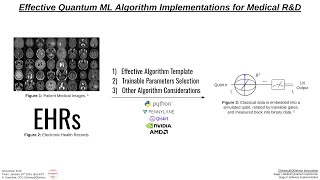
Effective Quantum ML Algorithm Implementations for Medical R&D
Explore quantum AI algorithms for medical R&D, focusing on embeddings, variational layers, and GPU implementations to enhance traditional approaches.
Vectorized Query Execution Using SIMD - Lecture 6
Explore vectorized query execution using SIMD in advanced database systems, focusing on performance optimization techniques and modern hardware utilization.
Introduction to CUDA Programming for Physicists - Lecture 3
Explore GPU architecture, memory operations, CUDA kernels, and reduction operations. Learn to accelerate critical code sections using GPUs for physics computations.
Introduction to CUDA Programming for Physicists - Lecture 2
Explore GPU architecture, memory operations, CUDA kernels, and reduction techniques for physicists. Learn to accelerate critical code sections using GPUs and leverage specialized libraries.