Optimizing HDRP with NVIDIA Nsight Graphics
Learn to optimize HDRP applications using NVIDIA Nsight Graphics for peak performance. Explore profiling tools, debugging techniques, and real-time ray tracing optimization strategies.
NPK - High-Powered, Open Source Hash Cracking Tool
Explore NPK, an open-source tool for high-powered hash cracking using AWS GPU instances. Learn its features, benefits, and how it enables cost-effective password security assessment.
Concurrency and Parallel Computing in JavaScript
Explore concurrency and parallel computing in JavaScript, covering actors, futures, and throughput computing in browsers. Learn techniques for leveraging modern parallel hardware in web development.
Thinking DSLs for Massive Visualization
Explore domain-specific languages for parallel computing and program synthesis in massive interactive visualizations, focusing on Superconductor's innovative approach to browser-based data visualization.
Unison - A New Distributed Programming Language
Explore Unison, a functional language for distributed systems. Learn its unique features, including self-deployment, elastic scaling, and simplified code management for building complex distributed applications.
PyTorch - Fast Differentiable Dynamic Graphs in Python
Explore PyTorch's dynamic deep learning framework, its high-performance design, and tensor compiler for faster AI research and development using GPUs and CPUs.
Haxl - A Big Hammer for Concurrency
Explore Haxl, Facebook's framework that flips the default from sequential to concurrent programming, enhancing I/O, concurrency, testing, and debugging in software development.
C++ Parallel Programming Models
Explore C++'s parallel programming models: unstructured, task-based, and data parallel. Learn key facilities, use cases, and recent features for efficient parallel programming in modern C++.
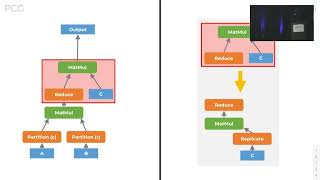
Unity - Accelerating DNN Training Through Joint Optimization of Algebraic Transformations and Parallelization
Explore Unity, a system optimizing distributed DNN training through joint algebraic transformations and parallelization. Learn about its unified parallel computation graph and hierarchical search algorithm for improved performance.
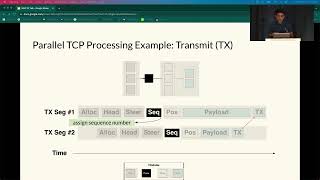
FlexTOE - Flexible TCP Offload with Fine-Grained Parallelism
Explore FlexTOE, a high-performance TCP offload engine for SmartNICs. Learn about its flexible design, fine-grained parallelism, and performance benefits in various network scenarios and hardware architectures.
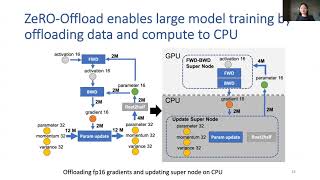
ZeRO-Offload - Democratizing Billion-Scale Model Training
ZeRO-Offload: Enabling billion-scale model training on a single GPU by offloading data and compute to CPU, minimizing data movement, and optimizing efficiency. Scales to multiple GPUs and works with model parallelism.
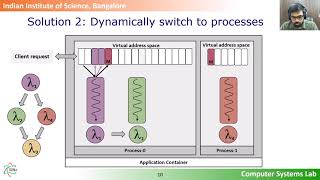
Faastlane - Accelerating Function-as-a-Service Workflows
Accelerating FaaS workflows by executing functions as threads, providing lightweight isolation, and dynamically identifying parallelism opportunities to enhance performance and reduce latency.
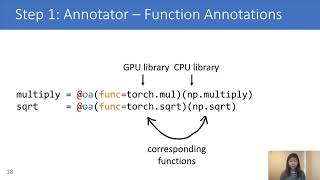
Offload Annotations - Bringing Heterogeneous Computing to Existing Libraries and Workloads
Explore offload annotations for efficient GPU computing in existing libraries, enabling seamless integration and performance gains without extensive code modifications.
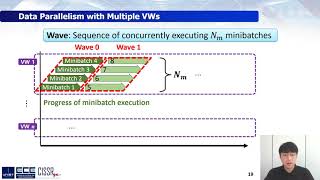
HetPipe - Enabling Large DNN Training on Heterogeneous GPU Clusters through Integration of Pipelined Model Parallelism and Data Parallelism
Explores HetPipe, a system integrating pipelined model parallelism and data parallelism for training large DNNs on heterogeneous GPU clusters, improving performance and enabling use of less powerful GPUs.

Systems That Run Forever - Self-Heal and Scale
Explore architectural principles for building scalable, fault-tolerant systems using isolated parallel components, error detection, and live code upgrades, with insights from Erlang's design.
Practical New Developments in The Breach Attack
Explore advanced techniques for exploiting SSL vulnerabilities, including new methods to bypass encryption, optimize attacks, and implement persistent command-and-control strategies. Novel mitigation approaches are also discussed.
GPU Programming with Modern C++
Explore GPU programming with modern C++, covering parallelism fundamentals, heterogeneous computing, and SYCL for GPU dispatch. Learn to optimize performance and leverage multi-core architectures effectively.
Scala Goes Native
Explore Scala's expansion beyond JVM with a new ahead-of-time compiler and lightweight managed runtime, opening doors to native development and enhanced performance.
OpenMP for Better High-Level Parallelism, Not Just for High Performance Computing
Explore OpenMP for efficient shared memory parallelism in C++, C, and FORTRAN. Learn its versatile applications beyond high-performance computing, from graphics to finance and data analysis.
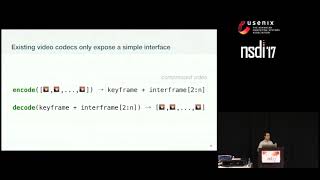
Encoding, Fast and Slow - Low-Latency Video Processing Using Thousands of Tiny Threads
Innovative video processing system using cloud functions and parallel computing for low-latency editing and encoding of high-resolution videos, including 4K and VR content.
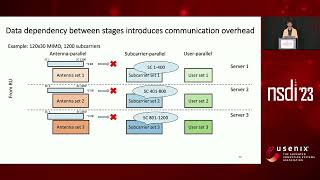
Scalable Distributed Massive MIMO Baseband Processing
Innovative system for scaling massive MIMO baseband processing in software-defined radio networks. Reduces inter-server communication to support larger MIMO configurations, enhancing 5G network capacity.