Why Communication is the Best Skill You Can Develop as a Programmer
Desarrolla habilidades de comunicación esenciales para programadores. Mejora la comprensión de requisitos, revisiones de código y colaboración en equipo.
DBT and Python - How to Write Reusable and Testable Pipelines
Develop reusable and testable data pipelines using DBT and Python. Learn best practices for version control, DAGs, and unit testing in SQL and Python-based models.
The Imposter Staff Engineer's Journey to Leadership
Explore a staff engineer's journey through imposter syndrome, leadership challenges, and unexpected triumphs while leading a team to create innovative solutions.
Why ML in Production is Still Broken
Explore challenges in deploying ML projects to production, focusing on the disconnect between development and real-world application. Learn key aspects distinguishing ML from traditional software engineering.
ML Monitoring ML: Scalable Monitoring of ML Models in Production Environments
Explore scalable ML model monitoring in production. Learn key performance measures, anomaly detection techniques, and an open-source agent for automated tracking and alerting of model issues.
MLOps at Scale: Predicting Bus Departure Times Using 18,000 ML Models
Explore MLOps at scale through a case study on predicting bus departure times using 18,000 ML models. Learn practical insights for implementing large-scale machine learning projects.
MLOps Without Much Ops - Building Efficient Machine Learning Systems
Discover modern, no-nonsense data pipelines for efficient machine learning systems. Learn PaaS advantages and explore real-world applications with open-source code. Gain insights on ML's future for organizations of all sizes.
Your R&D Project Looks Promising - Now What?
Explore strategies for transitioning promising R&D projects into production, covering key considerations and best practices for successful implementation.
Speeding Up Innovation with Cloud-Native and Continuous Delivery
Discover modern best practices for accelerating innovation through continuous delivery, cloud-native architecture, and chaos engineering, drawing from global organizational experiences and practical implementations.
Transforming Search with AI - Perplexity's Approach to Answer Engines
Explore AI-powered search innovation with Perplexity's CTO, discussing technical challenges, speed optimization, and the future of AI in delivering precise, fast answers to user queries.
Simplify GenAI App Development with Secure, Custom AI Agents
Explore best practices for managing AI model lifecycles, focusing on governance, monitoring, and performance tracking to ensure compliance and optimize delivery in production environments.
Solving Optimization Problems on Databricks for the Ad Industry
Explore scalable optimization techniques for ad industry using Databricks. Learn algorithms and tuning methods to process data efficiently and solve large-scale problems while integrating with existing infrastructure.
Data Warehousing Performance, Scale and Security with Databricks SQL
Explore high-performance data warehousing with Databricks SQL, focusing on scalability, security, and resource management for enterprise environments. Learn about latest advancements in scheduling and caching.
Optimizing Lakehouse Architecture Costs with Intel Software and Databricks
Enhance large-scale data processing for AI with autonomous CPU optimization, cost-effective resource management, improved scalability, and streamlined Spark operations using Intel's solutions for Databricks Data Intelligence Platform.
Scale Your Databricks Workloads up to 15k Nodes on Google Cloud
Explore how Databricks on Google Cloud leverages GKE for scalability, enabling AI/ML infrastructure to handle growing demands. Learn from NEAR's experience and discover extensive integrations with Google Cloud services.
Simplifying Data Ingestion for LLMs with Unstructured and Databricks
Learn to build a scalable solution for unstructured data ingestion in LLM applications using Unstructured and Databricks, addressing challenges and exploring efficient methods.
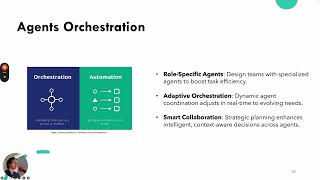
Orchestrating LLM AI Agents with CrewAI
Explore CrewAI for orchestrating LLM AI agents. Learn fundamentals, challenges, and real-world applications. Discover how to enhance LLM efficiency across industries with this open-source platform.
Technical Interviews Don't Have to Suck
Discover practical strategies to transform technical interviews into welcoming, useful, and enjoyable experiences for all parties involved.
On Parenthood, Systems Thinking, and App Development
Explore parallels between parenting and software engineering, focusing on managing complexity and adapting to change using Ember's systems thinking approach.

Unlocking the Power of Apache Flink - An Introduction in 4 Acts
Explore Apache Flink's core principles for real-time data processing, including shared-nothing architecture, event-time processing, and state snapshots, through practical examples and demos.
Streaming vs. Batch Processing: The Future of Data Architecture
Explore the future of data processing with industry experts as they debate streaming vs. batch, adoption challenges, and best practices for real-time data architecture.