Navigating the Challenges of Offer Categorization in E-commerce - Strategies for Accurate and Scalable Classification
Explore strategies for accurate and scalable offer categorization in e-commerce, addressing challenges, leveraging automation, and improving search relevance and product sorting.
Leveraging Open-Source Tools for Building a Quality Data Warehouse
Discover how to build a quality data warehouse using open-source tools. Learn about modern data stack architecture, test-driven approaches, and software development best practices for data transformation.
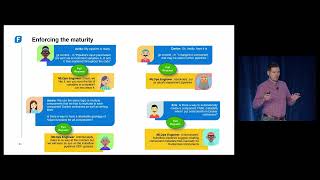
Fully Automated ML Platform Using Kubeflow and Declarative Approach to End-to-End ML Development
Explore FreshBooks' journey to MLOps maturity using Kubeflow pipelines and a declarative framework, addressing challenges and improving ML pipeline reliability from development to production.
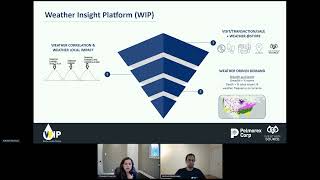
Challenges and Learnings of Machine Learning at Scale
Explore challenges and learnings of training millions of models efficiently, optimizing costs, and achieving high-performance daily predictions in machine learning.
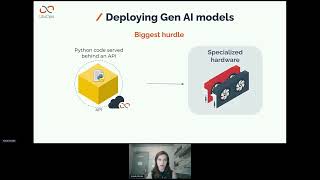
Deploying Generative AI Models - Best Practices and Interactive Example
Explore best practices for deploying generative AI models at scale, with an interactive example using UbiOps for serverless and cloud-agnostic implementation.
Inference at Scale with Apache Beam
Learn to deploy and scale machine learning models efficiently using Apache Beam for distributed inference on CPUs and GPUs, with practical insights on parallelizing workloads.
Through the Looking Glass: Key Architectural Choices in Flink and Kafka Streams
Explore architectural differences between Apache Flink and Kafka Streams, gaining insights into stream processing fundamentals and design choices for improved system performance.
Solr Eclipse - Zomato's Journey to 64 Million Search Queries a Day
Explore Zomato's journey scaling Apache Solr to handle 64 million daily searches across 100 million restaurant items in 13 languages, powering their homepage and overcoming technical challenges.
Git for Data Lakes: How LakeFS Scales Data Versioning to Billions of Objects
Learn how lakeFS enables Git-like versioning for data lakes, solving challenges of object storage and scaling to billions of objects without compromising performance. Explore branching, committing, and merging for petabyte-scale data management.

Delta Format and Live Tables - Pioneering Data Innovation
Explore Delta format and Live tables, understanding their role in scalable big data pipelines and modern data engineering innovations.

Spark Unveiled: Essential Insights for All Developers
Discover Apache Spark's core concepts, architecture, and impact on data processing. Gain essential insights to enhance your development skills and unlock Spark's potential.

State Storage in Spark Structured Streaming
Learn to configure and manage state storage in Spark Structured Streaming for efficient data processing and analysis.
From a Rebellious Individualist to Embracing Mentorship - Lessons Learned
Explore the journey from skeptical mentee to dedicated mentor, uncovering the vital role of mentorship in professional growth and career development.

Building Machine Learning Solutions with Python - Code Walkthrough
Develop a semantic search tool for YouTube videos using Python, focusing on experimentation, evaluation, and UI building in machine learning solutions.
Apache Celeborn: Making Spark and Flink Faster, More Stable and More Resilient
Explore Apache Celeborn's high-performance Shuffle service for Spark and Flink, enhancing stability, performance, and cost-efficiency in large-scale data processing environments.
Building a Real-Time Analytics Database
Odkryj tajniki tworzenia bazy danych do analityki w czasie rzeczywistym. Poznaj kluczowe koncepcje i najlepsze praktyki w tej dziedzinie.
Building a Successful Robotics Startup
Discover key strategies for launching a thriving robotics venture, from identifying market needs to scaling operations and securing funding.
Determinedly Deterministic: How It Can Help You as a Developer
Explore deterministic systems in financial exchanges, focusing on reliability, recovery, and high-performance Java coding for state machines and matching engines.
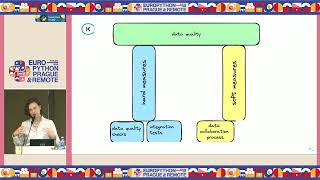
Don't Fix Bad Data, Do This Instead - Pragmatic Strategies for Data Quality
Explore pragmatic strategies for bridging the gap between data expectations and reality. Learn about integration tests, prioritization, and balancing technical and cultural measures in data quality management.
RPA, TDD, and Embedded - A World Glued Together with Python
Explore RPA, TDD, and embedded systems integration using Robot Framework and Python. Learn to maximize testing potential in microcontroller environments through practical examples.
Behind the Scenes of an Ads Prediction System
Explore the intricacies of ad prediction systems, from user targeting to ethical considerations. Gain comprehensive insights into developing efficient, high-volume ad prediction models and their real-world applications.