
Azure SQL for Beginners
Learn Azure SQL basics, deployment, security, performance, and availability. Gain hands-on experience through demos and challenges to effectively manage and optimize Azure SQL databases.
Productivity is Messing Around and Having Fun
Explore the connection between developer satisfaction, productivity, and business outcomes in this engaging conference talk. Discover how incorporating play and reducing friction in the workplace can lead to improved developer performance and job satisfa…
How to Improve Latency and CPU Isolation Without Cost
Aprenda técnicas para melhorar a latência e o isolamento de CPU sem custos adicionais, otimizando o desempenho de sistemas Linux.
Developing IO Prefetching for PostgreSQL
Explore IO prefetching in PostgreSQL, including algorithm development, simulation advantages, and evaluation techniques for improving database performance and efficiency.

Lesser Known Features of PostgreSQL
Discover lesser-known PostgreSQL features for efficient data manipulation, testing, and querying. Learn practical tips to enhance your database skills and streamline development workflows.
Optimizing Autovacuum - PostgreSQL's Vacuum Cleaner
Learn to optimize PostgreSQL's autovacuum for efficient database maintenance. Understand its workings, troubleshoot issues, and implement effective solutions to prevent bloat in production environments.
Optimization for Reducing Compute Cost of SparkSQL in ByteDance
Discover key optimization techniques for SparkSQL implementation at ByteDance, focusing on compute cost reduction strategies and performance enhancement methods.
Best Practices for Applications on Kubernetes - Frequent Updates and Stability
Explore best practices for Kubernetes applications, balancing frequent updates and stability. Learn container health checks, resource allocation, graceful shutdown, and Java-specific optimizations.
How We Build Production-Grade HPA: From Effective Algorithm to Risk-Free Autoscaling
探索创新的"基于流量驱动"副本预测算法和多阶段灰度扩展策略,以构建高效、稳定的Kubernetes水平自动扩展(HPA)解决方案,实现大规模资源节省和风险降低。
Optimiza la Velocidad de tu Código Python con Functools y NumPy Vectorize
Optimiza el rendimiento de Python utilizando functools y numpy vectorize para acelerar tus cálculos y mejorar la eficiencia del código.
Optimiza la Velocidad de tu Código Python con Numba JIT Compiler
Acelera tu código Python utilizando Numba y los decoradores JIT para optimizar el rendimiento y mejorar la eficiencia computacional.
Protecting Private Keys Against Memory Disclosure Attacks Using Hardware Transactional Memory
Explore hardware transactional memory for protecting cryptographic keys against memory disclosure attacks, enhancing security in both software and physical threat scenarios.
Making Bitbake PSI-chic: Regulating Builds Using /proc/pressure
Optimize bitbake builds using /proc/pressure to regulate task creation, maintaining system responsiveness without sacrificing throughput. Learn to set effective BB_PRESSURE_MAX variables.
Boost Delta Lake Performance with Data Skipping and Z-Order
Explore data skipping and Z-ordering techniques to enhance Delta Lake performance, focusing on optimized partitioning strategies for improved read and write efficiency in large-scale data lakes.
Delta Lake: Optimizing Merge Operations
Explore Delta Lake merge optimization techniques, including inner and full outer joins, partition pruning, and file pruning. Learn tips for handling large merges efficiently.
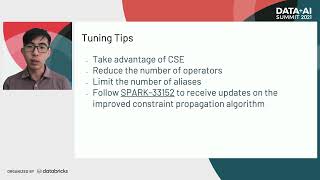
Optimizing Catalyst Optimizer for Complex Spark Plans
Optimizing Spark's Catalyst optimizer for complex plans with thousands of operators and large case statements. Techniques include memory-efficient logging, subexpression elimination, and improved constraint propagation.
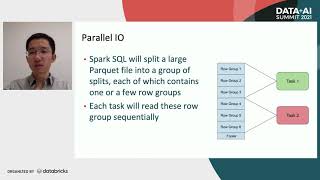
Optimizing Spark SQL Jobs with Parallel and Asynchronous IO
Optimizing Spark SQL jobs through parallel and async IO techniques, including file-level and row group-level parallel read, asynchronous spill, and parquet column family, resulting in 5-30% performance improvement.
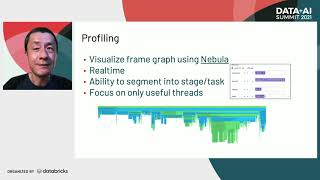
Migrating ETL Workflows to Apache Spark at Scale - Pinterest's Experience
Explore Pinterest's journey migrating ETL workflows to Apache Spark, covering challenges, solutions, and performance improvements. Learn about semantic gaps, thrift objects, and innovative Spark profiling techniques.
Accelerating Data Processing in Spark SQL with Pandas UDFs - Optimization Techniques
Learn to optimize Spark SQL data processing using Pandas UDFs. Discover techniques to speed up queries, profile jobs efficiently, and leverage custom UDFs for significant performance gains in large-scale data pipelines.
Hyperspace - An Indexing Subsystem for Apache Spark
Explore Hyperspace, an indexing subsystem for Apache Spark that enhances query performance and reduces resource costs. Learn about its design, implementation, and benefits for data analytics on large datasets.
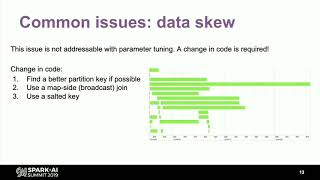
How to Automate Performance Tuning for Apache Spark
Discover techniques to automate Apache Spark performance tuning, addressing common issues and exploring tools for efficient, scalable data pipeline maintenance in production environments.