Building Resilience for Large-Scale AI Training: GPU Management, Failure Detection, and Beyond
Dive into GPU management strategies for large-scale AI training, covering failure detection, observability tools, and fault-tolerant distributed training principles to optimize performance and reduce costs.
Optimizing Load Balancing and Autoscaling for Large Language Model (LLM) Inference on Kubernetes
Discover practical techniques for optimizing LLM inference deployments on Kubernetes, focusing on load balancing, autoscaling, and efficient GPU resource utilization using KServe and Knative.
Optimizing LLM Performance in Kubernetes with OpenTelemetry
Master OpenTelemetry implementation for LLM deployments in Kubernetes, covering performance optimization, observability standards, troubleshooting techniques, and advanced autoscaling strategies.
GPU Configuration on the Fly Using Dynamic Resource Allocation - A Tale of Two Drivers
Discover how NVIDIA's GeForceNow optimizes GPU resource management using Dynamic Resource Allocation, enabling seamless driver switching and maximum GPU utilization in cloud gaming infrastructure.

Architecting the Future of AI: From Cloud-Native Orchestration to Advanced LLMOps
Dive into cloud-native AI architecture, exploring Kubernetes orchestration, Ray distributed computing, and vLLM for efficient large language model deployment and management.
Operationalizing High-Performance GPU Clusters in Kubernetes - Lessons Learned from Training Databricks DBRX
Dive into advanced strategies for managing large-scale GPU clusters in Kubernetes, focusing on monitoring, health detection, and solving complex failure scenarios in LLM training environments.
AI and ML: The Critical Operational Side of Running Applications in Kubernetes
Discover how to effectively manage AI and ML operations using service mesh, focusing on GPU workloads, multitenancy, and scaling in Kubernetes environments for reliable and observable ML applications.

Pathfinder to GPU Offload in WASM
Explore GPU offloading in WebAssembly for AI workloads, discussing integration challenges and potential solutions to enhance security and performance in cloud environments.
Azure AI Training and Fine-tuning Custom LLMs with Distributed Training
Master distributed training techniques for custom LLMs using Azure AI infrastructure, focusing on performance optimization, scalability, and efficient deployment with ND H100 and H200 series.
Building Serverless Intelligent Apps with Flex Consumption and GPUs
Master building high-performance serverless applications using Azure Functions Flex Consumption and Container Apps for AI workloads with GPU support and event-driven scalability.
Efficiently Process Complex AI Workloads with Azure ND MI300X v5 Technology
Discover how Azure's ND MI300X v5 VM series revolutionizes AI infrastructure with high-bandwidth memory and superior compute capabilities for accelerating complex AI model processing.
Co-dfns Compiler Roadmap and Updates - Implementation and Integration Features
Discover the latest developments in Co-dfns compiler for APL, exploring GPU integration, scalar optimization, static analysis, and traditional APL support through practical use cases and performance insights.
Enabling Fault Tolerance for GPU Accelerated AI Workloads in Kubernetes
Discover strategies for implementing fault tolerance in GPU-accelerated AI workloads on Kubernetes, covering hardware error handling, fault detection, and automated remediation techniques.
Accelerating the Next Generation of Multimedia with GPUs
Discover how to build high-performance live streaming services using the Babit Multimedia Framework (BMF), leveraging GPU acceleration and multi-language support for advanced video processing and broadcasting.
Building an Auto-scaling AI Inference Service - From Setup to Deployment
Master the fundamentals of building and scaling AI inference services, from GPU utilization to auto-scaling implementation, Docker configuration, and API endpoint setup for optimal performance.
Easy Monochrome Effect with GLSL in TouchDesigner
Master GLSL shader programming by creating a monochrome effect in TouchDesigner, leveraging GPU optimization for enhanced performance and parallel processing capabilities.
Distributed Training Methods and Parallelization Techniques - Lecture 19
Explore advanced distributed training concepts, from data parallelism and communication primitives to pipeline, tensor, and sequence parallelism methods for efficient machine learning systems.
Distributed Training: Hybrid Parallelism and Gradient Optimization - Lecture 20
Delve into advanced distributed training concepts, covering hybrid parallelism, gradient compression techniques, and strategies for optimizing bandwidth and latency in ML systems.
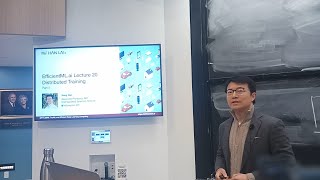
Distributed Training: Hybrid Parallelism and Gradient Optimization - Lecture 20
Delve into advanced distributed training concepts, exploring hybrid parallelism, gradient compression techniques, and strategies to overcome bandwidth and latency bottlenecks in ML systems.
GPU Sharing and Container Device Interface in Kubernetes Device Plugins
Dive into GPU resource management in Kubernetes, exploring Container Device Interface (CDI), device plugin architecture, and various GPU sharing mechanisms for optimized AL/ML workload performance.

Integrating S3 into Distributed Multi-Protocol Hyperscale NAS
Discover how to seamlessly integrate S3 data silos into high-performance parallel file systems for GPU computing, AI/DL workflows using standard enterprise infrastructure and multi-protocol storage solutions.