Architecture Analysis for ETL Processing - CPU vs GPU
Explore GPU acceleration for ETL operations, comparing CPU and GPU architectures. Learn about performance gains in database operations and SQL query acceleration using GPUs.
Recent Advances in Optimization Solvers within JuliaSmoothOptimizers
Explore cutting-edge nonlinear optimization solvers in JuliaSmoothOptimizers. Learn about new packages, performance enhancements, and flexible implementations for large-scale problems using high-level linear algebra and automatic differentiation.
News from the Embedded Graphics Space
Explore the evolving embedded GPU landscape, including new standards, hardware changes, and software ecosystem demands, with insights on Linux support and driver comparisons.
Building Cost-Effective Homelabs for AI Workloads - A Practical Guide
Discover practical insights for building budget-friendly AI homelabs, from hardware choices to workflow optimization. Learn from 7 years of hands-on experience in running AI workloads efficiently at home.
Computational Modelling of Growth and Response of Multicellular EMT6/Ro Spheroids to Multi-Fraction Irradiation
Explore computational modeling of EMT6/Ro spheroid growth and response to multi-fraction irradiation, enhancing understanding of cancer dynamics and potential therapeutic improvements.
Choreography vs Orchestration in Serverless Microservices
Explore microservice interaction patterns: choreography vs orchestration. Learn pros, cons, and tools for each approach, with demos and a case study on combining both methods.
Code Reflection in Action - Translating Java to SPIR-V
Explore Java-to-SPIR-V translation using Babylon's code reflection API for GPU execution. Learn about parallel compute workloads and graphics libraries implementation.
Project Babylon - Code Reflection Update
Project Babylon extends Java's capabilities with code reflection, enabling analysis and transformation of Java code into foreign programming models like GPU programs.
How to Make Your Electrons Do More in Java - Vector API and TornadoVM
Explore Vector API in Java and TornadoVM for GPU/FPGA computing. Enhance processing power and performance through advanced JVM techniques and native-code tooling.
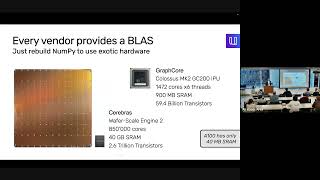
Fantastic Data Science Libraries and Where to Use Them
Discover high-performance alternatives to popular data science libraries, exploring GPU acceleration, distributed computing, and optimization techniques for faster data processing in Python.
Journey of Heterogeneous Computing in OpenInfra - From OpenStack Cyborg to AI Integration
Explore the 7-year evolution of OpenStack Cyborg's heterogeneous framework, from its community-driven inception to its role in AI infrastructure, and discover its impact on modern computing landscapes.
vLLM Inference and LLM Server Engine for Machine Learning
Discover how to leverage vLLM for efficient large language model inference and serving, including practical implementation techniques and deployment strategies.
Dynamic Scaling of GPUs for Container Apps with Composable Disaggregated Infrastructure for AI Era
Explore dynamic GPU scaling in containerized environments using Composable Disaggregated Infrastructure (CDI), focusing on efficient resource allocation and energy optimization for AI workloads.
Exploring Distributed Caching for Faster GPU Training with NVMe, GDS, and RDMA
Discover how to optimize GPU training performance through distributed caching techniques, leveraging NVMe storage, GDS, and RDMA networks for enhanced data access and reduced GPU wait times.
Optimize Your AI Cloud Infrastructure: A Hardware Perspective
Dive into hardware-level optimization techniques for AI cloud infrastructure, exploring GPU clusters, NUMA topology, and performance tuning strategies using H100 clusters and MLPerf benchmarks.
Ray Tracing for Adreno GPUs on Turnip - Building Bounded Volume Hierarchy Trees
Dive into GPU ray tracing acceleration with Turnip, exploring BVH tree construction and implementation challenges for Qualcomm's Snapdragon 8 Gen 2 Adreno GPUs.
Vulkan 1.3 Support for Apple M1 with Advanced Graphics Features
Dive into advanced Vulkan 1.3 implementation on M1, exploring geometry shaders, tessellation, and transform feedback with practical demonstrations and technical insights.
Procedural Content Generation: Advanced Topics and New Features in Unreal Engine 5.5
Dive into advanced Procedural Content Generation techniques, exploring attributes, multi-data processing, grammars, and GPU computation in Unreal Engine 5.5's latest framework updates.
Meeting the Demands of Modern Datacenters - AI Computing and Efficiency with AMD
Discover how AMD's innovative solutions address modern datacenter challenges through AI integration, compute density, and power efficiency while maximizing performance and automation capabilities.
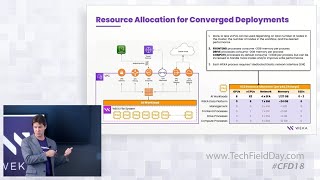
WEKA Converged Mode for AWS - Resource Efficiency for AI Workloads
Discover how WEKA's innovative Converged Mode optimizes GPU-accelerated workloads and AI model training in AWS, improving resource efficiency and performance for cloud deployments.
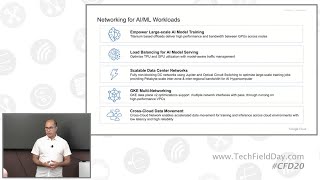
Google Cloud Network Infrastructure for AI and Machine Learning
Discover how Google Cloud's advanced network infrastructure enables efficient AI/ML workloads through dual-network architecture, hardware acceleration, and intelligent load balancing for optimal performance and scalability.