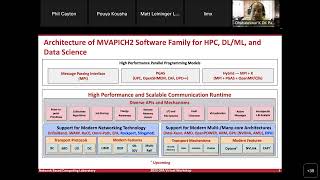
High Performance Scalable Support for Big Data Stacks with MPI - Leveraging MPI4Spark and MPI4Dask
Discover how MPI4Spark and MPI4Dask enhance big data frameworks by leveraging high-speed networks and HPC systems for improved performance and scalability in distributed computing environments.
iCheck - Leveraging RDMA and Malleability for Application-Level Checkpointing in HPC Systems
Discover how RDMA and malleable multilevel checkpointing can enhance HPC system reliability through iCheck framework, offering improved performance and efficient data transfer mechanisms for supercomputing applications.
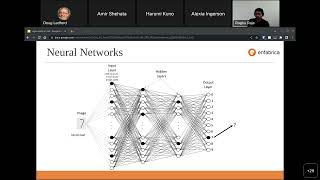
Designing Networking Stacks for Machine Learning Frameworks
Dive into networking stack design for machine learning frameworks, exploring challenges, solutions, and real-world applications through NCCL case studies and prototype implementations.
Infrastructure Software for Hyperscale AI and GPU Clusters
Explore cutting-edge infrastructure software solutions powering large-scale AI operations and GPU cluster management for hyperscale computing environments.
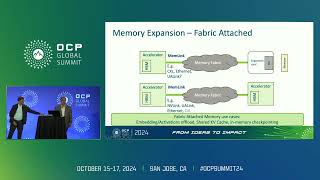
Memory Expansion Requirements for AI Systems in Hyperscale Data Centers
Explore evolving memory architecture requirements for AI systems in hyperscale data centers, focusing on GPU acceleration and infrastructure optimization for next-generation applications.
Accelerator Clusters: The New Supercomputer
Discover how accelerator clusters are revolutionizing supercomputing through NVIDIA's innovative approach to high-performance computing architecture and interconnect technologies.
Open Fabrics Interfaces Libfabric Tutorial
Discover the fundamentals of Open Fabrics Interfaces Libfabric, exploring its architecture, implementation, and practical applications in high-performance networking environments.
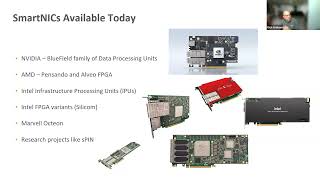
Leveraging SmartNICs for HPC and Data Center Applications - Part 1
Discover how SmartNICs revolutionize high-performance computing and data center operations, exploring key implementation strategies and performance optimization techniques for modern infrastructure.
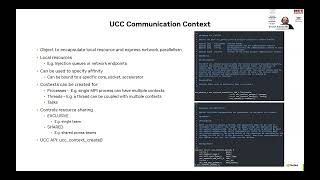
Unified Collective Communication - A Library for CPU, GPU, and DPU Integration
Explore the innovative Unified Collective Communication library that seamlessly integrates CPU, GPU, and DPU communication, enhancing performance across diverse computing architectures.
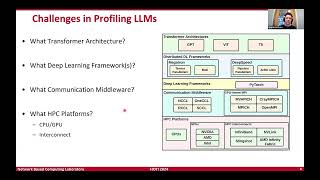
Demystifying the Communication Characteristics for Distributed Transformer Models
Explore communication patterns and optimization strategies for distributed transformer models, focusing on collective operations and performance characteristics in large-scale deployments.
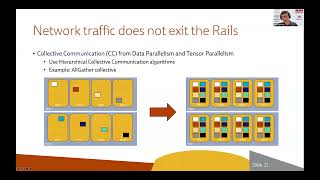
Rail-only: A Low-Cost High-Performance Network for Training LLMs with Trillion Parameters
Discover a groundbreaking network architecture designed for efficient training of large language models, optimizing performance while reducing infrastructure costs.
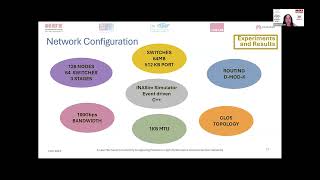
A New Mechanism to Identify Congesting Packets in High-Performance Interconnection Networks
Discover innovative techniques for identifying network congestion through advanced packet tracking mechanisms in high-performance interconnection systems.
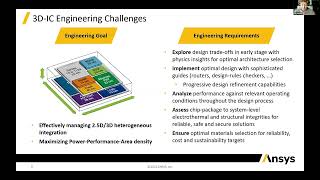
Signal Integrity Analysis for 2.5D/3D IC Technology in the Interposer Era
Delve into signal integrity analysis challenges and solutions for 2.5D/3D IC technology, focusing on silicon interposers, electromagnetic simulation, and advanced packaging architectures.
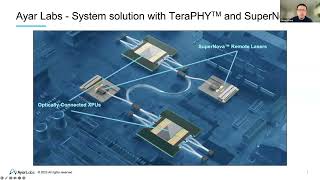
Silicon Photonics Chiplet Package - Optical Assembly and Integration Technologies
Explore cutting-edge packaging technologies for silicon photonics chiplets, focusing on optical components, assembly processes, and future high-performance computing applications.
Sharing is Caring - Fractional GPU Allocations with MetaGPU Device Plugin
Discover how to optimize GPU resource allocation in Kubernetes using MetaGPU Device Plugin, enabling fractional GPU sharing and efficient scheduling for enhanced cluster performance.
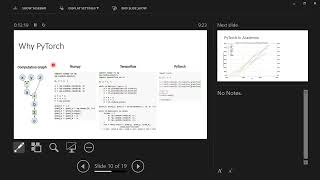
PyTorch Tutorial: Deep Learning Framework Fundamentals - Fall 2022
Master PyTorch fundamentals and deep learning concepts, from tensor operations to GPU acceleration, autograd, and data loading - all through hands-on coding examples and practical implementations.
How to Build and Scale Ultra-Lean Gen AI Startups
Discover proven strategies for building lean, high-performing AI startups through real-world success stories, focusing on blending human creativity with AI-driven productivity to achieve million-dollar revenues.
Что я хотел бы знать об MLOps год назад - Практический опыт внедрения Machine Learning
Discover essential MLOps insights through real-world experiences at Kolesa Group, covering ML model deployment, Docker, Kubernetes integration, and practical monitoring strategies for machine learning systems.
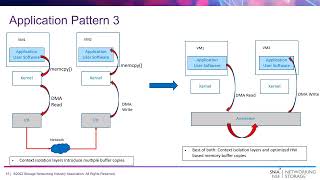
Memory Semantics and Data Movement with CXL and SDXI - Standards and Applications
Explore memory semantics and data movement standards through CXL and SDXI technologies, focusing on accelerator-assisted operations and heterogeneous computing architectures.

Kinetic Campaign: Speeding Up Scientific Data Analytics with Computational Storage
Discover how computational storage technologies and erasure coding enhance scientific data analytics performance, focusing on LANL's Campaign storage system and Seagate Kinetic Drives implementation.
Fast Deep Learning with Categories
Explore GPU-accelerated deep learning using Haskell, ConCat, and Accelerate for high-performance industrial applications.