Journey of Heterogeneous Computing in OpenInfra - From OpenStack Cyborg to AI Integration
Explore the 7-year evolution of OpenStack Cyborg's heterogeneous framework, from its community-driven inception to its role in AI infrastructure, and discover its impact on modern computing landscapes.
vLLM Inference and LLM Server Engine for Machine Learning
Discover how to leverage vLLM for efficient large language model inference and serving, including practical implementation techniques and deployment strategies.
Leveraging Ultra Ethernet Consortium for Next Generation AI Networks
Discover how Ultra Ethernet features enable next-generation AI networks, exploring advanced transport protocols and architectural innovations for enhanced network performance.
Possibility of Dynamic Rebalance in Multi-node HPC Vehicle Environment for SDV
Explore dynamic rebalancing strategies for Software-Defined Vehicles (SDV), focusing on edge orchestration challenges and solutions in multi-node HPC environments with mixed-criticality systems.
Dynamic Scaling of GPUs for Container Apps with Composable Disaggregated Infrastructure for AI Era
Explore dynamic GPU scaling in containerized environments using Composable Disaggregated Infrastructure (CDI), focusing on efficient resource allocation and energy optimization for AI workloads.
How to Extend AD/ADAS Sensors Accessibility to IVI Domain in the Software Defined Vehicle Era
Explore high-performance computing in software-defined vehicles, focusing on device sharing concepts, architectural requirements, and implementation strategies for multiple SoCs and sensor accessibility.
Exploring Distributed Caching for Faster GPU Training with NVMe, GDS, and RDMA
Discover how to optimize GPU training performance through distributed caching techniques, leveraging NVMe storage, GDS, and RDMA networks for enhanced data access and reduced GPU wait times.
Optimize Your AI Cloud Infrastructure: A Hardware Perspective
Dive into hardware-level optimization techniques for AI cloud infrastructure, exploring GPU clusters, NUMA topology, and performance tuning strategies using H100 clusters and MLPerf benchmarks.
Ray Tracing for Adreno GPUs on Turnip - Building Bounded Volume Hierarchy Trees
Dive into GPU ray tracing acceleration with Turnip, exploring BVH tree construction and implementation challenges for Qualcomm's Snapdragon 8 Gen 2 Adreno GPUs.
Vulkan 1.3 Support for Apple M1 with Advanced Graphics Features
Dive into advanced Vulkan 1.3 implementation on M1, exploring geometry shaders, tessellation, and transform feedback with practical demonstrations and technical insights.
Procedural Content Generation: Advanced Topics and New Features in Unreal Engine 5.5
Dive into advanced Procedural Content Generation techniques, exploring attributes, multi-data processing, grammars, and GPU computation in Unreal Engine 5.5's latest framework updates.
IBM Storage Scale - A Global Data Platform for High-Performance Unstructured Data Management
Discover IBM Storage Scale's capabilities for high-performance data management, featuring policy-based lifecycle control, multi-protocol connectivity, and flexible deployment across core, edge, and cloud environments.
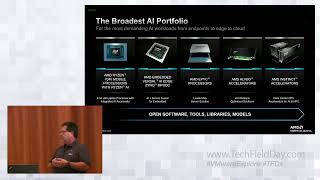
Meeting the Demands of Modern Datacenters - AI Computing and Efficiency with AMD
Discover how AMD's innovative solutions address modern datacenter challenges through AI integration, compute density, and power efficiency while maximizing performance and automation capabilities.
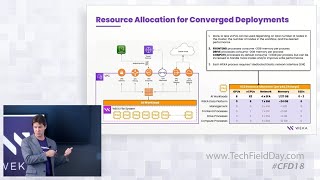
WEKA Converged Mode for AWS - Resource Efficiency for AI Workloads
Discover how WEKA's innovative Converged Mode optimizes GPU-accelerated workloads and AI model training in AWS, improving resource efficiency and performance for cloud deployments.
Quantum Myriad - All-Flash Scale-Out Storage Architecture
Discover how Quantum Myriad's innovative all-flash scale-out storage system leverages microservices, Kubernetes, and NVMe optimization to deliver high-performance storage solutions for video and HPC workloads.
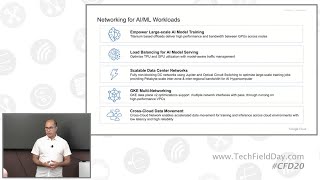
Google Cloud Network Infrastructure for AI and Machine Learning
Discover how Google Cloud's advanced network infrastructure enables efficient AI/ML workloads through dual-network architecture, hardware acceleration, and intelligent load balancing for optimal performance and scalability.
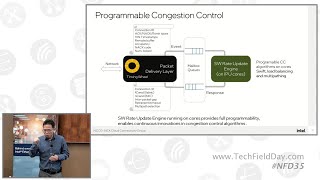
Reliable Transport of Lossy Fabrics with Falcon - A Low Latency Hardware Solution
Discover how Falcon enables reliable RDMA messaging and NVMe commands across cloud networks, optimizing performance for AI/ML, HPC, and storage workloads with low-latency transport.

Demystifying AI and ML Infrastructure for Network Engineers
Discover how to build and optimize GPU clusters for AI workloads, focusing on inter-GPU networking, efficient communication protocols, and practical implementation using Cisco's infrastructure solutions.
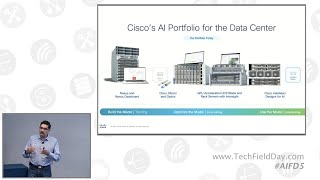
Kickstart AI in Your Data Center with Cisco Validated Designs
Discover how to efficiently deploy AI infrastructure using Cisco's validated designs, optimized hardware stacks, and partner integrations for seamless enterprise-scale AI implementation and workload management.
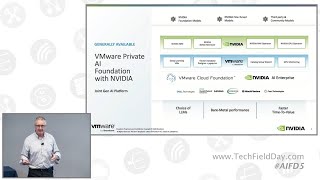
VMware Private AI Foundation with NVIDIA - Technical Overview and Demo
Discover how VMware's Private AI Foundation with NVIDIA streamlines AI development through automated infrastructure management, RAG capabilities, and simplified GPU resource allocation for enterprise applications.
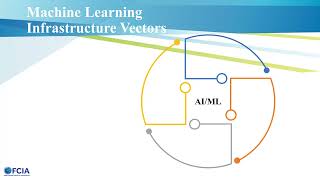
Benefits of FC-NVMe for Containerized Machine Learning Models
Discover how FC-NVMe optimizes containerized machine learning models, exploring Docker fundamentals, ML storage requirements, and performance benefits for efficient model training and deployment.