The Best Multicore-Parallelization Refactoring You've Never Heard Of
Discover a powerful, lesser-known refactoring technique for optimizing multicore parallelization in software development.
Immutable Arrays Help Mutating Arrays More Efficiently - ML'23 Lecture
Explore how immutable arrays enable compiler optimizations for efficient implementations, challenging intuitions about low-level control in array computations.
A Tale of Shared Memory Concurrency in Programming Languages
Explore shared memory concurrency in programming languages, examining challenges, recent advancements, and future directions for designing effective concurrency models for multicore systems.
Comparing Elixir and Python for Simple Neural Networks
Compare Elixir's Nx library with Python's machine learning ecosystem for training neural networks. Explore development experiences and performance differences using MNIST and CIFAR-10 datasets.
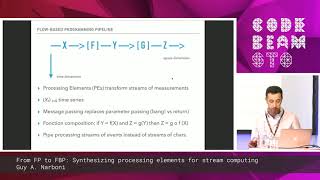
From FP to FBP: Synthesizing Processing Elements for Stream Computing
Explore Flow-Based Programming in Erlang, learning to design dataflow graphs and generate code for stream computing. Synthesize processing elements from functional blocks for efficient parallel data processing.
C++ for Multi-Accelerator, Multi-Vendor Systems - Meeting C++ 2022
Explore SYCL for C++ development on multi-accelerator systems. Learn basics, see demos, and discover how companies and institutions leverage this open-source, cross-device solution.
C++ Standard Parallelism - Portable Parallel Programming Across Platforms
Explore C++ Standard Parallelism: write portable parallel code for diverse hardware platforms. Learn about common algorithms, custom algorithm creation, and task graph composition.
Breaking Enigma with the Power of Modern C++
Explore Enigma machine encryption cracking using modern C++ and multicore CPUs. Learn historical context and benchmark performance of contemporary cryptanalysis techniques.
Optimizing Multithreading Performance - False Sharing and Hardware Destructive Interference
Explore false sharing and hardware destructive interference to optimize multithreaded performance. Learn strategies to mitigate cache-related bottlenecks and improve efficiency in C++ applications.
Advanced SIMD Algorithms in Pictures
Explore non-trivial SIMD algorithms like strcmp, set_intersect, and sort through visual explanations. Demystify vectorized algorithms for those with basic CS knowledge.
A Smooth Introduction to SYCL for C++20 Aficionados
Explore SYCL for cross-platform accelerator programming in C++20. Learn integration techniques, key features, and real-world applications in high-energy physics.
CUDA and the Wolfram Language: Latest Developments and Future Directions
Explore CUDA integration in Wolfram Language, covering latest developments and future directions for massively parallel GPU computation.
Building Autosuggest Infrastructure for High-Performance E-commerce
Explore OTTO's journey in building and reinventing autosuggest infrastructure, covering deep technology, architecture, scalability, and team insights for high-performance e-commerce solutions.
A Cheap Trick for Semantic Question Answering for GPU-Challenged Systems
Explore a cost-effective approach to semantic question answering using LLMs during indexing, combining text and vector matching for efficient search without GPU requirements.
Distributed Training: Techniques and Strategies - Part II - Lecture 18
Explore advanced distributed training techniques for machine learning, focusing on efficiency and scalability in large-scale AI systems.
Distributed Training for Efficient Machine Learning - Part II - Lecture 18
Explore advanced distributed training techniques for machine learning, focusing on efficiency and scalability in large-scale systems.
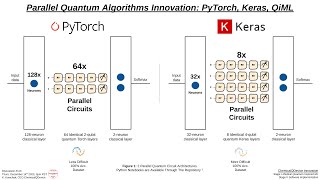
Parallel Quantum Algorithms Innovation: PyTorch, Keras, and QiML
Explore parallel quantum algorithms for machine learning using PyTorch and Keras. Enhance model accuracy and efficiency by incorporating quantum layers in neural networks.
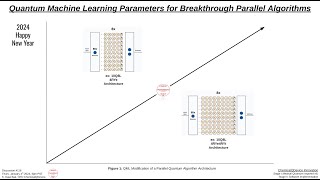
Quantum Machine Learning Parameters for Breakthrough Parallel Algorithms
Explore breakthrough parallel quantum algorithms for machine learning, improving performance and efficiency. Learn key benefits and optimal parameter settings for quantum-classical hybrid models.
Parallel Algorithms for Local Problems in Sparse Graphs
Explore efficient parallel algorithms for locally checkable problems in sparse graphs, focusing on techniques beyond graph sparsification for improved performance in sublinear regimes.
Molly.jl - Molecular Dynamics in Julia
Explore Molly.jl for molecular dynamics simulations in Julia. Learn about its features, advantages, and applications in research, including differentiable molecular simulation and force field improvement.
Towards QMCPACK v4
Explore advancements in quantum Monte Carlo simulations with QMCPACK v4, focusing on new features and improvements for computational materials science research.