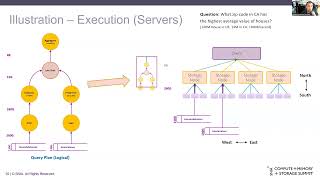
Decomposing Compute to Grow Computational Storage - Dynamic Query Partitioning in Storage Systems
Explore dynamic query partitioning in computational storage systems and learn how decomposable queries can optimize performance across storage device hierarchies for enhanced data processing capabilities.
Kata Containers 4.0 - Full Lifecycle GPU Management for AI/ML Workloads
Discover how Kata Containers 4.0 revolutionizes GPU management for AI/ML workloads through CDI framework integration, enhanced security features, and streamlined resource allocation in Kubernetes environments.
Improving the World's Slowest Raytracer - RADV Implementation Progress
Dive into the evolution of RADV's raytracing implementation, exploring performance improvements, compatibility expansions, and current capabilities in Mesa 23.2's graphics rendering system.
Reducing Stutters with Uber Shaders in Zink - OpenGL Driver Optimization
Discover how uber shaders optimize Zink's OpenGL driver performance by eliminating shader compilation delays and improving pipeline state handling for smoother graphics rendering.
Cross-Architecture Dynamic Migration Solution for Heterogeneous AI Acceleration Systems
Discover a unified solution for seamless application migration across diverse AI accelerators, enabling cross-architecture compilation and dynamic runtime adaptation without code modifications.
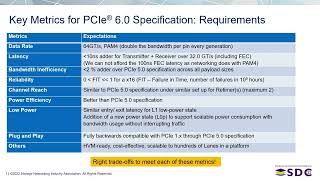
PCIe 6.0 Specification and Beyond - Enabling Storage for Machine Learning Applications
Explore PCIe 6.0's groundbreaking features and their impact on AI/ML applications, including PAM4 signaling, error correction, and flit-based encoding for enhanced data center performance and future developments.
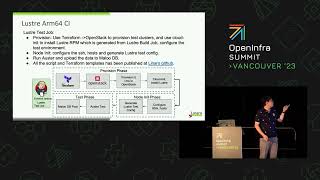
HPC Storage Solutions and Performance Optimization for Arm64 Architecture
Dive into high-performance computing storage optimization for Arm64 architecture, covering Lustre, DAOS, Ceph, and BeeGFS implementations, with focus on functionality, stability, and performance enhancements.
Deploying and Managing Baremetal Kubernetes with Ironic
Discover how G-Research leverages Ironic to automate baremetal Kubernetes deployment, managing hardware provisioning, security compliance, and firmware updates across multiple datacenters for efficient HPC operations.
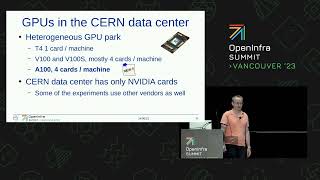
Multi-Instance GPU Deployment for Machine Learning and Particle Beam Simulations at CERN
Explore CERN's implementation of Multi Instance GPU technology using NVIDIA A100s, covering deployment strategies, virtualization approaches, and practical applications in machine learning and particle physics.
Intelligent Architectures for Intelligent Machines - Data-Centric Computing Systems
Explore modern computing architecture challenges and innovative solutions for data-centric design, focusing on machine learning acceleration, in-memory operations, and 3D-stacked memory technology.
Sokovan - Container Orchestrator for Accelerated AI/ML Workloads and Massive Scale GPU Computing
Discover how Sokovan optimizes AI/ML workloads through intelligent container orchestration, featuring dual-layer scheduling and hardware acceleration integration for enhanced GPU computing performance.
Lessons Learned in Ceph Operations for Science at CERN - From 3PB to 100PB
Discover how CERN scaled Ceph from 3PB to 100PB across data centers, exploring operational challenges, performance improvements, and essential lessons for large-scale storage implementation.
Data Platform for End-to-End AI Democratization
Explore how data platforms enable AI democratization through unified processing and training architectures, improving efficiency for recommender systems and deep learning workloads.
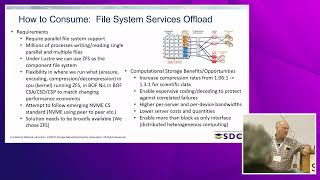
HPC Scientific Simulation and Computational Storage for Large-Scale Data Management
Explore how Los Alamos revolutionizes scientific data management using NVME Computational Storage, featuring proof-of-concept applications and industry partnerships for large-scale data solutions.

HDD Computational Storage Performance Analysis and Benchmarking - From System Tests to IPC
Dive into computational storage benchmarking techniques, exploring IPC analysis, SIMD programming, and inline assembler for optimizing genomics research performance on HDD systems.
Introducing CXL 3.0 - Expanded Capabilities for Scale and Resource Optimization
Explore the next-gen CXL 3.0 technology's enhanced capabilities, including doubled bandwidth, improved memory pooling, multi-level switching, and advanced coherency features for high-performance computing workloads.
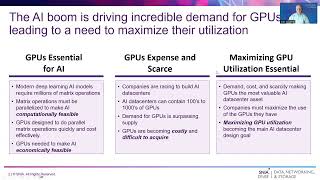
Storage Requirements for AI Infrastructure - From Data Preparation to Inference
Delve into the crucial role of storage systems across the AI lifecycle, from data preparation to inference, exploring performance requirements and infrastructure considerations for optimal GPU utilization.
Designing a Modern Object Store Server for Lustre File System
Dive into modern object store server design for Lustre file systems, exploring architectural improvements, storage innovations, and solutions for high-performance computing environments.
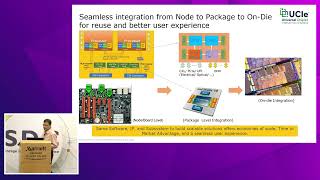
Universal Chiplet Interconnect Express (UCIe): Accelerating the Future of Semiconductor Innovations
Explore the Universal Chiplet Interconnect Express (UCIe) specification and its role in enabling modular semiconductor design through standardized chiplet connectivity and integration for next-gen computing systems.
Custom Chips Needed for Efficient High-Performance Computing
Explore the future of computing power through custom hardware solutions, from manycore systems to silicon development, addressing latency and energy efficiency challenges in high-performance computing.
Demolishing AI Gatekeepers - Breaking Down Barriers in AI Development
Explore how Web3 and decentralization can break Big Tech's monopoly on AI development by democratizing access to training data and GPU resources for unrestricted innovation.