Stable Diffusion 3.5 Large Tutorial - Configuration Guide and FLUX DEV Comparison
Master the optimal configuration and usage of Stable Diffusion 3.5 Large and FLUX DEV through SwarmUI, including model comparisons, LoRA implementation, and deployment across various computing platforms.
XLSTM: Understanding Extended LSTMs with sLSTM and mLSTM Architecture
Delve into the evolution of LSTM networks, exploring how XLSTM's innovative sLSTM and mLSTM components enable parallel processing and compete with transformers in sequence-related tasks.
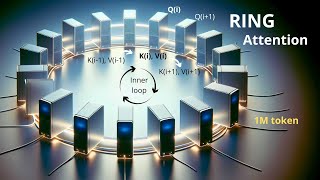
Ring Attention and Blockwise Transformers for Extended Context Length in Language Models
Dive into the technical mechanics of Ring Attention, exploring how it achieves million-token context lengths in large language models through blockwise parallel transformers and efficient implementation.
Rusticl OpenCL Implementation Status Update 2023
Discover the latest developments and implementations in Rusticl, exploring project updates and future outlook for this OpenCL implementation in Rust.
Mixture of Experts (MoE) in Large Language Models - A Simple Guide
Delve into the architecture and functionality of Mixture of Experts (MoE) systems in language models through clear examples and technical insights about token routing, gating networks, and computational efficiency.
Mistral 7B: Architecture, Performance and Implementation Guide
Dive into Mistral 7B's implementation, exploring grouped-query attention, efficient GPU usage, and hands-on demonstrations for running advanced language models on local hardware.
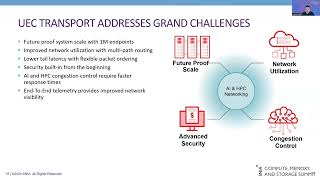
Ethernet Evolution: Powering AI's Future Through Ultra Ethernet Consortium
Discover how the Ultra Ethernet Consortium is revolutionizing network capabilities for AI and HPC, exploring technical innovations, enhanced performance metrics, and advanced RDMA solutions for next-gen computing.
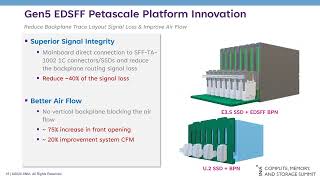
Storage Architecture Optimized for AI Workloads - High Performance Solutions for GPU Clusters
Discover how to optimize storage architecture for AI workloads, exploring high-performance solutions, capacity-optimized tiers, and real-world implementations for machine vision applications.
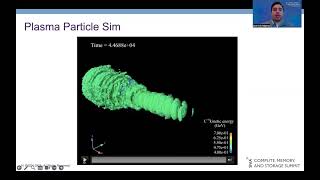
Streamlining Scientific Workflows - Computational Storage Strategies for HPC
Discover how computational storage strategies enhance scientific workflows in HPC environments, optimizing data processing for large-scale simulations and improving efficiency across I/O layers.
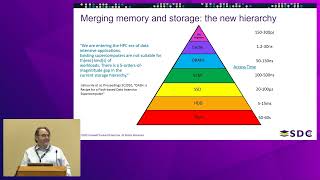
Fabric Attached Memory: Hardware and Software Architecture for HPC Systems
Explore hardware and software architecture of Fabric Attached Memory (FAM) in HPC clusters, focusing on large dataset management, CXL capabilities, and real-time analytics implementation using Arkouda.
PCIe 7.0 Specification - 128 GT/s Bandwidth for Future Data-Intensive Markets
Explore the next-generation PCIe 7.0 specification, featuring 128 GT/s transfer rates, PAM4 signaling, and enhanced power efficiency for advanced computing and data-intensive applications.
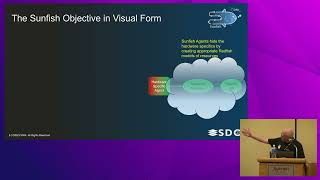
Sunfish Open Source Management for Composable Disaggregated Infrastructures
Explore how Sunfish project enables open-source management of composable infrastructures through industry standards, focusing on storage-centric use cases and fabric interconnect configuration for HPC environments.
SoC Construction Using Universal Chiplet Interconnect Express (UCIe) - A Game Changer
Explore the Universal Chiplet Interconnect Express (UCIe) standard and its revolutionary impact on SoC construction, chiplet integration, and high-performance computing applications.

QLoRA: Efficient Training of Large Language Models Using Quantization and Low-Rank Adaptation
Discover how QLoRA enables efficient training of large language models on a single GPU through innovative techniques like NormalFloat, Double Quantization, and Paged Optimizers.
Fine-tuning Flan-T5 LLM with HuggingFace Accelerate - Tutorial
Learn how to fine-tune Flan-T5 LLM using HuggingFace Accelerate for multi-GPU environments, with step-by-step guidance on preprocessing and implementation for specific downstream tasks.
Fine-tune T5 Language Model for Text Summarization on Google Colab
Master fine-tuning techniques for T5 language models using HuggingFace's latest code, focusing on text summarization tasks with hands-on implementation in Google Colab's free GPU environment.
ChatGPT vs Flan-T5: Comparing Proprietary and Free LLMs with Performance Tuning
Explore the differences between ChatGPT and Flan-T5 LLM models, comparing their capabilities, accessibility, and performance optimization through practical demonstrations and hyperparameter tuning techniques.
Reversible Pebbling - Parallel Quantum Circuits with Low Amortized Space-Time Complexity
Explore parallel quantum circuit construction through reversible pebbling games, focusing on efficient space-time complexity and quantum algorithm optimization for enhanced computational performance.
Heterogeneity-Aware Algorithms for Federated Learning and Distributed Optimization
Delve into advanced federated learning algorithms, focusing on heterogeneity challenges in distributed model training and innovative solutions for edge computing optimization.
Running BLOOM 176B LLM Inference with AWS ML and DeepSpeed
Dive into advanced LLM inference deployment using AWS's ml.p4de.24xlarge instance, exploring BLOOM 176B implementation with DeepSpeed and DJL for optimal performance and scalability.
Optimizing LLM Fine-Tuning with PEFT and LoRA Adapter-Tuning for GPU Performance
Master efficient fine-tuning of large language models using PEFT and LoRA techniques, optimizing GPU memory usage through INT8 quantization and adapter-tuning for cost-effective model development.