Introduction to Databricks Delta Live Tables
Accelerate data pipeline development with Databricks Delta Live Tables. Learn setup, ingestion, table creation, pipeline execution, and data validation for faster, more reliable projects.
What's New and Cool in Azure Synapse Analytics
Discover recent updates and new features in Azure Synapse Analytics for end-to-end analytics, with practical demonstrations and scenario-based applications.

Delta Live Tables - Building Reliable ETL Pipelines with Azure Databricks
Build fast, reliable, and scalable ETL pipelines using Delta Live Tables on Azure Databricks. Learn declarative approaches and see demos of simple and complex streaming pipelines.
Breaking Out of the Habit of Bulk Loading Everything - Lessons from Streaming Data Integration
Explore transitioning from bulk loading to streaming data integration, leveraging Azure services for real-time analytics and long-term storage in data warehousing.
Building Tomorrow's Warehouse Today - Modern Data Warehouse Modelling Insights
Explore fundamental shifts in data warehousing architecture and processing design principles for modern, efficient data management and analysis.
Building Stream Processing Applications with Ruby and Meroxa - RubyConf 2022
Explore real-time stream processing using Ruby and the Turbine framework. Learn to build and deploy sophisticated applications without complex tooling or unfamiliar paradigms.
Data Enrichment Patterns with Apache Flink
Explore common data enrichment patterns for streaming data using Apache Flink. Learn implementation techniques for static, API-based, and change data stream scenarios, with insights into Flink's state management.
Optimal Approaches for Real-Time Machine Learning with Apache Spark on Kubernetes
Explore optimal approaches for real-time machine learning using Apache Spark on Kubernetes, covering best practices for efficient model training, deployment, and serving in low-latency, high-scalability environments.
Data Symphony: Orchestrating Insights in Fintech
Explore the role of a Data Science Product Manager in Fintech, uncovering challenges and successes in leveraging data for strategic decision-making and product innovation at PayPal.
Orchestrating Scalable Data Pipelines with Apache Toree, YuniKorn, Spark, and Airflow
Explore integrated use of Apache Toree, YuniKorn, Spark, and Airflow for efficient, scalable data pipelines. Learn to leverage these projects for optimized data processing and workflow orchestration.
Efficient, Low Latency Ingestion to Large Tables via Apache Flink and Apache Iceberg
Learn efficient, low-latency data ingestion techniques using Apache Flink and Apache Iceberg for large tables. Explore integration challenges, performance optimizations, and comparisons with alternative solutions.
How to Pick the Best Data Transformation Strategy
Explore tools for combining data from multiple sources, including Azure Synapse, Spark, and Power BI Data Flows. Learn to select the optimal tool for your data environment.
Declarative ETL Pipelines with Delta Live Tables - Modern Software Engineering for Data Analysts and Engineers
Modernize ETL pipelines using Delta Live Tables for efficient data management. Learn development, production, and best practices for reliable, testable, and scalable data processing.
How to Create a High Performance Data Team - Lessons Learned from the Field
Discover key strategies for building and leading a high-performing data and analytics team, drawing from real-world experiences and proven methodologies.
Obtain, Distribute and Use Temporary Credentials Automatically in Apache Spark and Apache Flink
Learn to securely scale distributed data processing with automatic credential management in Apache Spark and Apache Flink. Explore common authentication challenges and solutions for high-load scenarios.
Understanding Stream-Table Duality Using Kafka, Flink SQL and Debezium Format
Explore stream-table duality using Kafka, Flink SQL, and Debezium format. Learn about CDC events, SQL queries on changelog data, and practical applications through a demo.
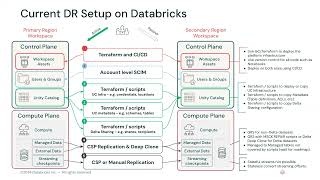
Business Continuity and Disaster Recovery on Databricks - Part 2: Implementation
Implement disaster recovery on Databricks Data Intelligence Platform, covering setup processes and upcoming features for enhanced business continuity.
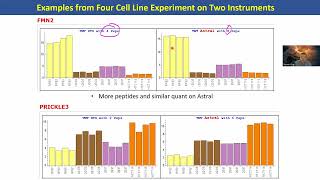
Targeted Pathway Proteomics Using TMT and Real-Time Analytics to Create GoDig Assays
Explore targeted pathway proteomics using TMT and real-time analytics for GoDig assays. Learn innovative techniques for hypothesis-driven research in systems biology.
ES|QL - Elasticsearch's New Query Language for Java Developers
Explore ES|QL, Elasticsearch's new query language combining SQL and Bash, for improved performance and seamless integration across Java and Kibana.
Apache Amoro - Exploring Community Operations from Zero
Discover how to build and operate open-source communities effectively through Apache Amoro's incubation journey, focusing on key strategies and best practices for community development.
Пирамида Потребностей Multitenant-системы: От Инженерных к Бизнес-решениям
Discover how YTsaurus evolved its big data platform automation, from basic infrastructure needs to advanced user-centric features, managing 20K+ hosts and 4.5K daily active users at Yandex.