Big Data Computing
Comprehensive exploration of big data technologies, covering Hadoop, Spark, key-value stores, streaming analytics, machine learning, and graph processing for large-scale data analysis and insights.
Building Data Infrastructure at Scale for AI/ML with Open Data Lakehouses
Explore how data lakehouse architecture with Apache Hudi supports real-world predictive ML and vector-based AI use cases in this 30-minute keynote by Vinoth Chandar, creator of Apache Hudi. Learn about ingesting data with minute-level freshness, providin…
Realtime Streaming for Anomaly Detection - An End-to-End Data Engineering Project
Build a real-time anomaly detection system using streaming data engineering techniques. Learn end-to-end implementation for monitoring and identifying unusual patterns in data streams.
Systematic Approaches and Creativity - Building DoorDash's ML Platform During the Pandemic
Explore DoorDash's ML platform development journey, focusing on collaboration, guardrails, principled approaches, and architecture powering billions of daily predictions for diverse use cases.
Building a CML Pipeline with Spark and Kafka - YOW! 2018
Explore building a CML pipeline using Apache Spark and Kafka. Learn functional programming techniques for efficient data processing and machine learning workflows.
The Who, What, and Why of Data Lake Table Formats
Explore data lake table formats, their creators, purposes, and significance in modern data architecture. Gain insights into optimizing data management and analytics.

How to Use Cloudera Data Platform
Comprehensive guide to Cloudera Data Platform, covering key components, features, and practical applications for data management, analytics, and machine learning in cloud environments.
Cloudera Certified Associate Spark and Hadoop Developer
Comprehensive training for Cloudera Certified Associate Spark and Hadoop Developer certification, covering Sqoop, Flume, HDFS, Spark, and Hive. Hands-on practice with real-world scenarios and data analysis techniques.
Spark Streaming Tutorial - Twitter Real Time Streaming - Apache Spark for Beginners
Apache Spark Streaming is a scalable fault-tolerant streaming processing system that natively supports both batch and streaming workloads. This video will help you to understand every aspect of Spark Streaming along with the examples and visuals for bett…

Apache Spark Full Course - Learn Apache Spark 2020
In this 'Spark Tutorial' you will comprehensively learn all the major concepts of Spark such as Spark RDD, Dataframes, Spark SQL and Spark Streaming.
Big Data Analytics for Beginners
Comprehensive introduction to big data analytics, covering key concepts like Hadoop, Apache Spark, and ETL. Ideal for beginners seeking to understand the landscape and value chain of big data.
Data Science Projects
Hands-on projects covering deep learning, machine learning, and data analysis. Practical applications in healthcare, finance, and more using Python, TensorFlow, and other tools.
PySpark with Python
Learn PySpark for big data processing: DataFrame operations, handling missing values, filtering, aggregations, MLlib basics, and Databricks integration. Includes linear regression implementation.
Spark Tutorials for Beginners
Learn Apache Spark fundamentals, including RDDs, SQL, streaming, and architecture. Hands-on tutorials cover setup, programming, and advanced concepts for big data processing.
Scala Tutorial
Comprehensive Scala programming tutorial for Spark developers and functional programmers, covering basics, concepts, and examples to prepare for Apache Spark development.
Apache Spark Tutorials
Learn Apache Spark's distributed computing capabilities, architecture, and programming with Scala. Explore DataFrames, SQL, data sources, and advanced features like Delta Lake for efficient big data processing.
Apache Spark 3 - Beyond Basics and Cracking Job Interviews
Advanced Apache Spark 3 skills for certification, job interviews, and complex scenarios. Covers architecture, memory management, optimization techniques, and performance tuning. Open to learner requests for additional topics.
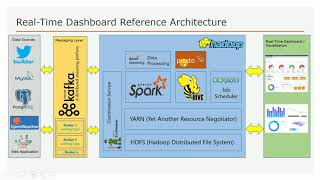
Apache Spark, Hadoop Project with Kafka and Python - End to End Development
Comprehensive big data project integrating Apache Spark, Hadoop, Kafka, and Python for end-to-end development, including streaming, REST API, and dashboard creation.
Machine Learning Using Spark MLLib
Learn to implement machine learning algorithms using Spark MLLib, covering linear regression techniques, data preprocessing, model building, and evaluation methods in a hands-on, practical approach.
Tech Talk - Top Tuning Tips for Spark 3.0 and Delta Lake on Databricks
Learn top tuning tips for Apache Spark 3.0 and Delta Lake on Databricks. Discover optimal join strategies, machine sizing, merge operation speedups, and job simplification techniques for enhanced big data processing.
Optimization for Reducing Compute Cost of SparkSQL in ByteDance
Discover key optimization techniques for SparkSQL implementation at ByteDance, focusing on compute cost reduction strategies and performance enhancement methods.