Bytedance's Parquet Format Optimization for Cost Reduction and Efficiency
Optimize Parquet file operations for big data efficiency. Learn binary copy techniques to enhance file overwriting, merge small files, and implement column-level TTL, boosting performance 10+ times.
Degrading Performance - Understanding and Solving Small Files Syndrome
Learn how small files impact data pipeline performance, understand cloud storage and Apache Spark interactions, and discover DeltaLake solutions for improved efficiency in handling massive datasets.
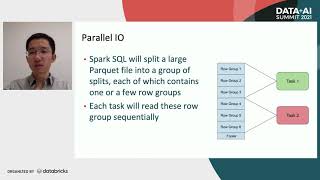
Optimizing Spark SQL Jobs with Parallel and Asynchronous IO
Optimizing Spark SQL jobs through parallel and async IO techniques, including file-level and row group-level parallel read, asynchronous spill, and parquet column family, resulting in 5-30% performance improvement.
Recent Parquet Improvements in Apache Spark - Vectorized Complex Types and Column Index Support
Explore recent improvements in Apache Spark's Parquet performance, including vectorized read support for complex types and column index support, leading to significant speed enhancements and efficient data processing.

The Parquet Format and Performance Optimization Opportunities
Explore Parquet format intricacies, columnar storage basics, and optimization techniques for Spark workloads. Learn about encoding, compression, predicate pushdown, and Delta Lake to enhance analytical performance.

The Apache Spark File Format Ecosystem - Optimizing Storage for Performance
Explore key file formats in Spark ecosystem: Parquet, ORC, Avro. Learn core concepts, optimization techniques, and how to select the right format for performant data processing and AI/ML workflows.
Building a Streaming Microservice Architecture with Apache Spark Structured Streaming
Explore building a scalable, fault-tolerant streaming microservice architecture using Apache Spark, Kafka, gRPC, and Delta Lake for real-time data processing and reliable insights.
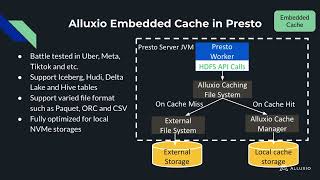
Caching Framework for Exabyte-Scale Data Lakes
Optimize exabyte-scale data lakes with open-source caching framework. Improve performance, reduce costs, and tackle challenges in complex data environments using Hadoop, Parquet, Hudi, and Alluxio.
Apache Arrow and Go: A Match Made in Data
Explore Apache Arrow's Go implementation, covering Arrow and Parquet libraries, Flight server/client, C Data API integration, and performance optimization techniques.
Introduction to DuckDB: An In-Process Analytical Database Management System
Discover DuckDB's powerful analytical database system, featuring in-process execution, multi-language support, and efficient data processing capabilities for handling large datasets on a single laptop.

DuckDB: Crunching Data Anywhere - From Laptops to Servers
Discover how DuckDB enables efficient data analysis across devices, from processing hundreds of gigabytes on laptops to terabytes on servers, with native support for SQL and popular file formats.
Sound Data Engineering in Rust - From Bits to DataFrames
Explore Rust for efficient data engineering, from low-level bit manipulation to high-performance DataFrames using Apache Arrow. Learn optimization techniques and benchmarks for improved data processing.
OLAP on Cassandra Data with Arrow, Flight SQL, ADBC, and DuckDB
Explore modern OLAP techniques for Cassandra data using Arrow, Flight SQL, ADBC, and DuckDB. Learn to convert sstable snapshots to Parquet, enable real-time analytics, and leverage Flight SQL for efficient querying.

Complete Python Pandas Data Science Tutorial - 2024 Updated Edition
Comprehensive tutorial on Python Pandas for data analysis, covering basics to advanced techniques. Learn to manipulate, filter, and aggregate data efficiently using the latest Pandas features and AI tools.

The Future Roadmap for the Composable Data Stack
Explore advancements in data processing with Wes McKinney. Learn about Parquet, Arrow, and interface libraries like Ibis and tidyverse. Gain insights into current project states and future innovations.
Implementing InfluxDB IOx Using Apache Arrow, DataFusion, and Rust
Discover how modern database systems are built using Apache Arrow, DataFusion, and Rust, exploring the architecture and implementation of InfluxDB IOx through deconstructed database approaches and open-source components.
Maximizing Real-Time Data Processing with Apache Kafka and InfluxDB - A Comprehensive Guide
Learn to create powerful data pipelines by combining Apache Kafka and InfluxDB for real-time processing, analysis, and visualization of large-scale data, especially in IoT applications.
How to Migrate from Snowflake to an Open Data Lakehouse Using Delta Lake UniForm
Explore Delta Lake UniForm's ability to create a single data set accessible across multiple open table formats, enhancing data lakehouse architecture efficiency and flexibility.

Microsoft Fabric Overview - Features, Benefits, and Use Cases
Explore Microsoft Fabric's powerful features for organizational data management, including OneLake, lakehouses, warehouses, and AI integration. Learn key benefits and use cases for data engineering and analysis.

Black Hat Europe 2024
Black Hat Europe 2024