Prestissimo: The Next Generation C++ Based Presto SQL Query Engine
Discover how Prestissimo revolutionizes Presto SQL engine with C++ runtime, delivering enhanced performance, efficient memory management, and improved CPU utilization through vectorization and runtime optimizations.
Presto on Apache Spark - A Tale of Two Computation Engines
Explore the integration of Presto and Spark, combining low-latency evaluation with robust execution for enhanced SQL experience in both interactive and batch use cases at Facebook scale.
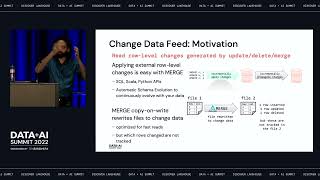
Delta Lake 2.0 Overview - New Features and Community Collaborations
Overview of Delta Lake 2.0 features, integrations, and community collaboration. Highlights include data skipping, Change Data Feed, column mapping, multi-cluster S3 writes, and support for various languages and platforms.
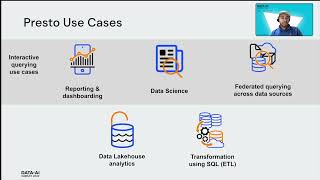
An Introduction to Open Source Presto
Explore Presto, a distributed SQL engine for data lake analytics. Learn its features, benefits, and use cases through an introduction and demo on AWS implementation.
Introducing Prestissimo: Presto's Next-Gen Query Execution Engine
Explore Prestissimo, Presto's new C++ query execution engine, offering improved performance, reliability, and efficiency for data analytics and open data lakehouses.
An Intro to Presto, the Open Source Distributed SQL Query Engine for the Data Lake
Explore Presto, an open-source distributed SQL query engine for data lakes. Learn its architecture, use cases, connectors, and performance benchmarking. Discover how Presto enables fast, scalable analytics on diverse data sources.

Compute Engine Testing with Synthetic Data Generation
Explore Meta's innovative testing framework using privacy-safe synthetic data for compute engines, enhancing regression detection, test coverage, and release cycles in data warehousing.
Performance Analysis of Apache Spark and Presto in Cloud Environments
Comparative analysis of Apache Spark and Presto on Amazon EMR, focusing on SQL performance using TPC-DS benchmark. Explores execution times, costs, and optimization techniques to guide big data analytics platform selection.

Introduction to Presto - The SQL Engine for Data Platform Teams
Explore Presto, a powerful SQL engine for data platform teams, and learn how it can enhance your data analytics capabilities and streamline query processing across diverse data sources.
How to Use Kubernetes to Build a Data Lake for AI Workloads
Learn to build a cloud-agnostic data lake using Kubernetes, Rook, and Ceph for AI workloads. Discover how to provide unified data access across multiple data centers for data scientists and developers.
Supercharged Analytics for Prometheus Metrics with Spark, Presto, & Superset
Explore advanced analytics for Prometheus metrics using Spark, Presto, and Superset. Learn to perform complex queries and join metrics with Kubernetes metadata for deeper insights.
Presto - Today and Beyond - The Open Source SQL Engine for Querying all Data Lakes
Explore Presto's architecture, use cases, and future developments as an open-source SQL engine for querying data lakes, with insights on performance, scalability, and reliability improvements.
Presto Open Source SQL Engine for Massive Scale Data Lakehouses
Explore Presto's capabilities for fast, scalable SQL analytics across diverse data sources. Learn how major companies leverage it and see a demo on AWS. Discover Presto's open-source success and future enhancements.
Building an Open Data Lakehouse on AWS with Presto and Apache Hudi
Learn to construct an open data lakehouse on AWS using Presto and Apache Hudi, combining data lake flexibility with data warehouse performance for efficient big data management.
Inserting Data into Hudi and Querying Your Hudi Table with Presto
Learn to insert data into Hudi tables and efficiently query them using Presto, enhancing your data management and analysis skills in distributed systems.
Data Caching for Enterprise-Grade Petabyte-Scale OLAP
Explores Alluxio local cache for petabyte-scale OLAP, optimizing data transfer efficiency in decoupled compute-storage models. Shares insights from Uber and Meta deployments.