Apache Arrow - El Formato Columnar Explicado
Explora Apache Arrow como formato columnar eficiente para análisis de datos, abordando diseños de memoria, tipos lógicos, serialización y estructuras avanzadas con ejemplos prácticos.
Streaming Featurization with Ibis, Substrait and Apache Arrow
Explore real-time streaming data processing using Ibis, Substrait, and Apache Arrow. Learn how this software stack enhances featurization workflows for fast, accurate insights and decision-making in data science.
AIUK 2022 Workshop - Raphtory: Real-Time Graph Analytics
Explore real-time graph analytics with Raphtory, covering social networks, time-based graphs, and advanced features like historical properties and query languages.
DataFusion and Apache Arrow: Supercharging Data Analytics with a Rust-Based Query Engine
Explore Rust, Apache Arrow, and DataFusion to accelerate modern data stacks. Learn implementation timelines, optimization techniques, and key features for efficient data analysis and querying.
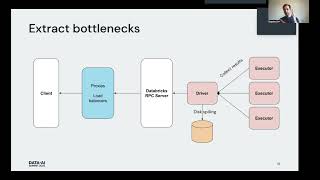
Cloud Fetch: High-Bandwidth Connectivity for BI Tools - Databricks
Explore high-bandwidth connectivity for BI tools using Cloud Fetch, a parallel data extraction mechanism that significantly speeds up query result retrieval from Databricks SQL endpoints.
Master Databricks and Apache Spark - SparkR Usage - Lesson 35
Explore SparkR for integrating R with Databricks and Apache Spark, covering architecture, APIs, libraries, and practical examples of data manipulation and analysis.
Data Science Across Data Sources with Apache Arrow - Accelerating Analytics and Interoperability
Explore Apache Arrow's columnar in-memory data representation for real-time analytics across distributed systems. Learn how it accelerates data processing and enables interoperability between various analytical tools and data sources.
Apache Arrow and the Future of Data Frames with Wes McKinney
Explore Apache Arrow's columnar data standard and its impact on data frame libraries, analytics systems, and cross-language collaboration in data processing and analysis.
Pandas 2, Dask or Polars? Quickly Tackling Larger Data on a Single Machine
Explore Pandas 2, Dask, and Polars for efficient large data processing on a single machine. Compare features, performance, and ecosystem compatibility to choose the best tool for your research workflow.
Apache Arrow and Go: A Match Made in Data
Explore Apache Arrow's Go implementation, covering Arrow and Parquet libraries, Flight server/client, C Data API integration, and performance optimization techniques.
Apache Arrow DataFusion: Vectorized Execution Framework for Maximum Performance
Explore Apache Arrow DataFusion's architecture, extension capabilities, and use cases for high-performance data processing and query execution using vectorized execution and Rust implementation.
Apache Arrow DataFusion - A Fast, Embeddable, Modular Analytic Query Engine
Explore Apache Arrow DataFusion's fast, embeddable, and modular analytic query engine capabilities with insights from expert Andrew Lamb.
Apache Arrow Optimization on Arm
Discover techniques for profiling and optimizing Apache Arrow on Arm platforms, including Top-down methodology, Arm SPE, and NEON. Learn to identify and resolve performance bottlenecks in complex workloads.
Sound Data Engineering in Rust - From Bits to DataFrames
Explore Rust for efficient data engineering, from low-level bit manipulation to high-performance DataFrames using Apache Arrow. Learn optimization techniques and benchmarks for improved data processing.
OLAP on Cassandra Data with Arrow, Flight SQL, ADBC, and DuckDB
Explore modern OLAP techniques for Cassandra data using Arrow, Flight SQL, ADBC, and DuckDB. Learn to convert sstable snapshots to Parquet, enable real-time analytics, and leverage Flight SQL for efficient querying.
Data Engineering with Rust and Delta Lake
Explore data engineering with Rust, leveraging Delta Lake, data fusion, and arrow for high-performance pipelines. Learn to ingest, enrich, manage, and export data using Rust's powerful capabilities.
Columnar Storage: Redefining Data Management for the Modern Era
Discover how columnar storage optimizes data warehousing through Apache Arrow, Parquet, and Pandas, improving query performance and reducing costs while enhancing analytics workflows.
Speed Up Data Access with PyArrow Apache Arrow - Data is the New API
Explore Apache Arrow's columnar memory format for fast, language-independent data access. Learn about PyArrow integration, performance benefits, and Apache Flight for analytics.
Polyglot Data with Python - Introducing Pandas and Apache Arrow
Explore polyglot data handling with Python using Pandas and Apache Arrow for efficient data exchange between ecosystems, improving performance and reducing file sizes.
SQLAlchemy as the Backbone of a Data Science Company
Explore SQLAlchemy's advanced features for data science, including Core API, Expression Language, and database migrations. Learn to scale relational models for handling billions of records efficiently.
Distributed Multi-GPU Computing with Dask, CuPy and RAPIDS
Explore distributed multi-GPU computing using Dask, CuPy, and RAPIDS. Learn to leverage GPU acceleration and distributed systems for faster, more efficient data processing and analysis.