
Effective Data Platforming with Open Source Tools for Faster Insights
Discover how to build robust data streaming platforms using Strimzi, Kafka, and other open-source tools on Kubernetes, while learning architectural best practices and solutions to common challenges.
Production AI at Scale: Cloudera's Journey in Building a Robust Inference Platform
Discover how Cloudera built a secure, scalable AI inference platform using Kubernetes and open-source projects, exploring architecture, performance optimization, and security implementation for production environments.
Operationalizing High-Performance GPU Clusters in Kubernetes - Lessons Learned from Training Databricks DBRX
Dive into advanced strategies for managing large-scale GPU clusters in Kubernetes, focusing on monitoring, health detection, and solving complex failure scenarios in LLM training environments.
Elastic Data Streaming: Autoscaling Apache Kafka on Kubernetes
Discover how to implement autoscaling for Apache Kafka on Kubernetes, exploring key features like auto-rebalancing, node pools, and tiered storage for optimal cloud-native deployment and cost efficiency.
Apache Gluten - Boosting Apache Spark Performance with Native Engines
Discover how Apache Gluten enhances Spark performance through native engine integration, optimizing data processing and analysis capabilities for improved efficiency.
Meituan's Journey with Apache Spark and Gluten
Discover how Meituan optimizes data processing with Apache Spark and Gluten, exploring performance improvements and real-world implementation strategies for large-scale data analysis.
SQL Support in Elasticsearch via Apache Calcite
Explore how Apache Calcite enables SQL support in Elasticsearch, covering implementation details and practical applications for enhanced data querying capabilities.
Build an AI App on Streaming Data with Azure Databricks SQL and Genie
Discover how to build AI-powered data workflows by integrating Azure Databricks SQL, Genie APIs, and Power BI for seamless data connectivity, governance, and natural language querying capabilities.
Adding MxN Streaming Support for Envoy External Processing Filter
Dive into advanced streaming capabilities with Envoy's external processing filter, exploring MxN body streaming implementation and its practical applications in data compression scenarios.
Building a ChatGPT RAG Data Pipeline with RisingWave Stream Processor and Vector Store
Discover how to build a real-time ChatGPT data pipeline using RisingWave stream processor, integrating Twitter feeds with vector embeddings for enhanced similarity search and RAG-based chatbot functionality.
Simplify Stream Data Processing with Declarative, Scalable Kubernetes Native Technologies
Discover how to implement efficient, cost-effective stream data processing using Kubernetes-native technologies while ensuring resilience and scalability in cloud-native environments.
Building RAG Applications: Speaking with Unstructured Data Using LangChain - Part 1
Dive into building a RAG application using Langchain, multiple LLMs, and vector stores to enable interactive conversations with unstructured data through a Streamlit interface.
How to Build a Cloud Native Data Lake with Open Source Technologies
Discover how to deploy a Kubernetes-based data lake using open source tools, from initial setup to running a complete prototype platform on your local machine.
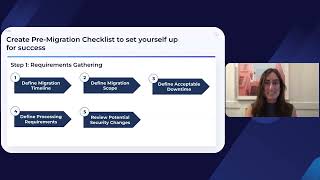
How to Migrate from Apache Kafka to Confluent Cloud with Limited Downtime
Learn essential steps and strategies for migrating from Kafka to Confluent Cloud while maintaining service continuity, with practical guidance on planning, setup, and validation processes.

Effective Data Platforming with Open Source Tools for Faster Insights
Discover how to build robust data streaming platforms using open-source tools like Strimzi, Kafka, and Confluent, while applying core software engineering principles for optimal architecture and performance.
Open Standards for Open Lakehouses - Understanding Apache Iceberg, Parquet, Arrow, and Nessie
Discover how open-source standards like Apache Iceberg and Nessie power data lakehouses, enabling flexible and cost-effective data platforms while minimizing vendor lock-in and data movement challenges.
Cloud Storage Considerations for RAG in AI Applications
Explore cloud object storage implementation in RAG systems, covering LLM-OS concepts, domain-specific data handling, and practical applications for building AI-powered solutions with vector databases.
Integrating Apache Arrow on WASM Using Component Model
Discover how to integrate Apache Arrow with WASM Component Model, exploring efficient data handling techniques and practical applications across IoT, robotics, and cloud infrastructure.
Object Storage Is All You Need - From Cloud Persistence to Modern Applications
Explore how object storage is evolving from simple web storage to a complete persistence solution, examining its benefits, performance aspects, and practical applications in modern cloud systems.
Drug Launch Success Through Prompt-Driven Sales Data Analytics
Discover how to optimize pharmaceutical drug launches through advanced sales analytics, predictive modeling, and real-time data processing for improved market performance and ROI.
Real-Time Data for Generative Feedback Loop Automation
Dive into real-time data automation with Generative Feedback Loops (GFL), exploring practical implementations, pipeline construction, and hands-on demonstrations for automated data processing systems.