Developer Transition: Machine Learning to Quantum Machine Learning
Explore quantum machine learning frameworks, tools, and resources to transition from classical ML. Gain insights into QML algorithms, simulators, and future developments in the field.
Challenges and Advancements in Speaker Diarization and Recognition for Naturalistic Data
Explore advancements in speech technology for analyzing human interactions, focusing on child learning spaces and NASA APOLLO missions. Gain insights into ML-based audio processing and diarization techniques.
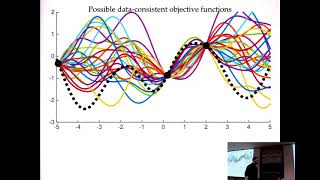
Better Science Through Better Bayesian Computation - 2015
Explore Bayesian computation for data analysis in science and engineering. Learn about Bayesian optimization and scalable Markov chain Monte Carlo techniques for improved hypothesis testing and decision-making.

Realtime Data Streaming - End-to-End Data Engineering Project
Build a real-time data streaming pipeline using Apache Airflow, Kafka, Spark, and Cassandra. Learn end-to-end data engineering, from ingestion to processing and storage, all containerized with Docker.
Realtime Socket Streaming with Apache Spark - End-to-End Data Engineering Project
Build a real-time data streaming pipeline using TCP/IP Socket, Apache Spark, OpenAI LLM, Kafka, and Elasticsearch. Process 7 million records for sentiment analysis and efficient data indexing.
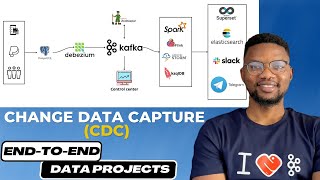
Realtime Change Data Capture Streaming - End-to-End Data Engineering Project
Implement real-time Change Data Capture streaming using Docker, Postgres, Debezium, Kafka, Apache Spark, and Slack. Create an efficient data pipeline for responsive data engineering projects.
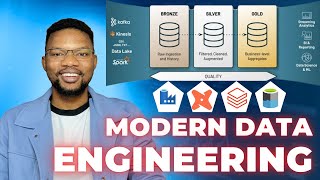
Building Robust Data Pipelines for Modern Data Engineering - End-to-End Project
Develop robust data pipelines using Apache Spark, Azure Databricks, and DBT. Master end-to-end data engineering with Azure, covering ingestion, integration, and transformation in a modern data architecture.
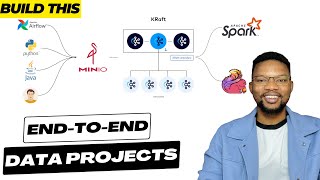
Realtime Streaming with Data Lakehouse - End-to-End Data Engineering Project
Design, implement, and maintain secure, scalable lakehouse architectures using Apache Spark, Kafka, Flink, Delta Lake, AWS, and open-source tools. Unlock data's potential through advanced analytics and machine learning.
Realtime Algorithmic Trading with Apache Flink - End-to-End Data Engineering Project
Develop an end-to-end algorithmic trading system using Apache Flink, Kafka, and Python. Learn real-time data processing, custom algorithms, and financial market insights.
Debezium - Building Streaming Data Pipelines with Change Data Capture
Explore Debezium's features for building streaming data pipelines using popular databases as sources, with a focus on Apache Kafka integration and alternative data sinks.
Migrate Your Kafka Cluster with Minimal Downtime
Learn strategies and tools for migrating Kafka clusters with minimal downtime. Explore MirrorMaker, Confluent Replicator, and Cluster Linking. Gain insights on planning, execution, and overcoming challenges in Kafka migration.
Kafka, Flink, and Beyond: Current Developments and Future Innovations in Data Streaming - 2023
Explore recent advancements, upcoming improvements, and innovative applications in Kafka and Flink data streaming. Gain insights from industry leaders on tiered storage, queues, use cases, and two-phase commit protocol.

Delta Live Tables: Building Reliable Data Pipelines with Databricks
Simplify ETL development with declarative pipelines, automatic testing, and deep visibility for reliable batch and streaming data on Databricks Lakehouse Platform.

Microsoft Fabric Overview - Features, Benefits, and Use Cases
Explore Microsoft Fabric's powerful features for organizational data management, including OneLake, lakehouses, warehouses, and AI integration. Learn key benefits and use cases for data engineering and analysis.
Empower an End-to-End Scalable and Interpretable Data Science Ecosystem Using Statistics, AI and Domain Science
Explore scalable, interpretable data science using statistics, AI, and domain expertise. Gain insights from Harvard professor Xihong Lin on analyzing complex genomic and health data.
Discovery in High Dimensions - 2008
Explore statistical methods for uncovering hidden structures in high-dimensional data from various fields, including genetics, astronomy, and consumer behavior.
Elevating Kubeflow Spark Operator's Future: Best Practices and Enhancements
Discover advanced techniques for deploying Apache Spark on Kubernetes using Kubeflow Spark Operator, covering scaling strategies, multi-tenancy management, security best practices, and efficient upgrade procedures.
How IoT Can Save a Life - A Real-World Example in Smart City Traffic Systems - OCX 2024
Explore real-world IoT applications in smart city infrastructure, focusing on collision detection systems that integrate traffic, public transport, and pedestrian data to enhance urban safety.
The Art of Omnichannel - Building Blocks for Crafting Connected Experiences
Discover how to architect seamless omnichannel experiences through real-time data collection, AI-driven decisioning, and multi-channel distribution strategies for creating personalized customer interactions.
Design Patterns for Running AI/ML and Big Data Workloads on Kubernetes
Explore essential design patterns and solutions for deploying AI/ML and big data workloads on Kubernetes, addressing challenges in container management, data handling, and system optimization.
Распределённое хранение и обработка больших данных
Dive into распределённое хранение и обработку больших данных с открытым ПО Яндекса, изучая методы отображения изменяемых таблиц на неизменяемые фрагменты для эффективной обработки данных.