Advancing GPU Analytics with RAPIDS Accelerator for Apache Spark and Alluxio
Learn to accelerate GPU analytics using RAPIDS for Apache Spark and Alluxio, enabling faster data access and processing for AI and analytics workloads across any cloud environment.
A Collaborative Data Science Development Workflow Using Kedro and MLflow
Explore a collaborative data science workflow using Kedro pipelines, MLflow tracking, and cloud-agnostic GPU containers for efficient model development, training, and production deployment.
Growing the Delta Ecosystem - Delta-RS for Rust and Python
Explore delta-rs, a Rust library extending Delta Lake beyond Spark. Learn its current capabilities, roadmap, and real-world application in kafka-delta-ingest for high-throughput data transfer.
Building Lakehouses on Delta Lake with SQL Analytics
Learn to build lakehouses using Delta Lake, perform SQL analytics, and connect BI tools. Explore data management techniques, governance models, and implementation examples for efficient data processing and analysis.
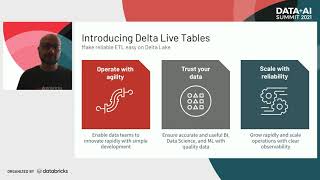
Make Reliable ETL Easy on Delta Lake
Learn to simplify ETL development on Delta Lake, improving data quality and scaling operations. Discover how Databricks streamlines the ETL lifecycle for efficient data engineering and management.
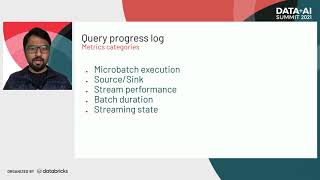
Delta Lake Streaming - Internals and Query Progress Logs
Explore Delta Lake streaming internals, focusing on structured streaming components, Query Progress Logs, and checkpoint directories for efficient real-time data pipeline management.
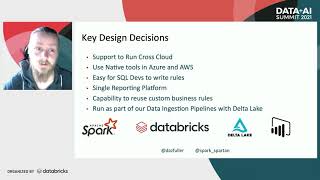
Building Data Quality Pipelines with Apache Spark and Delta Lake
Learn to build robust data quality pipelines using Apache Spark and Delta Lake. Explore rule templates, reporting models, and PowerBI integration for effective data remediation and self-healing in enterprise environments.
Why Lakehouse Architecture Now - Exploring Enterprise Data Warehouse Failures and the Need for Lakehouse Paradigm
Explore the shift from enterprise data warehouses to lakehouse architecture, focusing on benefits, challenges, and Starburst's role in powering SQL-based analytics on Delta Lake.
Creating a Lakehouse on AWS
Learn to build a Lakehouse on AWS, combining data lake affordability with data warehouse performance. Discover integration with AWS services and real-world examples of high-performance, cost-effective analytics solutions.
Building End-to-End Delta Pipelines on GCP
Explore building end-to-end Delta pipelines on GCP, covering data reliability, performance, and the Bronze-Silver-Gold architecture pattern, with practical code examples and Big Query integration.
Apache Spark, Data Science, and Machine Learning Advances - Data + AI Summit 2021 Keynote
Explore AI advancements, data science, MLOps, and Databricks Lakehouse Platform innovations. Featuring industry leaders and Bill Nye, this keynote covers MLFlow updates, AutoML, and practical machine learning solutions.
Boost Delta Lake Performance with Data Skipping and Z-Order
Explore data skipping and Z-ordering techniques to enhance Delta Lake performance, focusing on optimized partitioning strategies for improved read and write efficiency in large-scale data lakes.
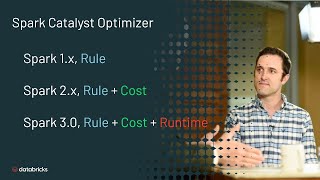
How Apache Spark 3.0 and Delta Lake Enhance Data Lake Reliability
Discover performance enhancements in Apache Spark 3.0 and Delta Lake's data reliability features. Learn about Adaptive Query Execution, Dynamic Partition Pruning, and handling skewed queries for improved big data processing.
Engagement Activity Delta Lake for Einstein Analytics and Sales Cloud Einstein
Explore how Salesforce built an engagement activity platform using Delta Lake to support Einstein Analytics and Sales Cloud Einstein, covering data ingestion, incremental reads, and mutation handling.
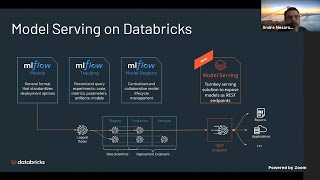
MLflow Model Serving - From Training to Production
Comprehensive overview of MLflow Model Serving, covering offline and online scoring, deployment options, and integration with Databricks, with practical examples and recent features.
Developing Scalable Machine Learning Pipelines for Gaming Industry
Explore scalable ML pipelines in gaming, leveraging Apache Spark for data-driven product development and improved user acquisition through advanced LTV modeling.
Accelerating MLOps with Apache Spark and SingleStore
Learn to accelerate MLOps using Apache Spark and SingleStore. Discover how to build fast analytical applications, manage supervised learning models, and scale AI/ML operations for data science success.
Cost Efficiency Strategies for Managed Apache Spark Service with Databricks
Explore cost-efficient strategies for Azure Databricks, including resource management, tier selection, and best practices for optimizing Apache Spark workloads in a managed cloud environment.
Migrating Airflow-Based Apache Spark Jobs to Kubernetes - The Native Way
Learn to migrate Airflow-based Apache Spark jobs to Kubernetes, reducing costs and improving stability. Explore challenges, best practices, and native Airflow integration for seamless transition from AWS EMR to K8s.
Scaling Machine Learning Feature Engineering in Apache Spark at Facebook
Explore advanced techniques for scaling ML feature engineering in Apache Spark, including Feature Injection and Feature Reaping, with optimizations for improved performance and efficiency at Facebook's scale.
Project Zen - Improving Apache Spark for Python Users
Discover improvements in Apache Spark for Python users, including redesigned documentation, type hints, PyPI distribution options, and enhanced PySpark features for a more Pythonic experience.